hermes-ai.netis an unofficial, independent community guide to Hermes Agent, with localized docs, release notes, desktop notes, and practical setup paths.
AC2 Beats GRPO on Math Proofs Using 2.5x Fewer Decoding FLOPs
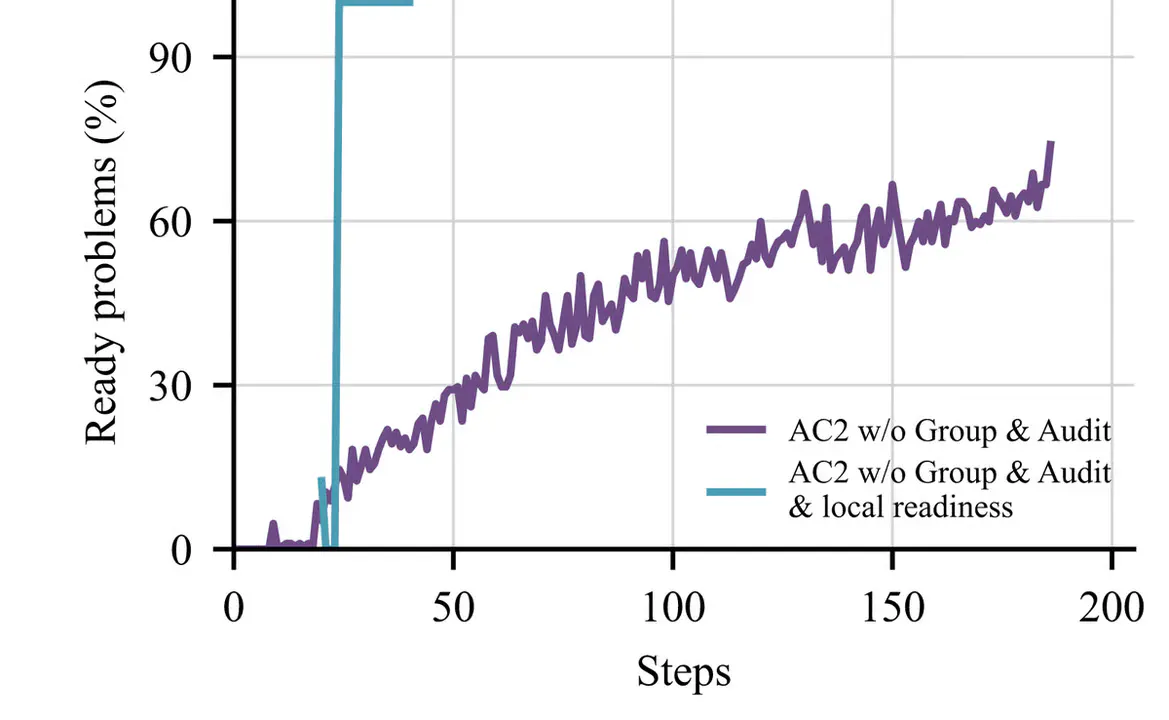
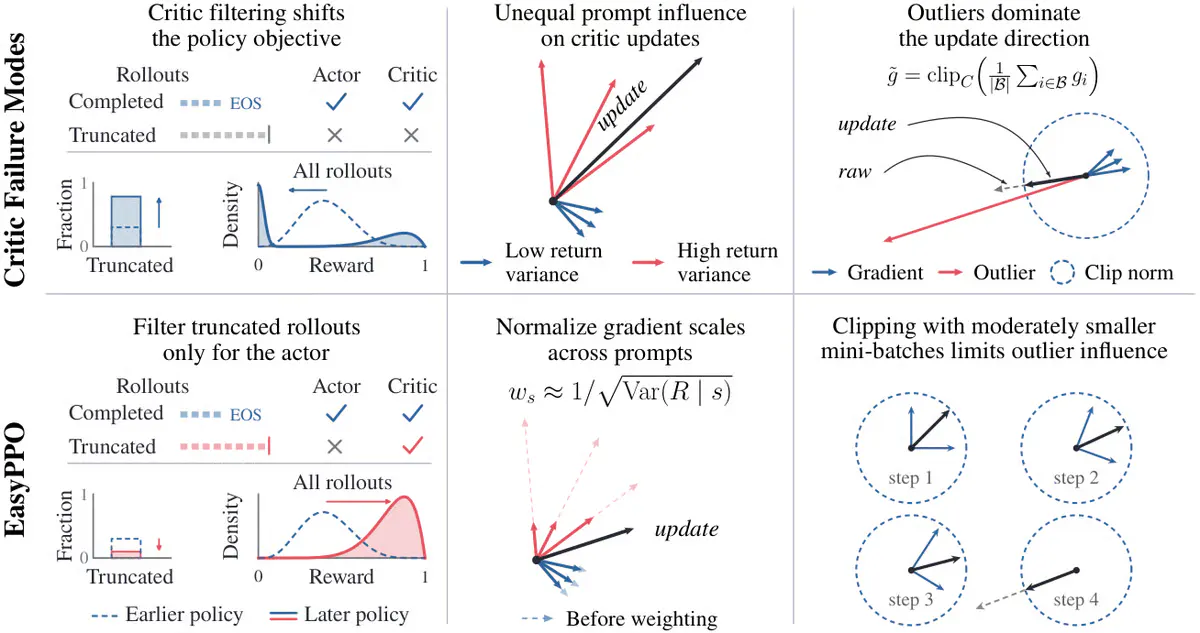
A new actor-critic recipe called AC2 trains LLMs on long reasoning tasks without rolling every trajectory to completion, hitting GRPO's peak with 2.5x fewer decoding FLOPs.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new actor-critic recipe called AC2 trains LLMs on long reasoning tasks without rolling every trajectory to completion, hitting GRPO's peak with 2.5x fewer decoding FLOPs.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.