
Together AI Fixes a Hidden Bias Crashing LLM Reinforcement Learning Training
A new additive correction called score centering removes the hidden drift that destabilizes off-policy RL when training and inference engines disagree.
hermes-ai.net
Read docs →A focused feed of models, agents, research and open-source releases for people building with AI.
A new additive correction called score centering removes the hidden drift that destabilizes off-policy RL when training and inference engines disagree.
Ten Claude Opus 5.5 agents collaborated on a message board for 15 hours to produce C-HD, a Lean-verified shortest-path algorithm that beats published bounds in a specific density regime.
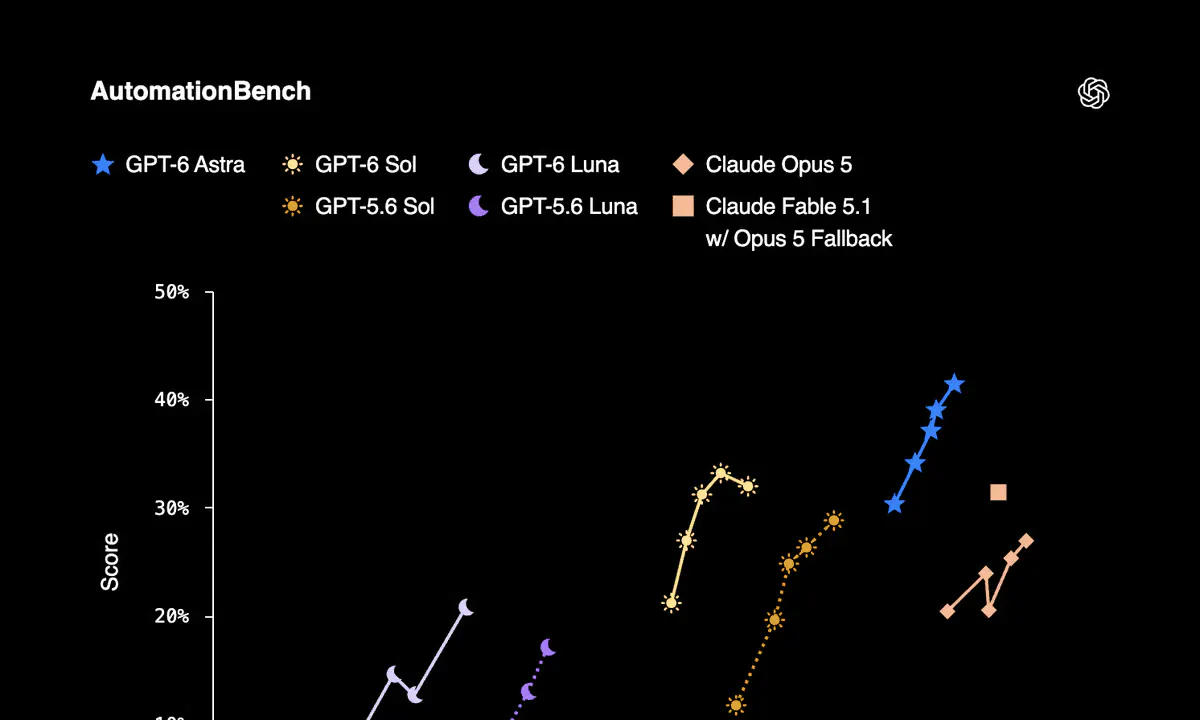
OpenAI expands its GPT-6 lineup with two cheaper, faster siblings to Astra, cutting API prices in half and pushing prompt caching further.
METR’s API key theft shows why you must check authentication, credential access, and permissions before deployment.
Anthropic's newest flagship model lands in Copilot Pro+, Max, Business, and Enterprise, promising Opus 5 quality with fewer steps, fewer tokens, and 40% lower cost.
Anthropic's new flagship lands in Cursor with a 57.8% CursorBench Max score and 40% cheaper per-task cost than Opus 5.
Lovable swapped in Anthropic's Opus 5.5 across its app-building agent, cutting build steps by up to 48% with no drop in output quality.
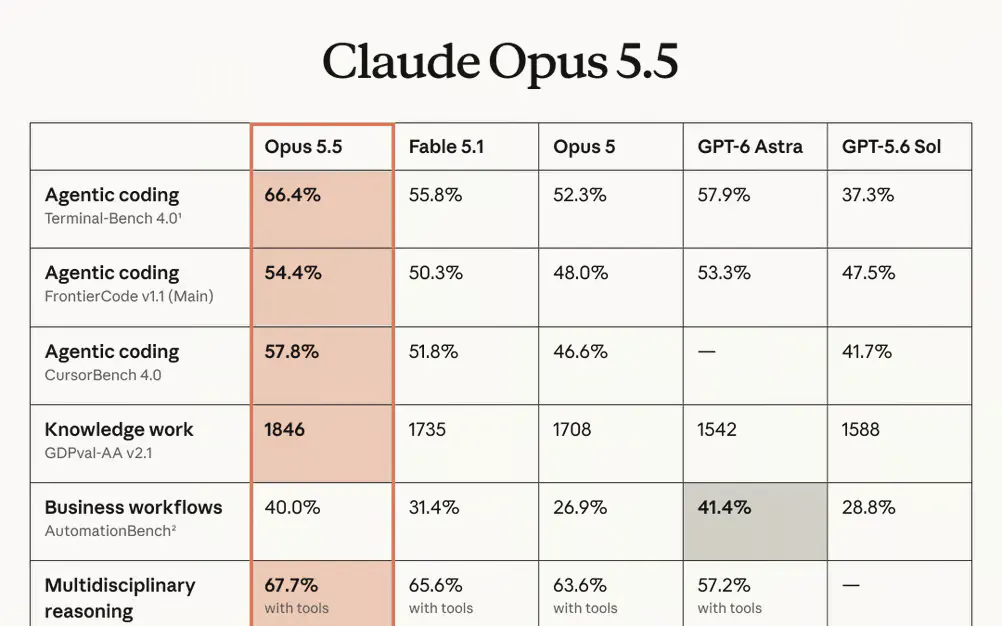
Anthropic's new flagship model matches Fable 5.1 quality on most work while cutting costs 40%, with faster output and stronger alignment scores.
Runway's new DIFFUSE platform turns its Talent Network into a full hiring marketplace, matching AI-fluent creatives with brands, agencies and studios that need them.
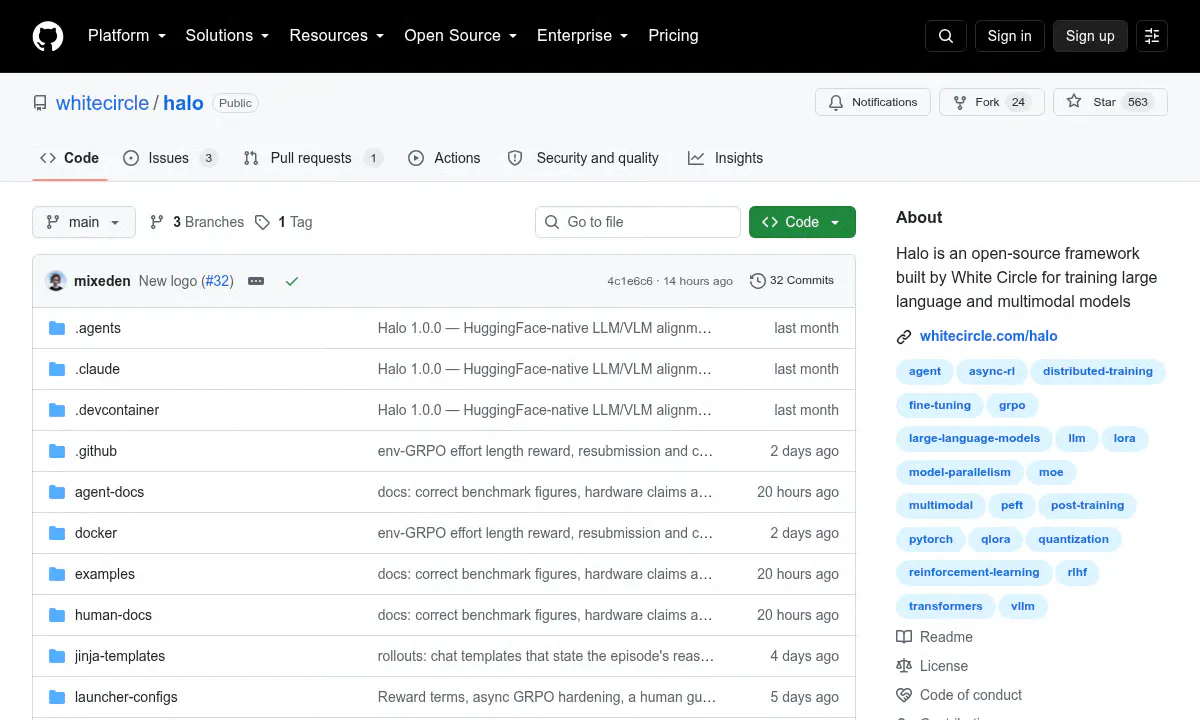
White Circle open-sourced Halo, a distributed training framework that keeps models in native HuggingFace format while hitting up to 2.8x TRL throughput.
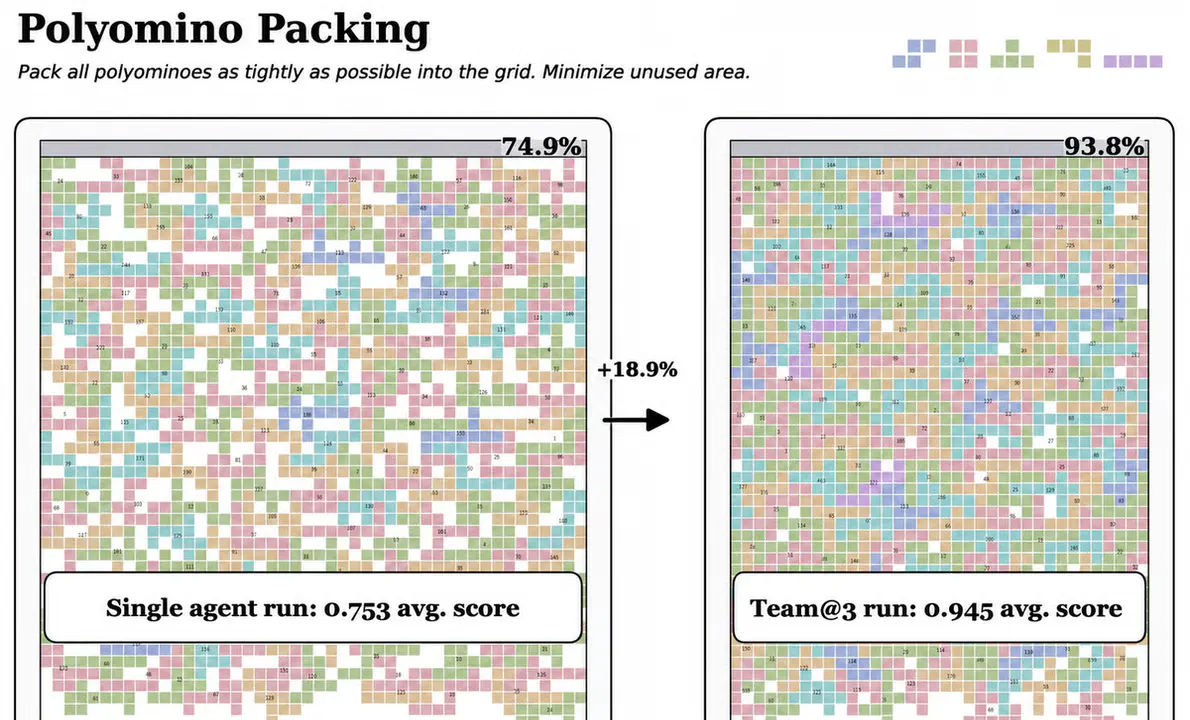
A Microsoft Research and UC Berkeley team shows agents sharing a scratchpad beat parallel independent runs, setting new records on ARC-AGI-3, polyomino packing, and MNIST compression.
Moonshot rebrands Kimi WebBridge as the Kimi Browser Extension, adding a sidebar chat, recordable skills, and cross-agent support that runs locally.
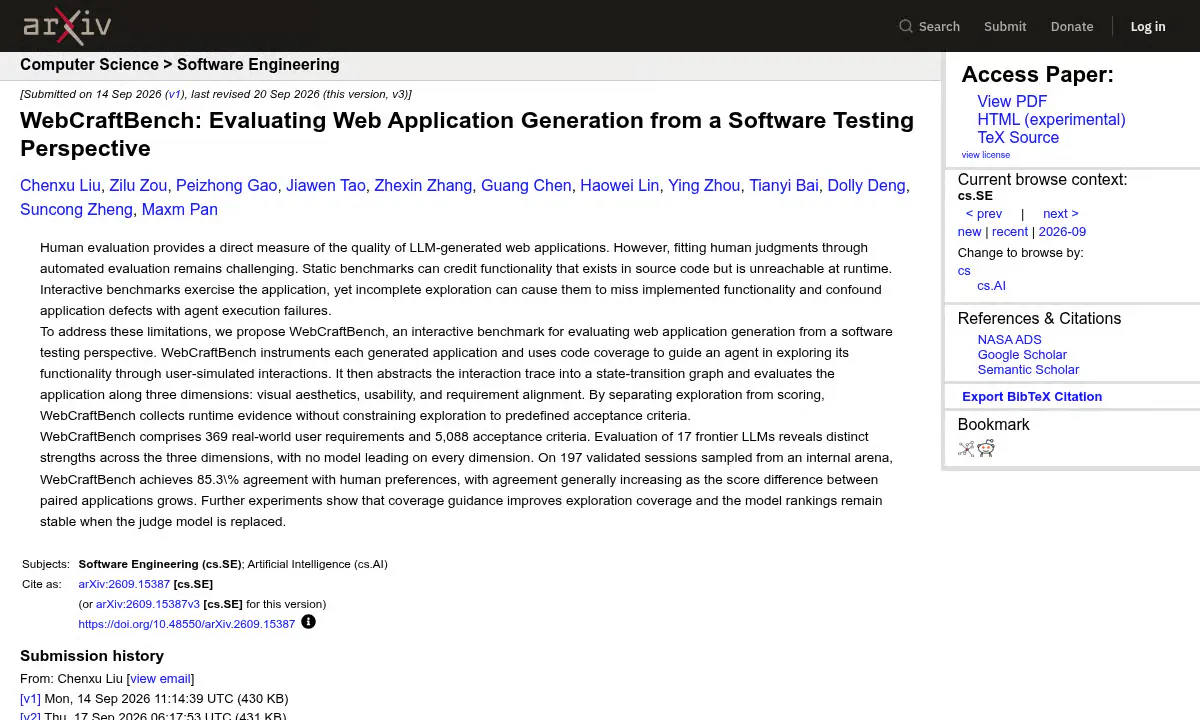
Tencent Hunyuan's new interactive benchmark actually runs AI-generated web apps, uses code coverage to hunt broken paths, and matches human taste 85.3% of the time.
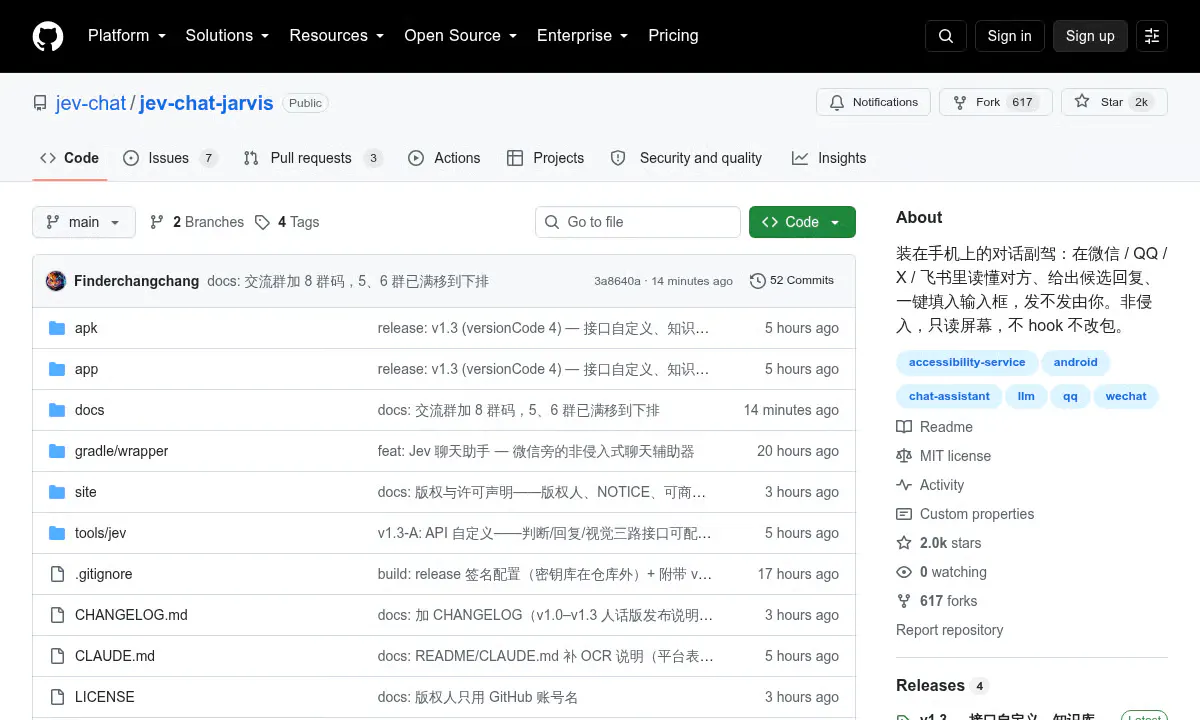
An Android accessibility-service app reads WeChat, QQ, and X conversations, then drafts three ranked replies you can paste with one tap.

Moonshot's 2.8T-parameter open-weight model lands on AWS with a 1M-token context, native vision, and explicit prompt caching for agent workloads.
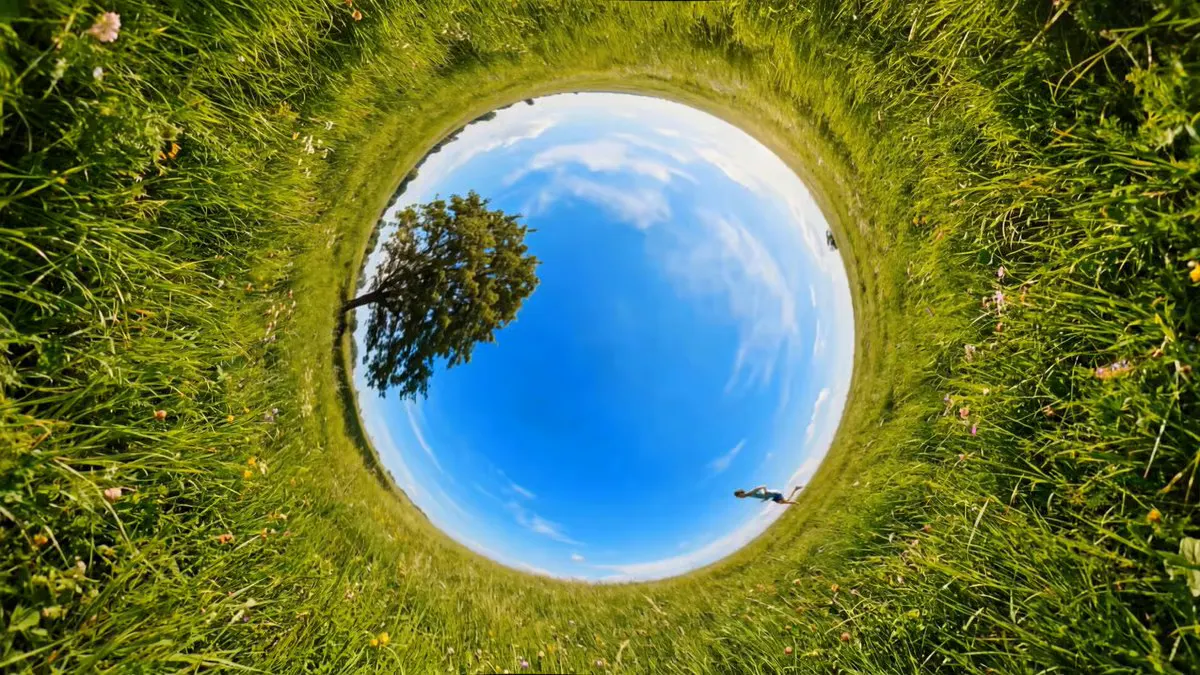
Tencent's Hunyuan team launched a preview of Hy Image 3.5, claiming a 30% win rate boost over 3.0 at $0.024 per image.
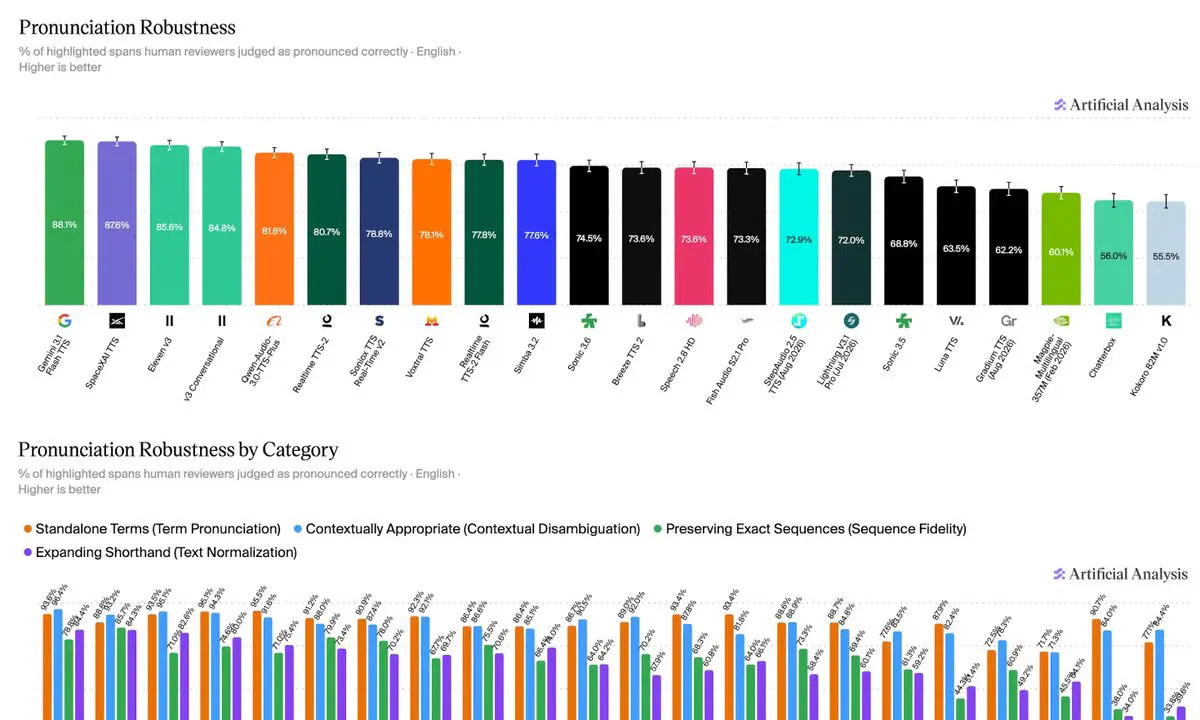
A new benchmark scores text to speech models on how correctly they pronounce tricky words, and voice preference does not predict accuracy.
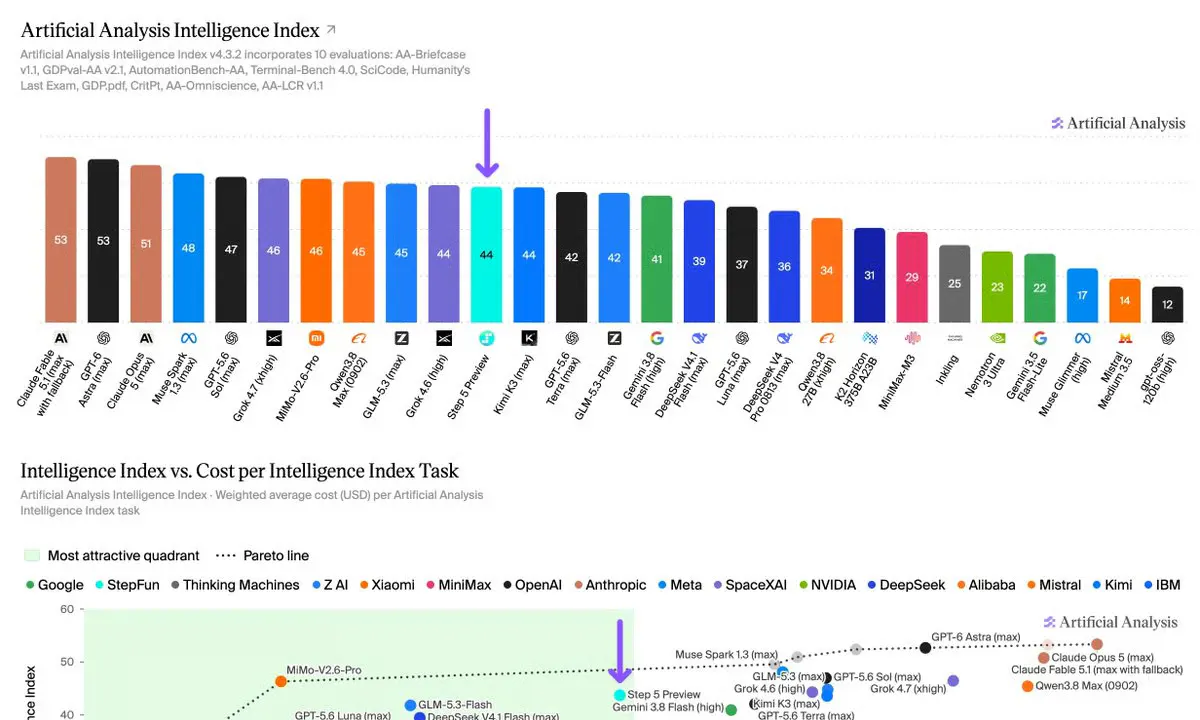
StepFun's new 600B MoE flagship matches Kimi K3 on the Intelligence Index at roughly one third the cost, with open weights due in October.
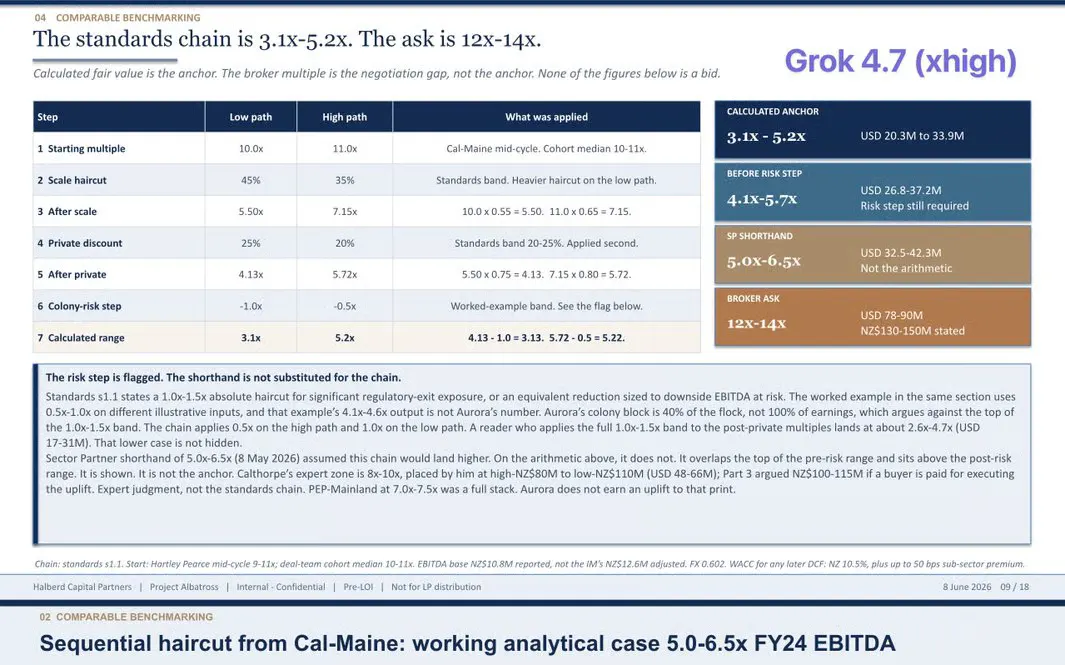
xAI's Grok 4.7 jumps 111 Elo on Artificial Analysis's agentic knowledge work benchmark, closing the gap with Anthropic at roughly half the cost per task.

Cognition ships xAI's newest model in Devin CLI and Desktop, where it excels at hard backend work but over-scopes on simpler tasks.
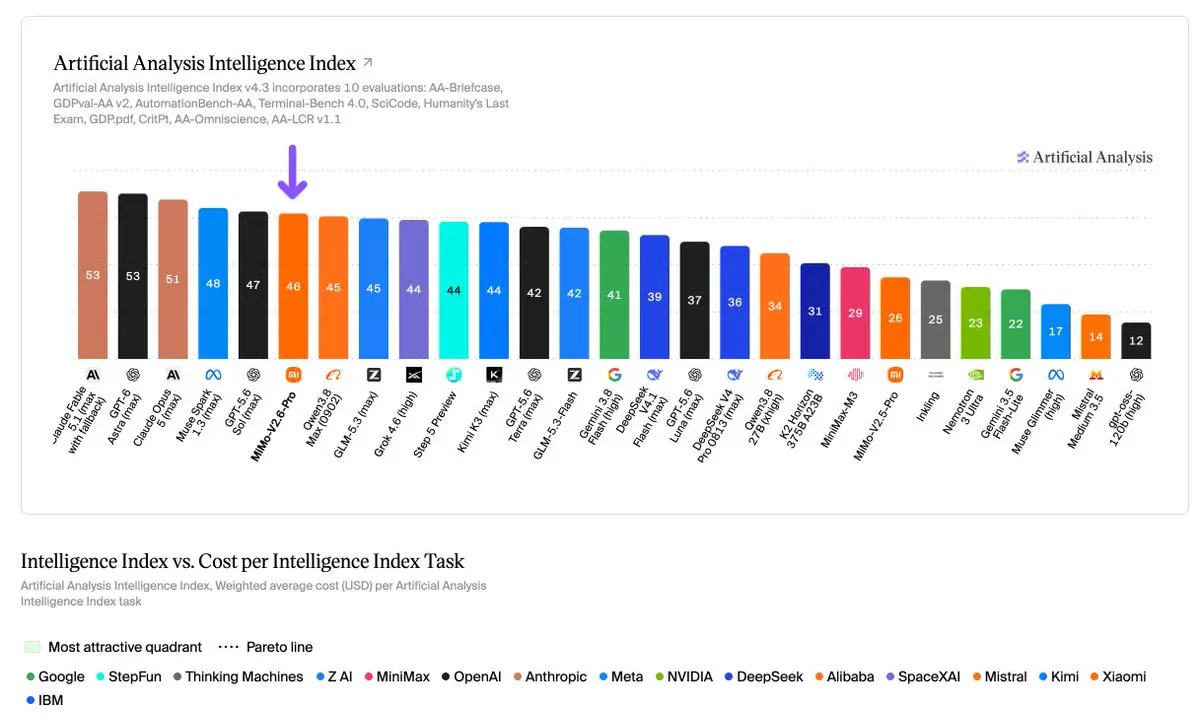
Xiaomi's new 1.02T parameter MoE tops the Artificial Analysis open weights leaderboard while costing pennies per task through aggressive caching and sparse activation.
Meta's Petal cable will deliver 1 petabit per second across the Atlantic using multi-core fiber, doubling capacity over the most advanced systems.
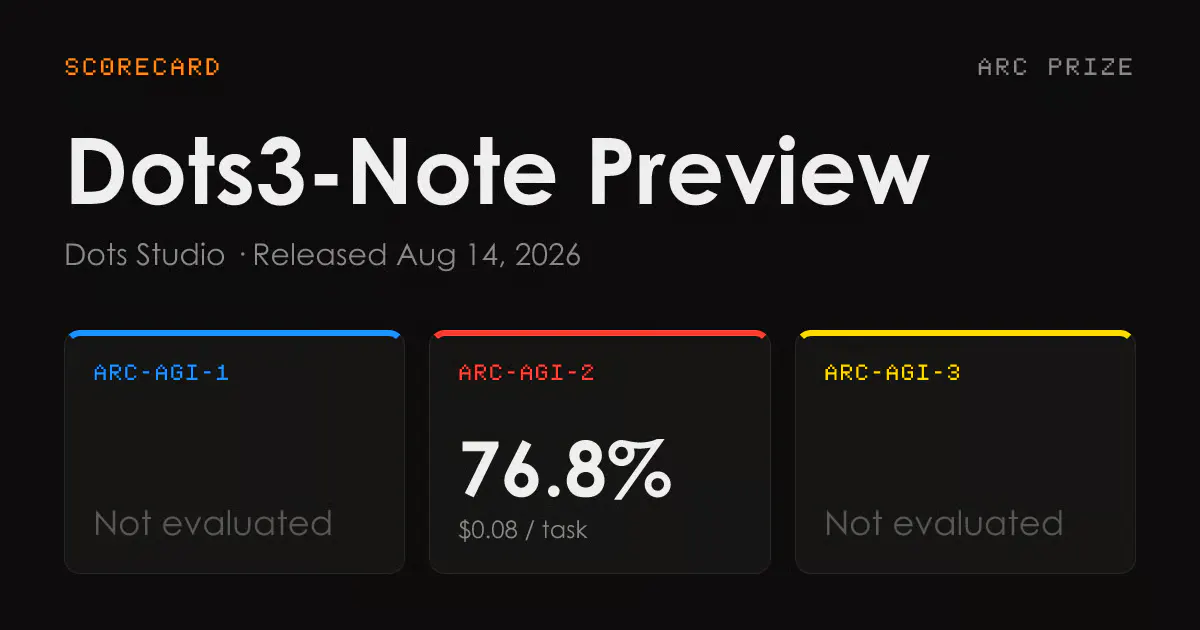
Dots Studio's 280B mixture-of-experts model hits 76.8% on ARC-AGI-2 at eight cents per task, topping the open-weight verified leaderboard.
Inco's open-source Splash engine runs Qwen3.8-27B at 74 tok/s on an M5 Pro, hitting 2x oMLX and 3x Ollama on Apple silicon.
No stories match these filters.