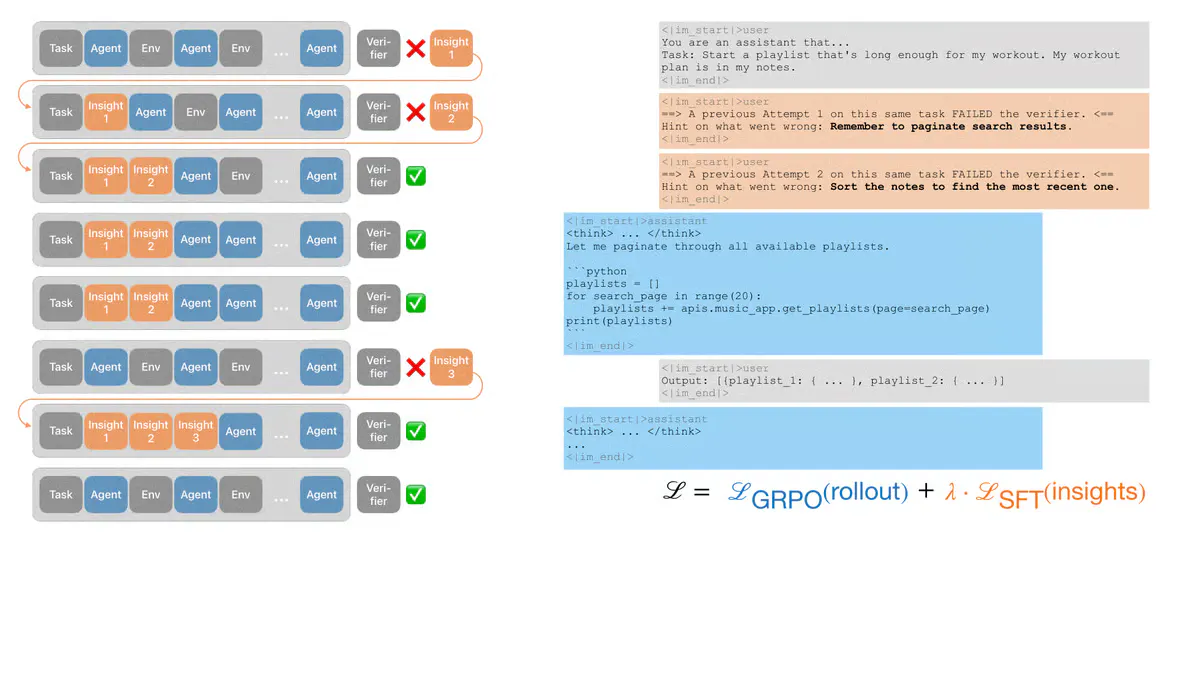
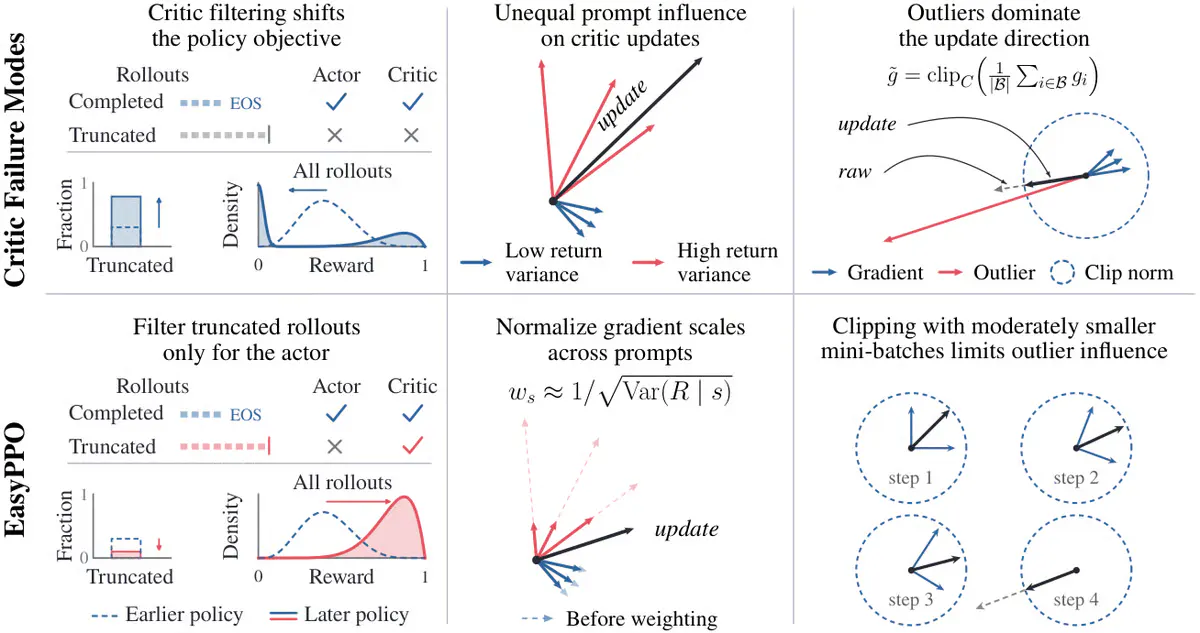
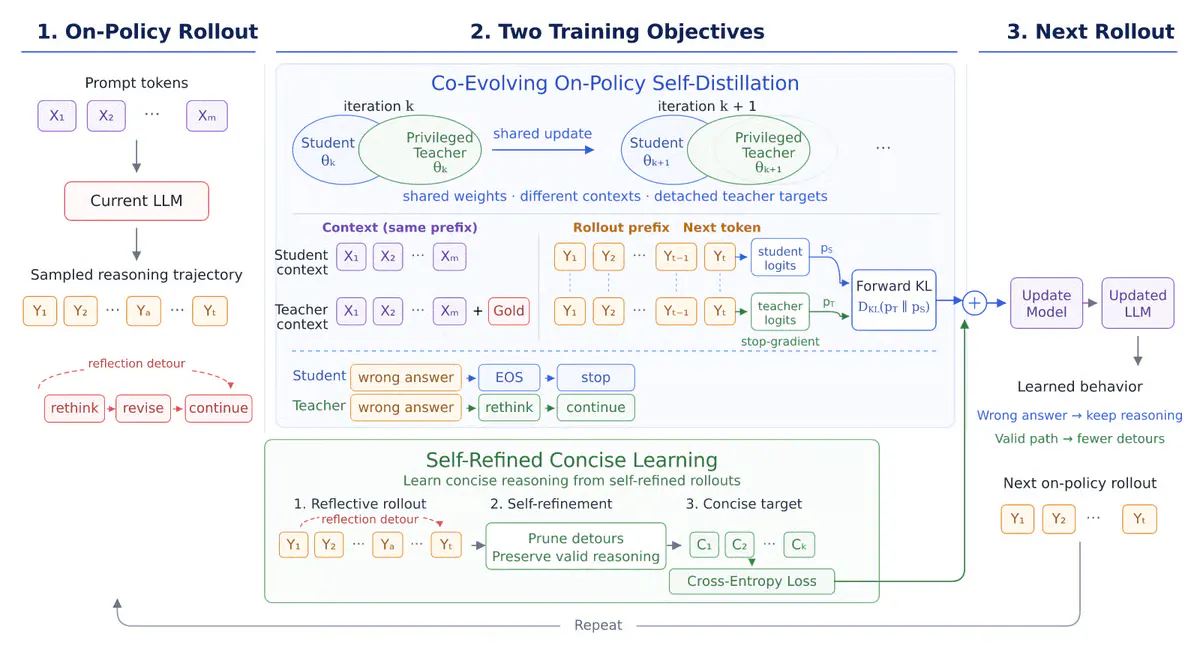
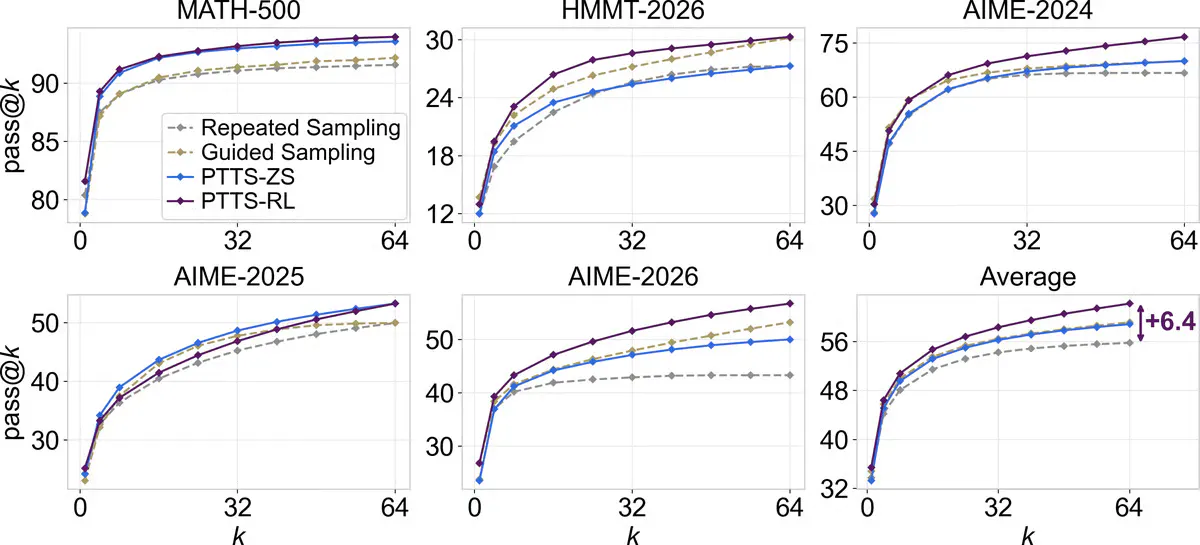
←Back to NewsAI News/Post TrainingpaperPost TrainingReasoningApple's RLTL;DR Teaches AI to Learn From Its Own FailuresApple researchers show a 9B model can crack tasks it failed 128 times in a row by backpropagating short self-written notes instead of full solutions.SourceAlphaSignalPublishedSep 29, 2026, 2:04 PMAuthorAlphaSignal NewsroomRead1 min readApple researchers show a 9B model can crack tasks it failed 128 times in a row by backpropagating short self-written notes instead of full solutions.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsAlphaSignal · paperUC Berkeley's EasyPPO Stops AI Training Collapses With Three Critic FixesAlphaSignal · paperRecursive Self-Distillation Doubles Qwen3-8B Math Accuracy to 65.97%AlphaSignal · paperUCLA's PTTS Gives AI Parallel Reasoning Branches Separate Plans, Gaining 13.4 Points