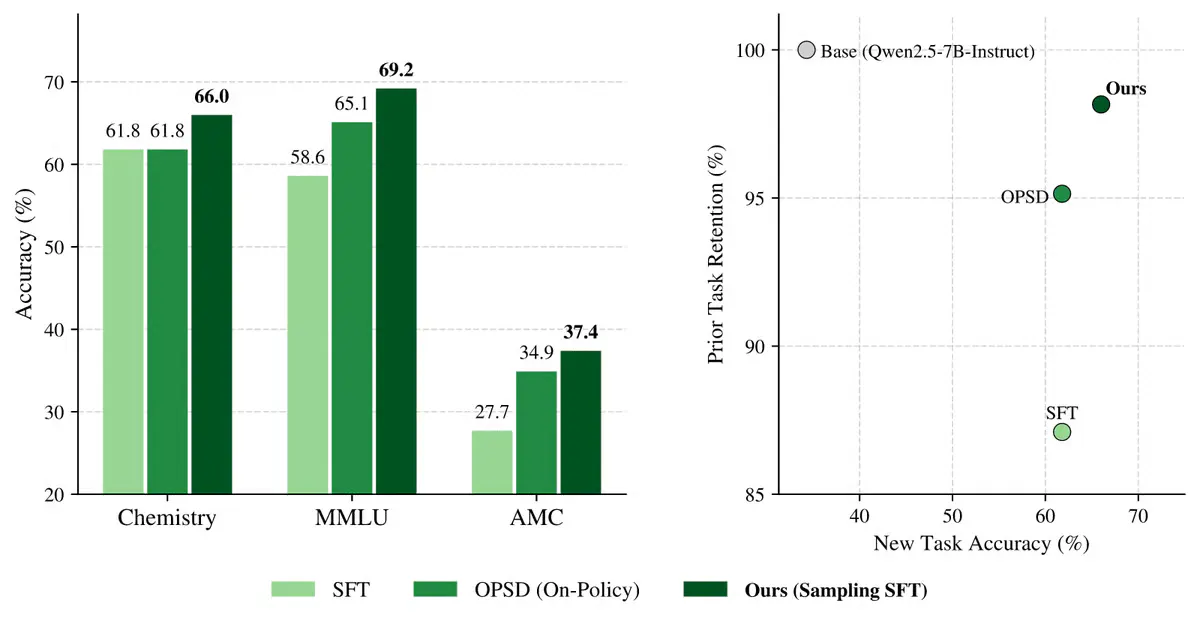
←Back to NewsAI News/Post TrainingpaperPost TrainingReasoningHarvard's Projection Sampling Makes Standard Fine-Tuning Match Reinforcement LearningHarvard researchers use MCMC sampling to reshape expert data into on-policy traces, letting supervised finetuning match or beat RL on generalization.SourceAlphaSignalPublishedOct 1, 2026, 5:45 PMAuthorAlphaSignal NewsroomRead1 min readHarvard researchers use MCMC sampling to reshape expert data into on-policy traces, letting supervised finetuning match or beat RL on generalization.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsAlphaSignal · paperAC2 Beats GRPO on Math Proofs Using 2.5x Fewer Decoding FLOPsAlphaSignal · paperApple's RLTL;DR Teaches AI to Learn From Its Own FailuresAlphaSignal · paperUC Berkeley's EasyPPO Stops AI Training Collapses With Three Critic Fixes