ISTA Squeezes a 763B DeepSeek-V4.1 Coder Into One GPU
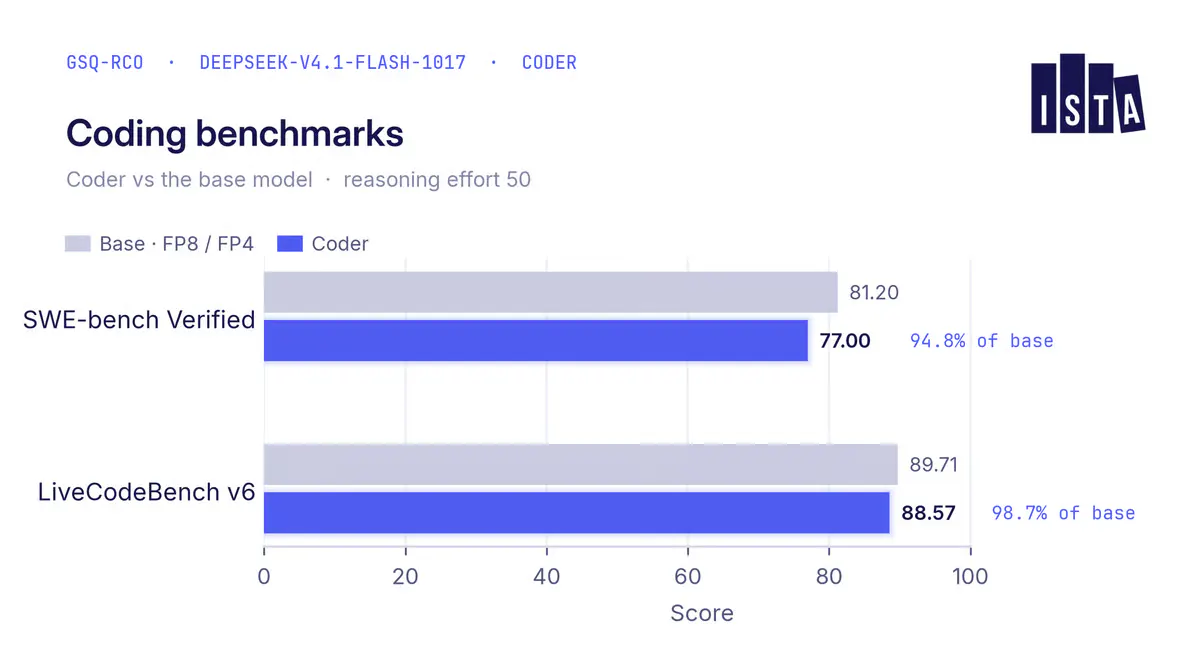
ISTA-DASLab released a 1.05 bpw compression of DeepSeek-V4.1-Flash-1017 , a 763B parameter MoE model. 72.1 GB of transformer weights fit on a single GPU, down from 138 GB for IQ2_XXS. Retains 94.8% of SWE-bench Verified and 98.7% of LiveCodeBench v6 against base.
Takeaways
- ISTA-DASLab released a 1.05 bpw compression of DeepSeek-V4.1-Flash-1017 , a 763B parameter MoE model.
- 72.1 GB of transformer weights fit on a single GPU, down from 138 GB for IQ2_XXS.
- Retains 94.8% of SWE-bench Verified and 98.7% of LiveCodeBench v6 against base.
- Combines GSQ scalar quantization with RCO expert pruning under per-layer budgets.
- 192 of 384 experts per layer removed, calibrated for code, agents, long context, vision.
- Runs on llama.cpp b11870+ or Strata , MIT licensed, free.
ISTA’s Distributed Algorithms and Systems Lab has released a compressed coder based on DeepSeek-V4.1-Flash-1017. The MIT-licensed build retains half of the model’s routed experts and quantizes the survivors, reducing 551.9 billion transformer parameters to 72.12 GB of GGUF weights. It targets local code generation and agentic tool use through Strata or llama.cpp.
The advertised 763 billion parameters include a shared Engram lookup table stored separately from the transformer. That table adds about 110 GB, bringing the full download to roughly 183 GB. The one-GPU claim relies on memory-mapping Engram from disk, so the entire package does not reside in VRAM.
The 1-bit claim, unpacked
| Measure | Value |
|---|---|
| Advertised model size | 763B parameters |
| Transformer parameters | 551.9B |
| Experts retained per layer | 192 of 384 |
| Remaining transformer parameters | About 280B |
| Transformer files | 72.12 GB across five shards |
| Engram table | About 110 GB |
| Total model assets | About 183 GB |
The reported 1.05 bits per weight comes from dividing the 72.12 GB transformer package by all 551.9 billion original transformer parameters. Pruned experts count as zero bits in that calculation. The roughly 280 billion parameters that remain consume an average of 2.06 bits each, with dense tensors stored at higher precision and surviving expert tensors using IQ2_XXS types.
The release therefore combines structural pruning with low-bit scalar quantization. Its 1.05-bit figure describes an amortized rate across retained and deleted parameters, while the stored weights use mixed precision.
Coding scores survive most of the cut
DASLab reports the following results against the base FP8/FP4 model:
| Benchmark | Base model |
|---|
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report