LoopRPT Teaches AI to Think Smarter With Every Recurrent Pass
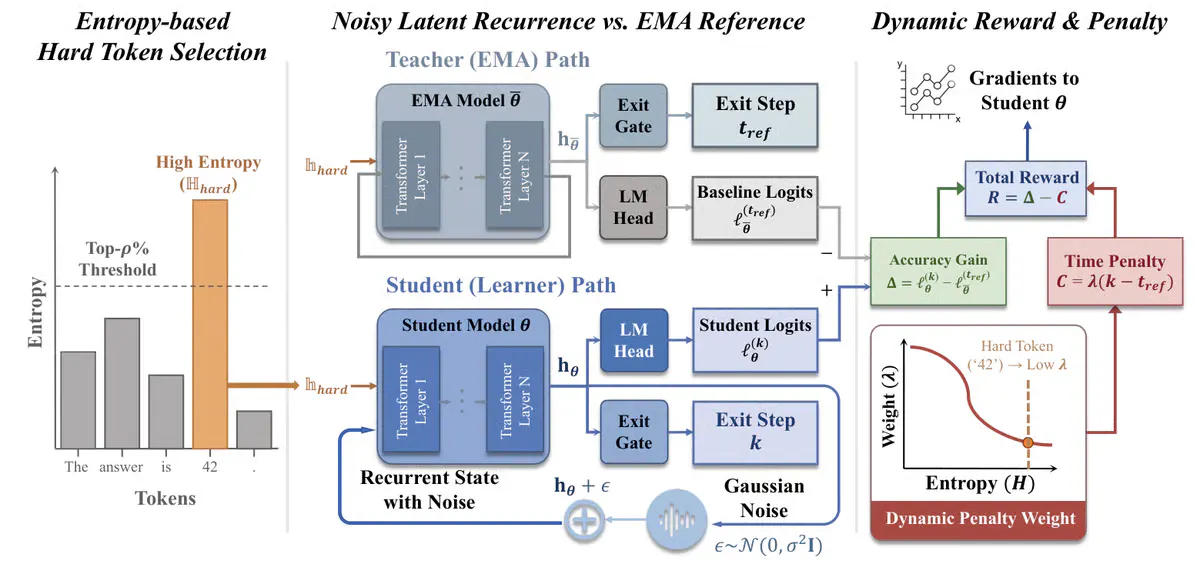
A new reinforcement pre-training recipe pushes rewards into the hidden iterations of looped transformers, improving accuracy and cutting compute per token.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new reinforcement pre-training recipe pushes rewards into the hidden iterations of looped transformers, improving accuracy and cutting compute per token.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.