Back to News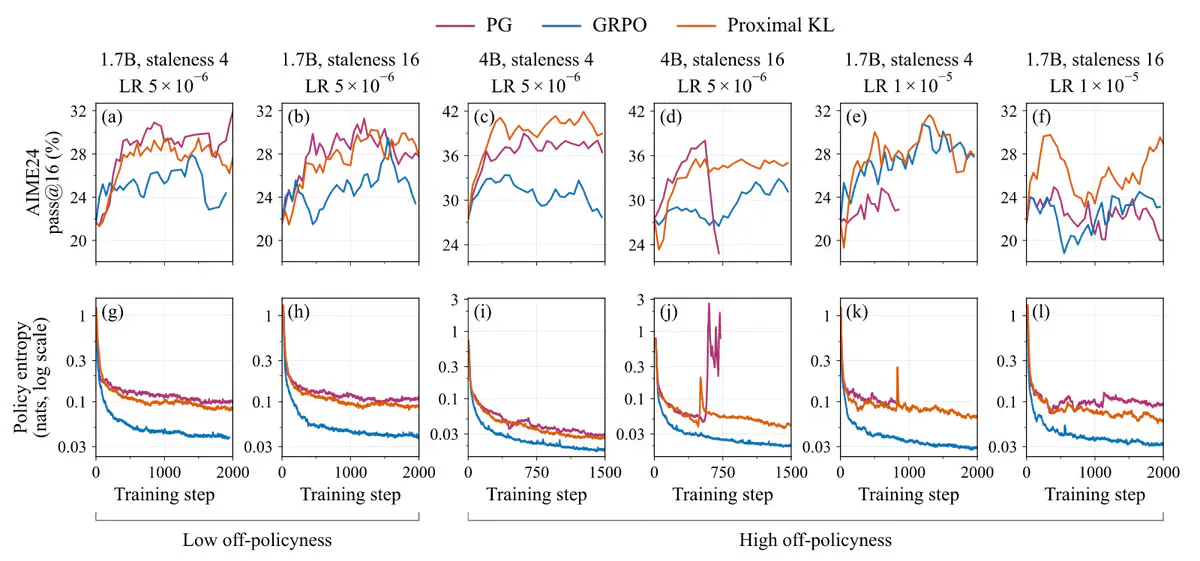
Proximal KL Beats GRPO by 2.58% When AI Training Data Goes Stale
A new RLVR training method called Proximal KL swaps PPO-style clipping for bounded future-KL credit, beating GRPO by up to 2.58% on math benchmarks.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new RLVR training method called Proximal KL swaps PPO-style clipping for bounded future-KL credit, beating GRPO by up to 2.58% on math benchmarks.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report