PyTorch 2.14 Ships Faster Apple Silicon and 100x GPU Speedups
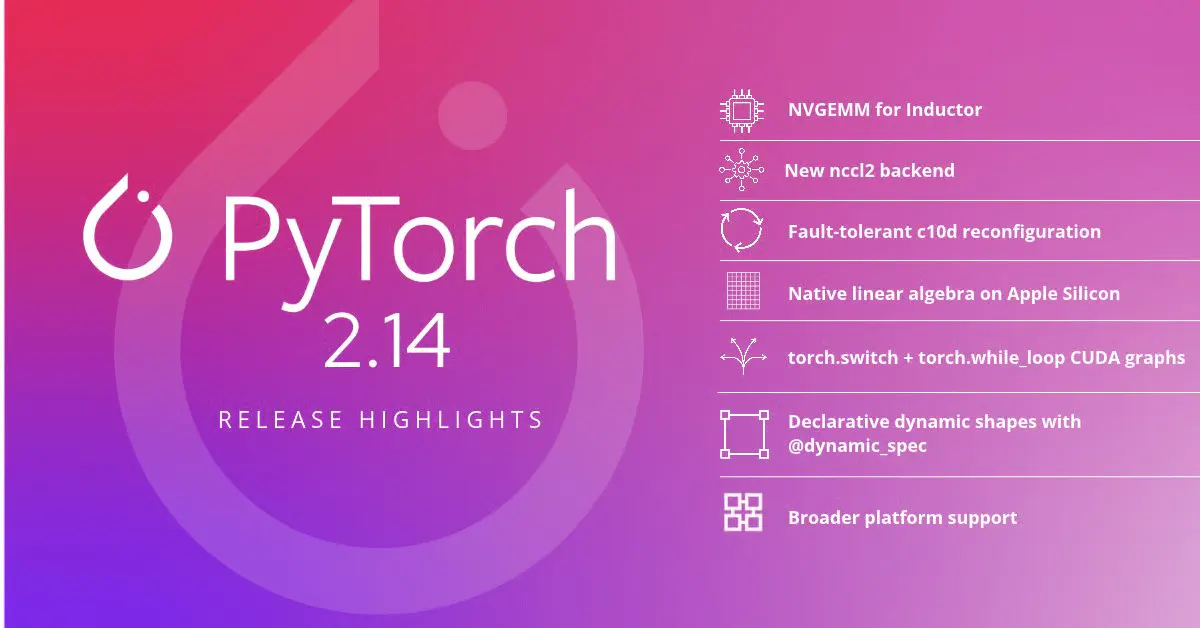
PyTorch 2.14 lands with a new CUTLASS-based GEMM backend, in-place fault tolerance for distributed training, and native linear algebra on Apple Silicon.
Source
PyTorch
Published
Author
AlphaSignal Newsroom
Read
1 min read
PyTorch 2.14 lands with a new CUTLASS-based GEMM backend, in-place fault tolerance for distributed training, and native linear algebra on Apple Silicon.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.