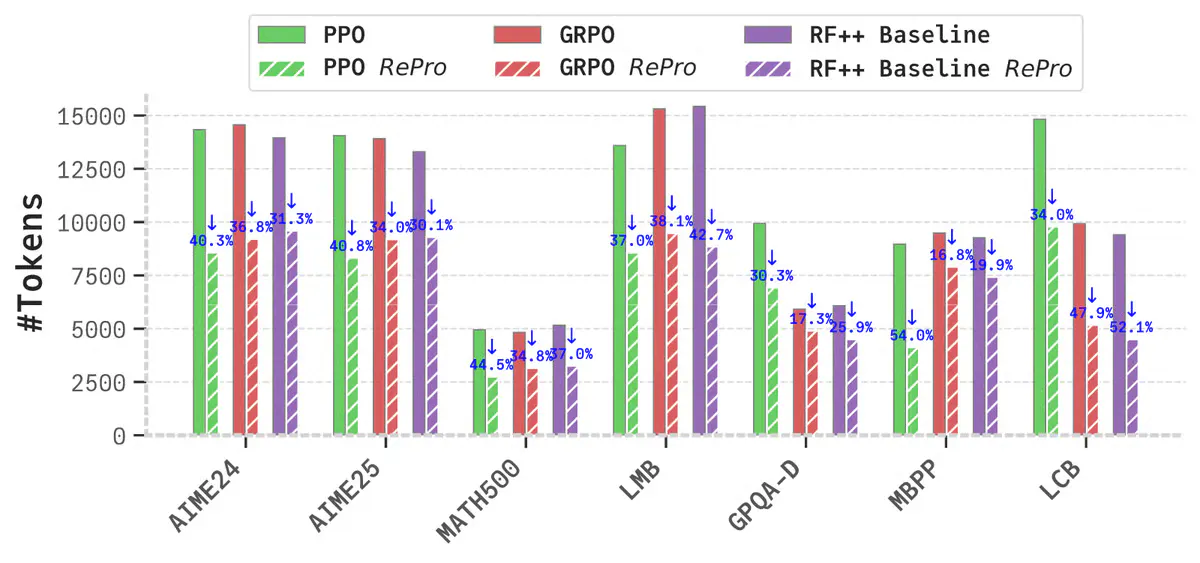
Shanghai AI Lab's RePro Cuts Reasoning Tokens 47% While Boosting Math Scores
A new reinforcement learning reward treats chain-of-thought as gradient descent, cutting tokens by about 50% while boosting accuracy on math, science, and code benchmarks.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new reinforcement learning reward treats chain-of-thought as gradient descent, cutting tokens by about 50% while boosting accuracy on math, science, and code benchmarks.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.