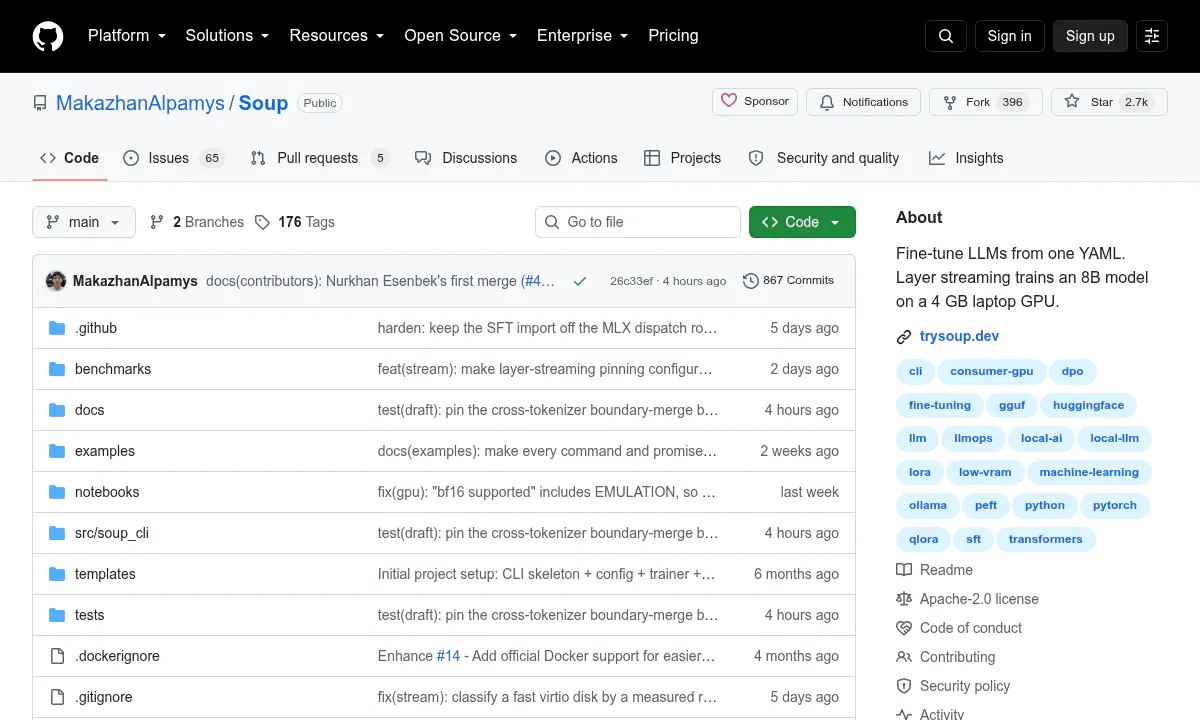
←Back to NewsAI News/Post TrainingrepoPost TrainingDevelopmentSoup Trains Llama-3.1-8B on a 4 GB Laptop GPU for FreeLayer streaming plus 4-bit quantization pins an 8B model into 3.32 GB of VRAM, turning laptop GPUs into real fine-tuning boxes.SourceAlphaSignalPublishedAug 20, 2026, 6:52 PMAuthorAlphaSignal NewsroomRead1 min readLayer streaming plus 4-bit quantization pins an 8B model into 3.32 GB of VRAM, turning laptop GPUs into real fine-tuning boxes.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsCognition · newsCognition's SWE-2 Beats GPT-5.6 Sol at 64% Lower CostAlphaSignal · repoJianying Headless Lets Coding Agents Build Editable Video Drafts From JSONPydantic · newsPydantic AI Adds Jev to Cut Classification Latency 6x Without Generating Tokens