UC Berkeley's EasyPPO Stops AI Training Collapses With Three Critic Fixes
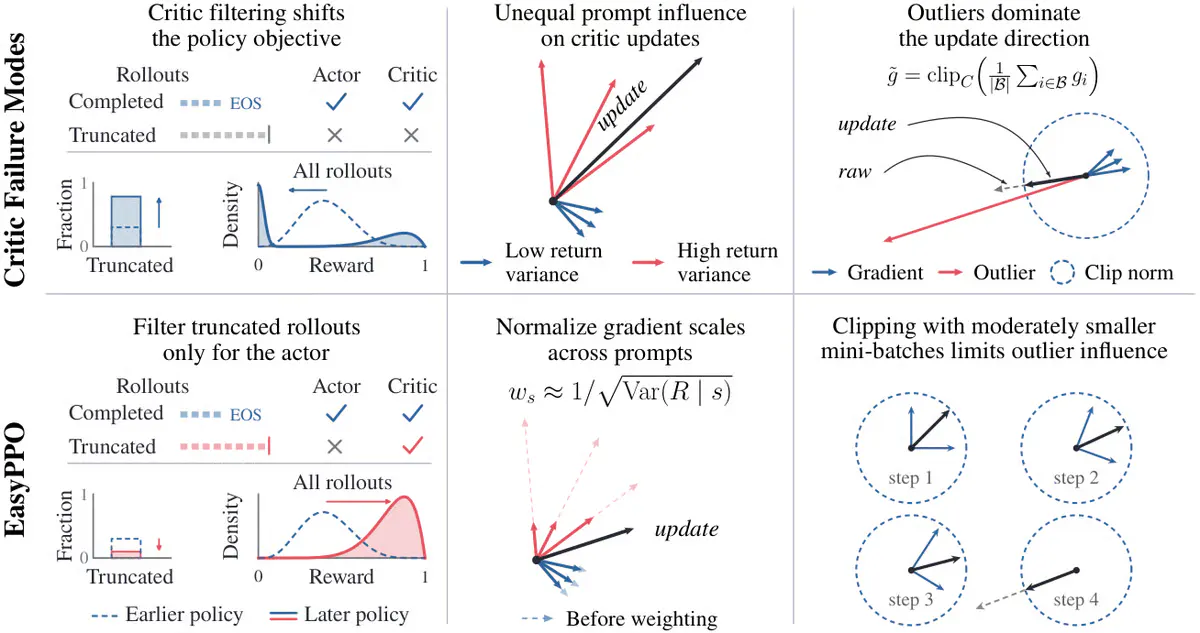
A trio of surgical tweaks to PPO's critic eliminates training collapse in LLM reinforcement learning, delivering up to 14.89% score gains without touching the actor.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A trio of surgical tweaks to PPO's critic eliminates training collapse in LLM reinforcement learning, delivering up to 14.89% score gains without touching the actor.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.