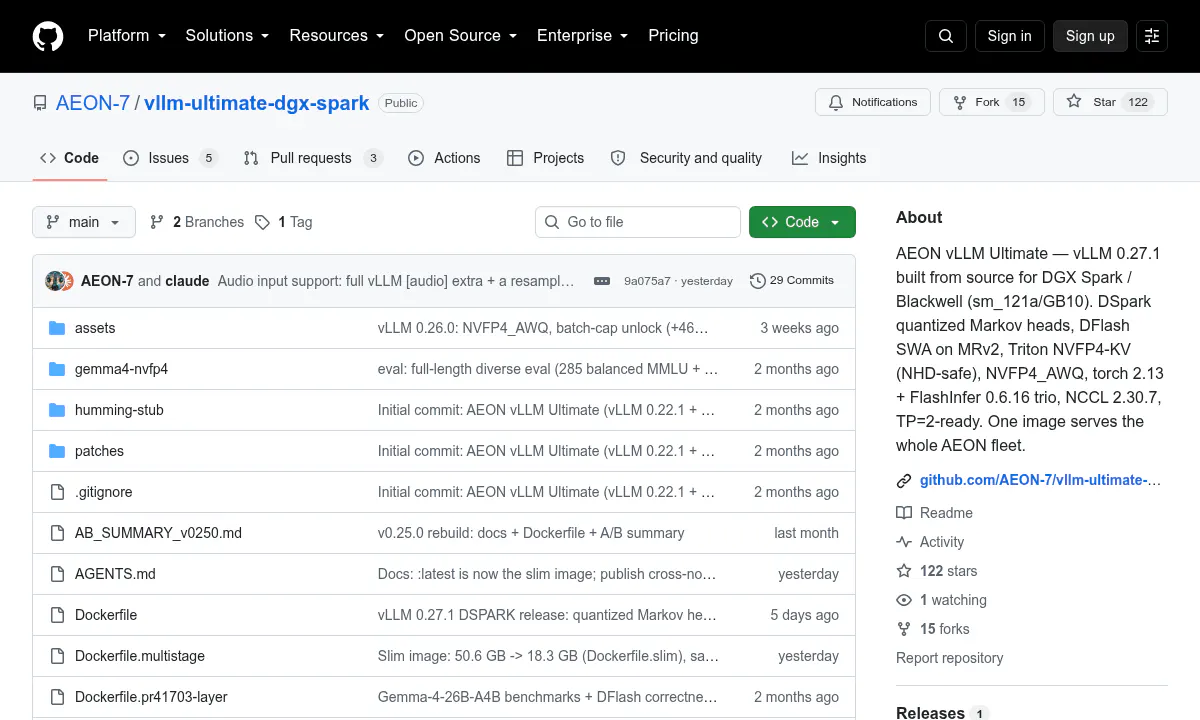
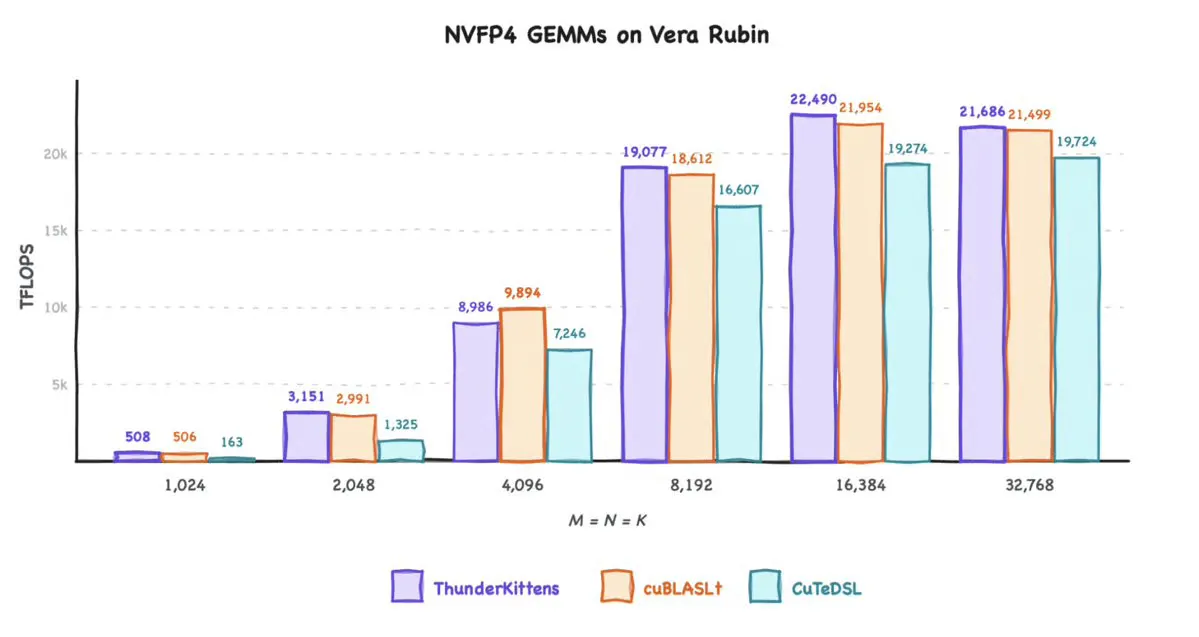
←Back to NewsAI News/InfrarepoInfraGpusAEON vLLM Ultimate Fixes NVIDIA DGX Spark's Broken AI Stack in One PullA community-built vLLM container brings NVFP4 KV cache, DFlash speculative decoding, and Blackwell sm_121a runtime patches to DGX Spark serving.SourceAlphaSignalPublishedAug 20, 2026, 9:41 PMAuthorAlphaSignal NewsroomRead1 min readA community-built vLLM container brings NVFP4 KV cache, DFlash speculative decoding, and Blackwell sm_121a runtime patches to DGX Spark serving.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsTogether AI · newsTogether AI's ThunderKittens Hits 22.4 PFLOPS on NVIDIA's RubinIntelligent Internet · newsIntelligent Internet's Meta-Zenith Agent Rewrote vLLM Kernels for a 4x SpeedupPyTorch · newsNVIDIA's CUDA Python 1.0 Makes Python a First-Class GPU Citizen