
Tamara Tran's fast-jev-compaction Stops Claude Code From Forgetting Critical Tool Output
A new open-source Claude Code plugin uses TypeSafe's Jev decision model to prune agent context per tool call instead of summarizing it away.
hermes-ai.net
Read docs →A focused feed of models, agents, research and open-source releases for people building with AI.
A new open-source Claude Code plugin uses TypeSafe's Jev decision model to prune agent context per tool call instead of summarizing it away.
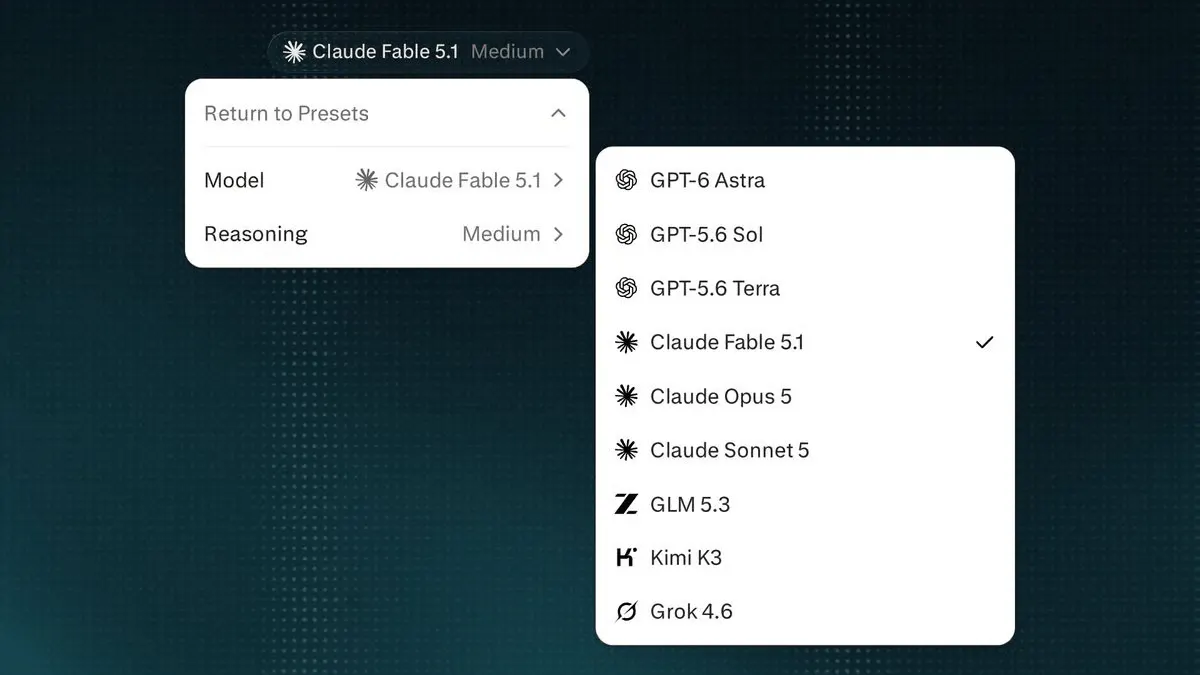
Perplexity Computer now lets users pick effort levels from Light to Ultra, and the orchestrator picks the right model and reasoning depth automatically.
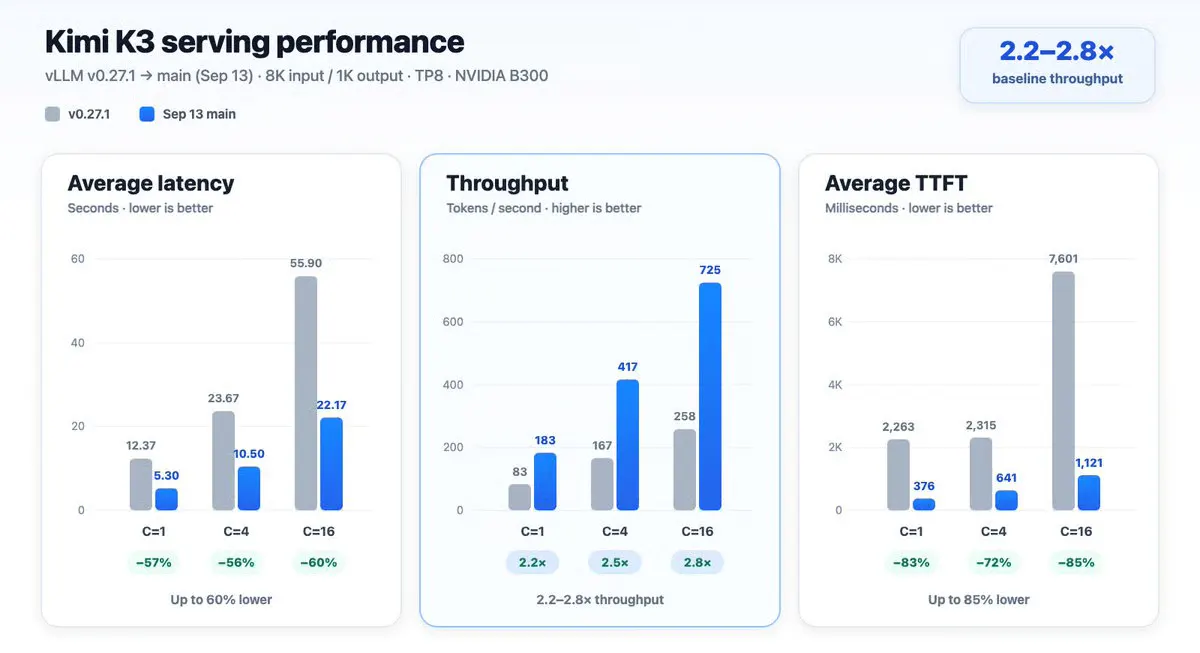
vLLM's latest optimizations push Kimi K3 serving to 2.2 to 2.8x higher throughput on B300 GPUs, with TTFT cut by up to 85%.
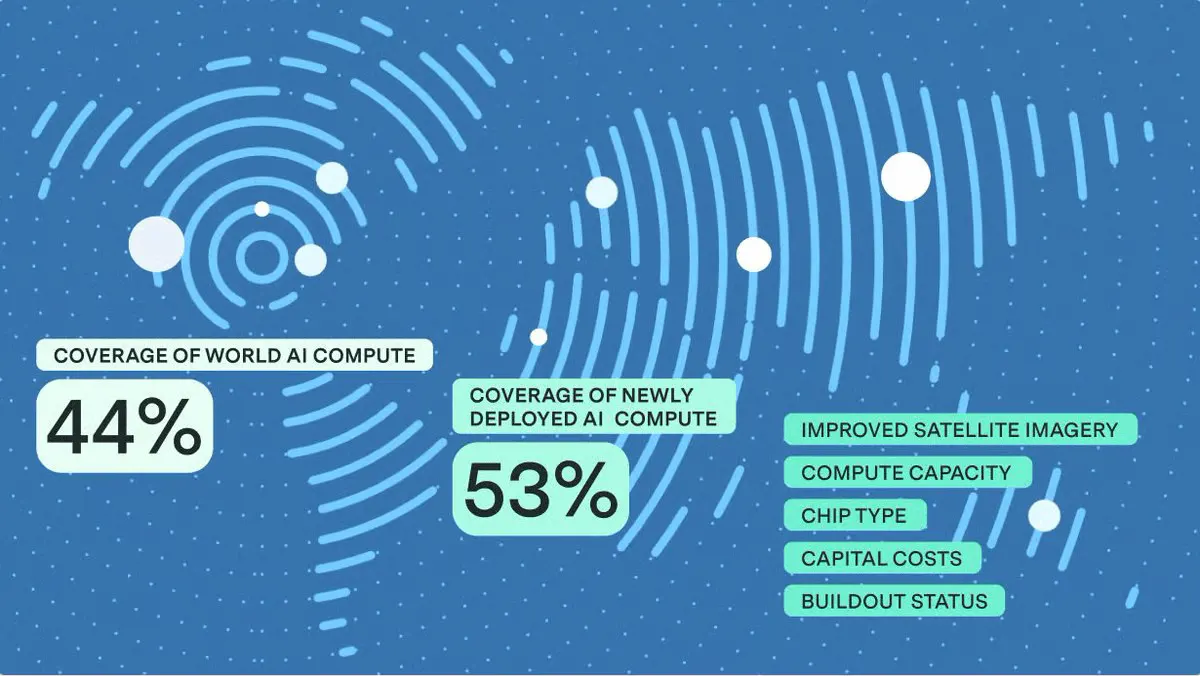
Epoch AI's data center explorer now maps 86 sites covering an estimated 44% of global AI compute, with satellite imagery and detailed hardware specs.
Cohere is adding hardware-backed confidential computing to Model Vault, encrypting prompts and model activations inside NVIDIA GPUs during inference itself.
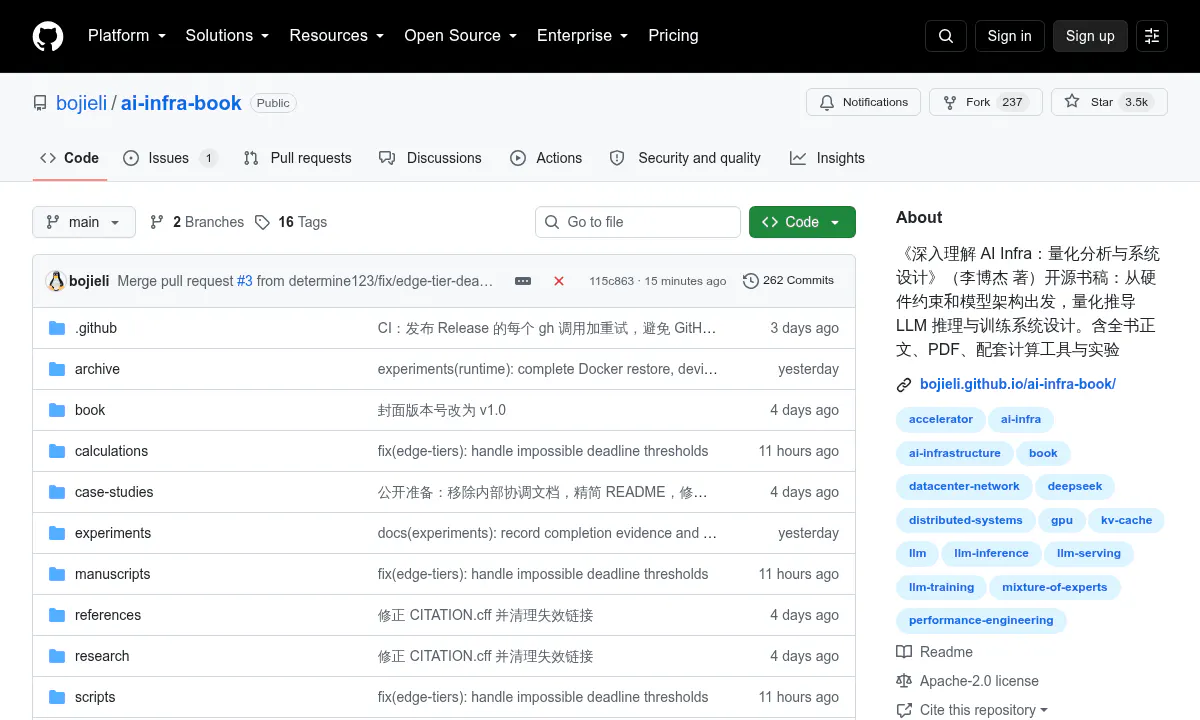
Bojie Li open-sourced a Chinese-language AI infra textbook that derives inference and training system design from first-principles hardware constraints, with 3.4k stars in days.

A hobbyist lab shipped a two-node vLLM stack that runs GLM-5.3-Flash at 4bpw across a pair of DGX Sparks with 900k context.
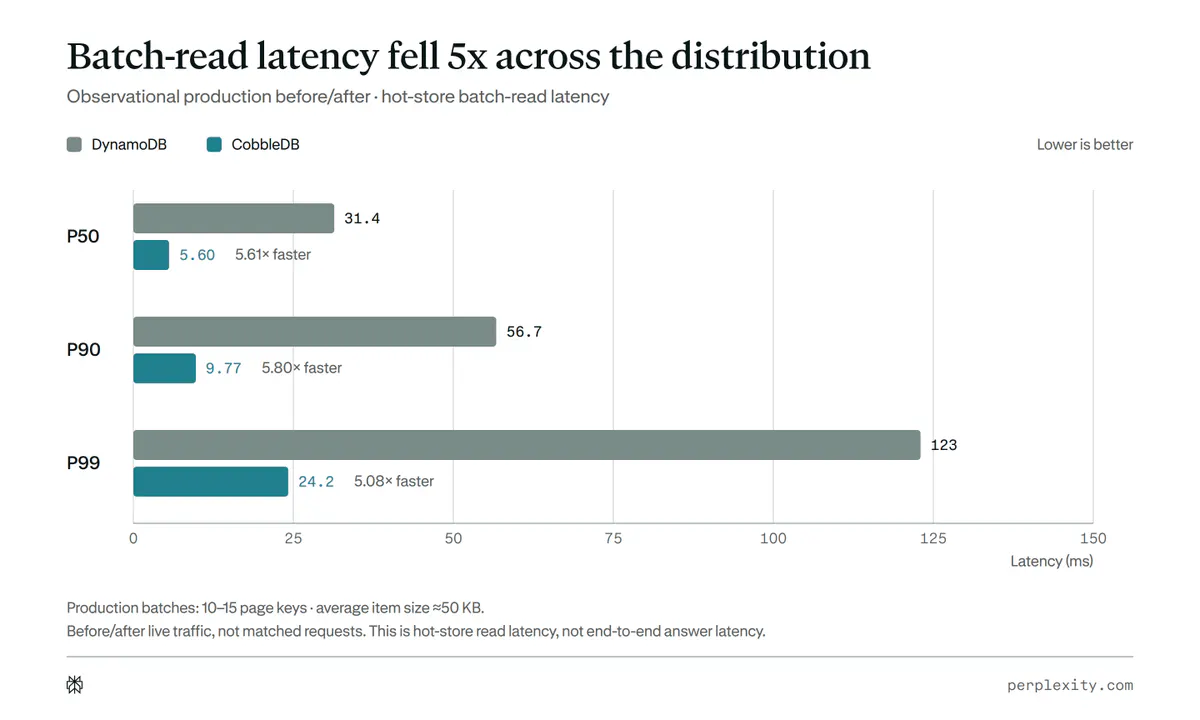
Perplexity rebuilt its search hot store from scratch, cutting batch-read latency 5x and slashing costs 20% versus DynamoDB.
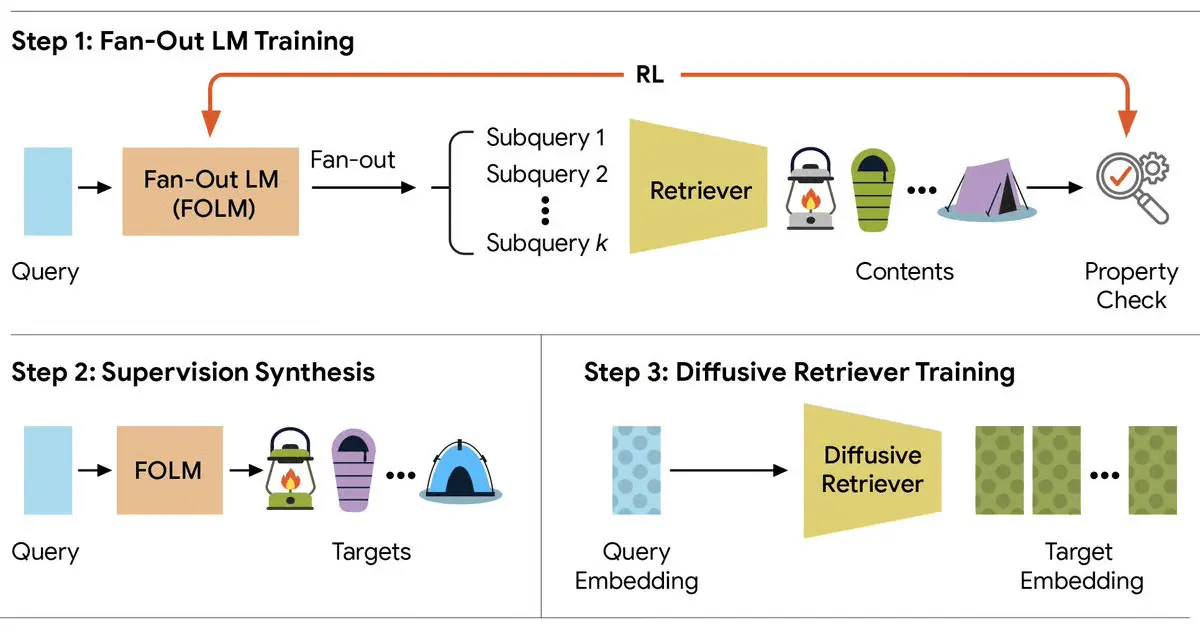
Google Research swaps expensive chain-of-thought fan-out for a 53.9M-parameter diffusion retriever, delivering 12-20x faster expert-level search slates.
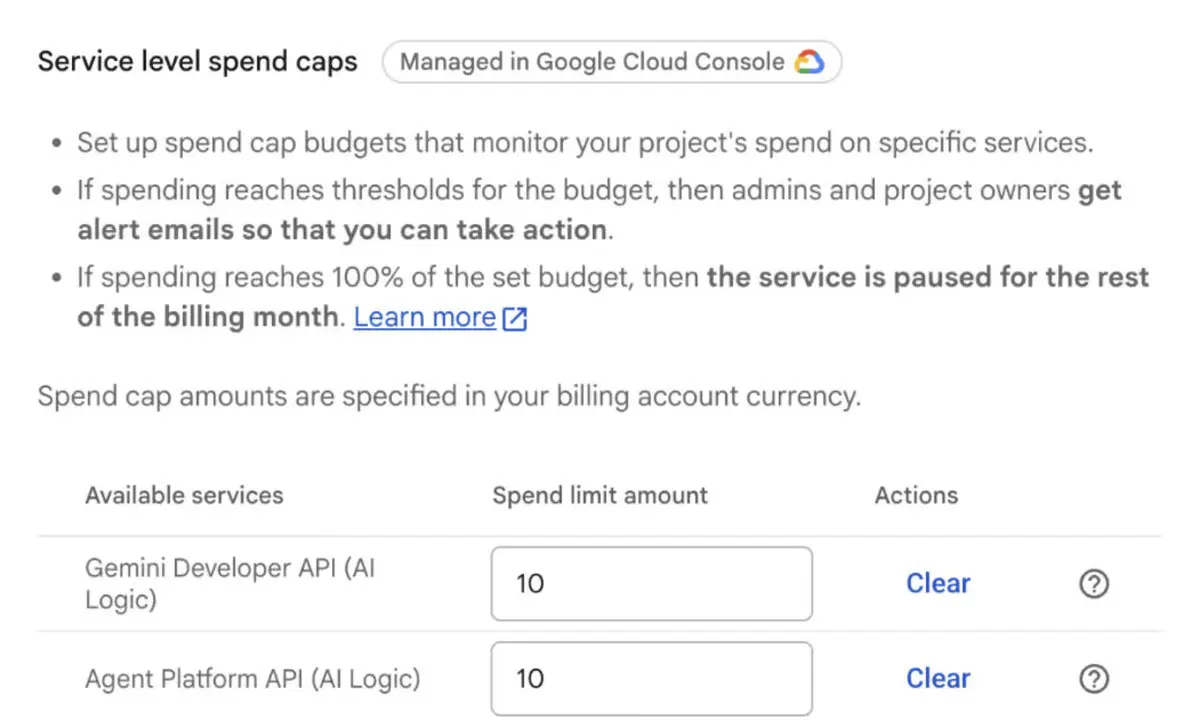
Firebase now lets you cap spending per service and auto-pause workloads at 100% of budget, protecting against runaway Gemini API and Cloud Functions bills.
A 552B model with 890-byte KV cache, 8B active on input, and an Artificial Analysis 40 versus Gemini 3.8 Flash High at 41
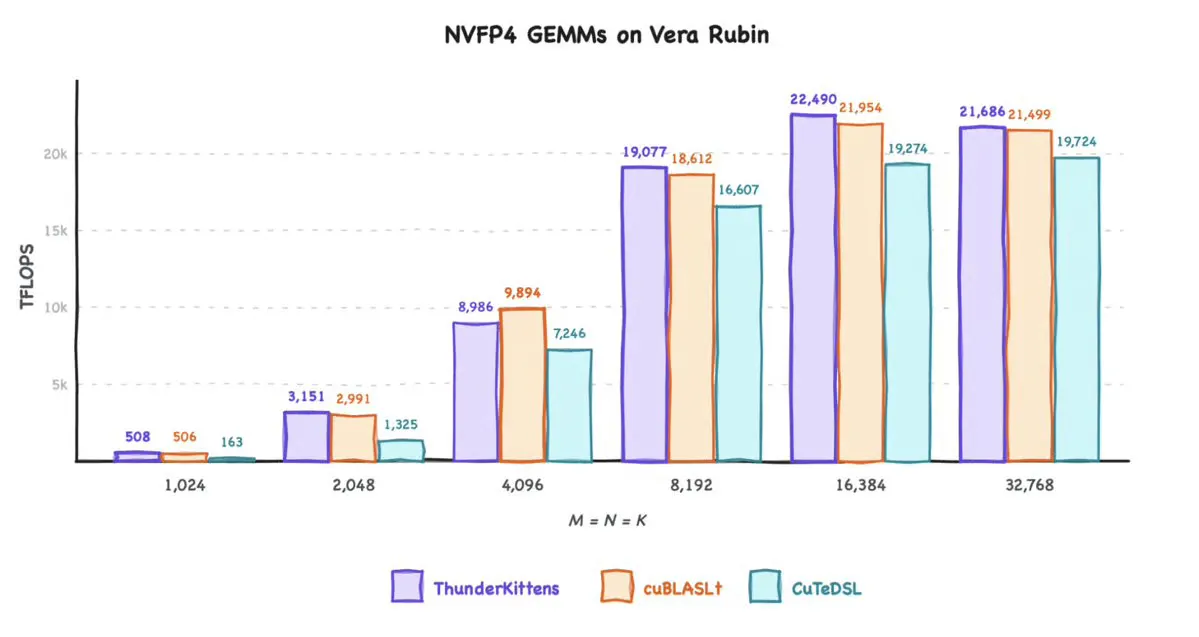
Together AI ported its ThunderKittens kernel framework to NVIDIA's Vera Rubin NVL72, hitting 22.4 PFLOPS on NVFP4 GEMMs and rivaling cuBLAS.
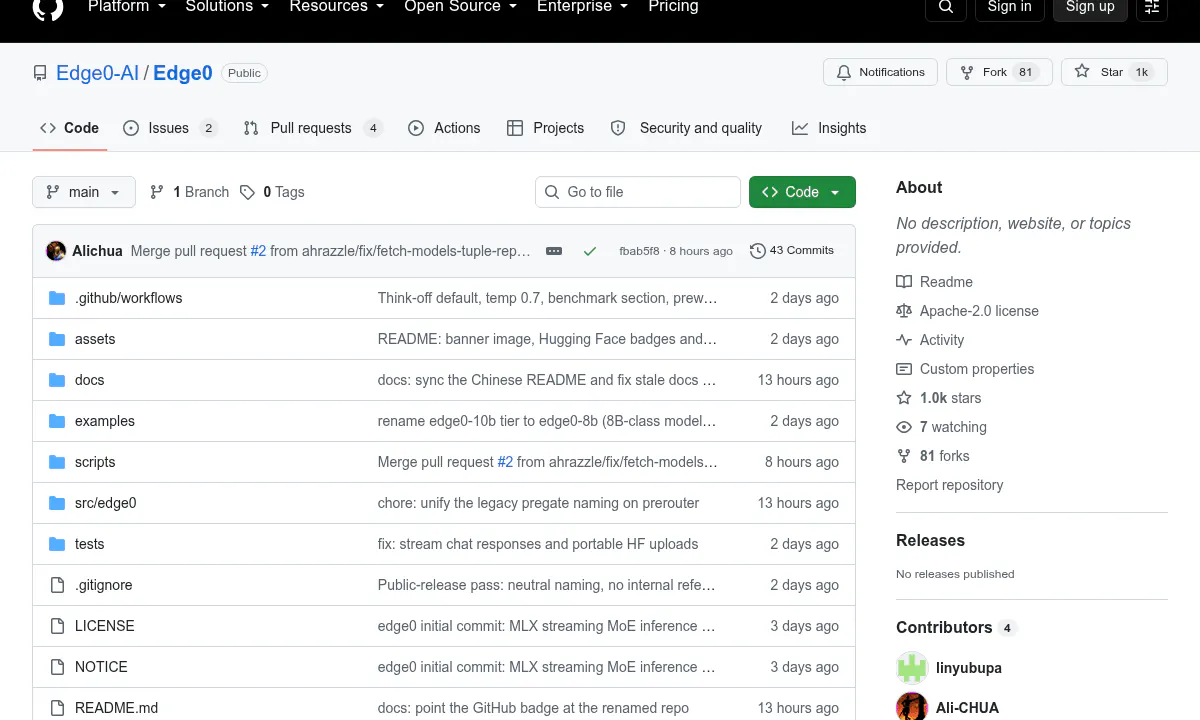
Edge0 is an open source framework that streams MoE experts from SSD, letting a 35B parameter model run on a 24GB Mac mini with under 3GB active memory.
Breakpoints, TTL math, Batch stacking, and a two-session split. Measured on OpenRouter, $0.003 vs $0.022 per turn
An autonomous agent ran 111 trials to optimize vLLM for Qwen3.8-27B on a single RTX 5090, hitting 4.1x throughput at 65K context.
NVIDIA ships CUDA Python 1.0 with semantic versioning, a shared cuda.core foundation, and PyTorch and CuPy already building on it.
Cohere open-sourced a serving engine that runs the entire LLM decode step as one persistent CUDA kernel, hitting 1.58x vLLM throughput on H100.
vLLM's new Hybrid HiSparse keeps long-context requests decoding when the KV cache overflows HBM, tripling concurrency on GLM 5.3 at 1M context.
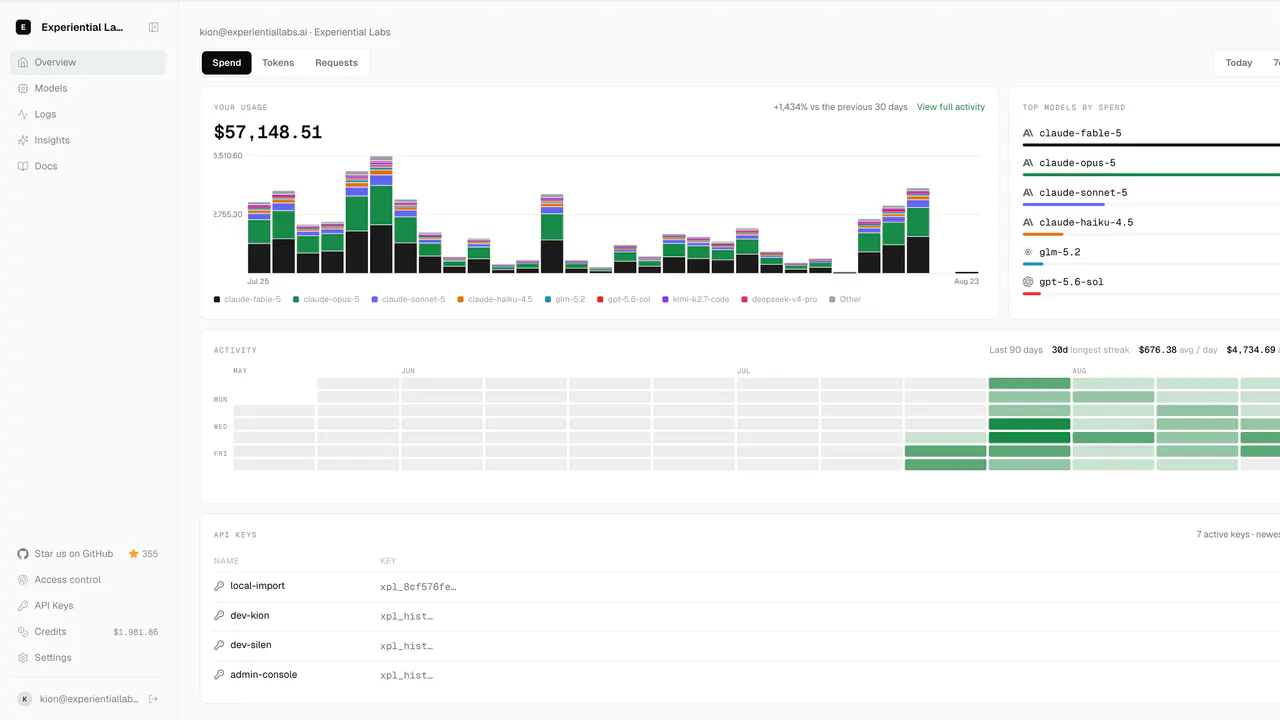
Experiential is an open source, OpenAI-compatible gateway that routes across hosted, BYOK, and local models with zero markup and spend controls.
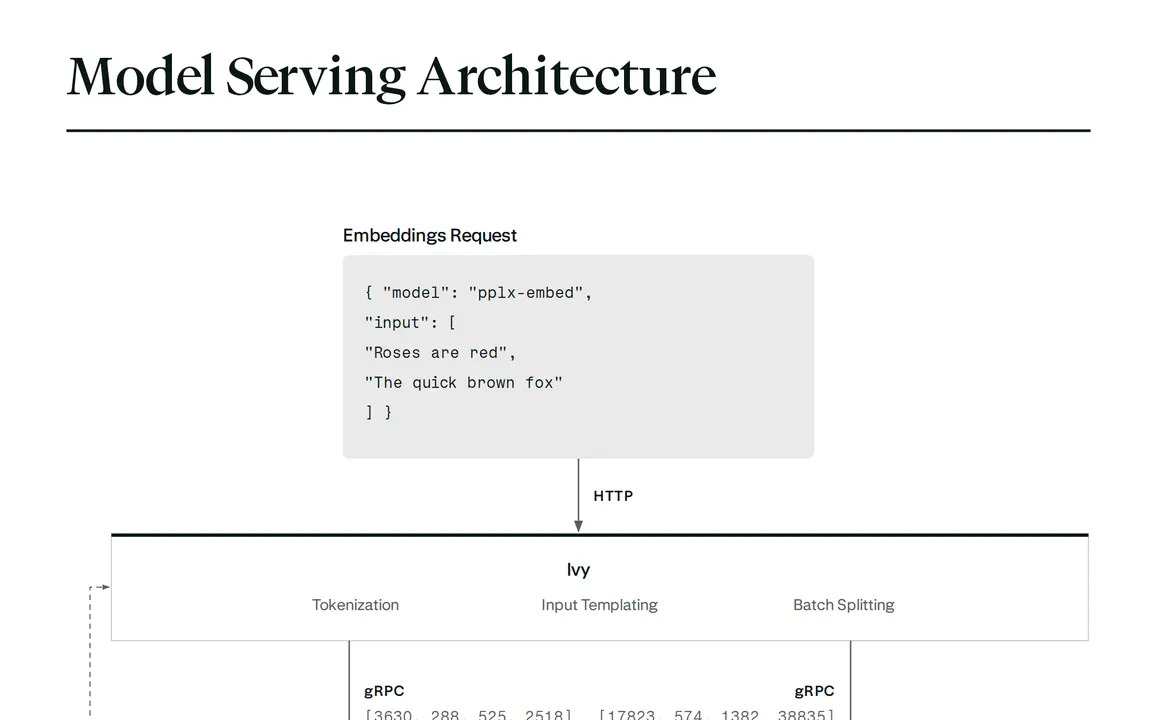
Perplexity open-sources details of Ivy, Tulip, and ROSE, its Rust plus Python embedding stack that beats vLLM on latency and throughput.
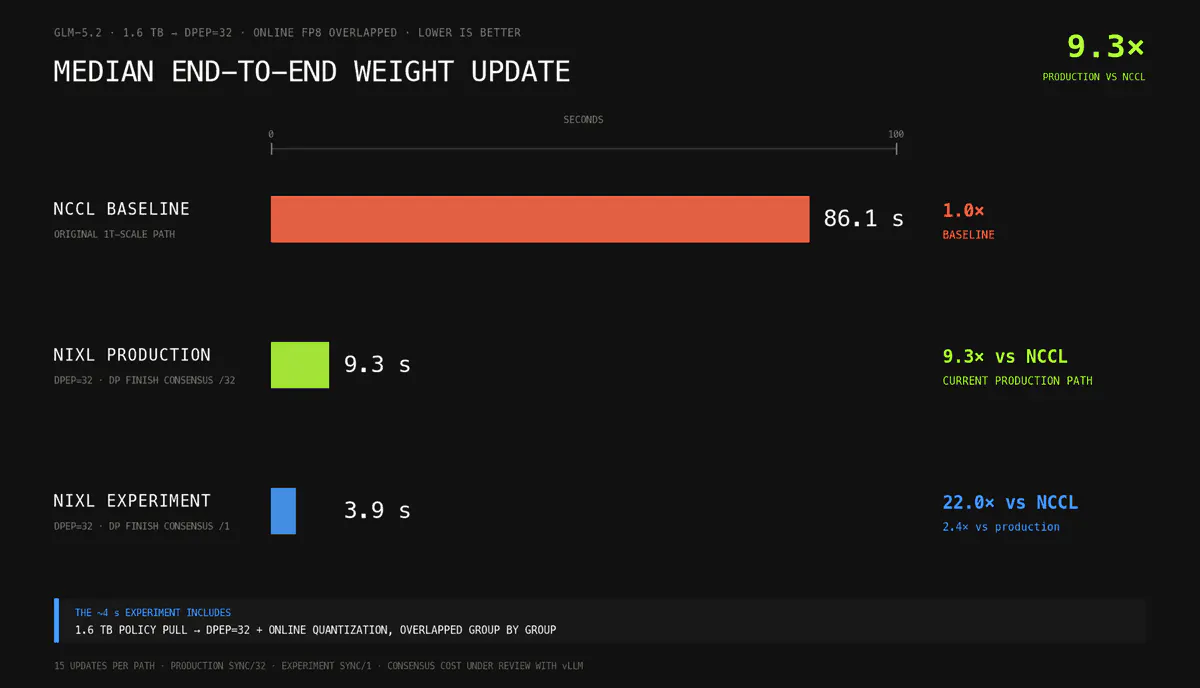
Prime Intellect rebuilt weight sync on RDMA and vLLM tracing, dropping GLM-5.2's 1.6TB policy transfer from 86 seconds to under 4.
Hermes Desktop now auto-detects your hardware, picks a fitting local model, downloads it, and configures the runtime without any manual setup.
A new attention kernel unlocks Blackwell's FP4 tensor cores for inference, hitting 2.13x BF16 forward throughput on GB200 while training stays partly in FP8.
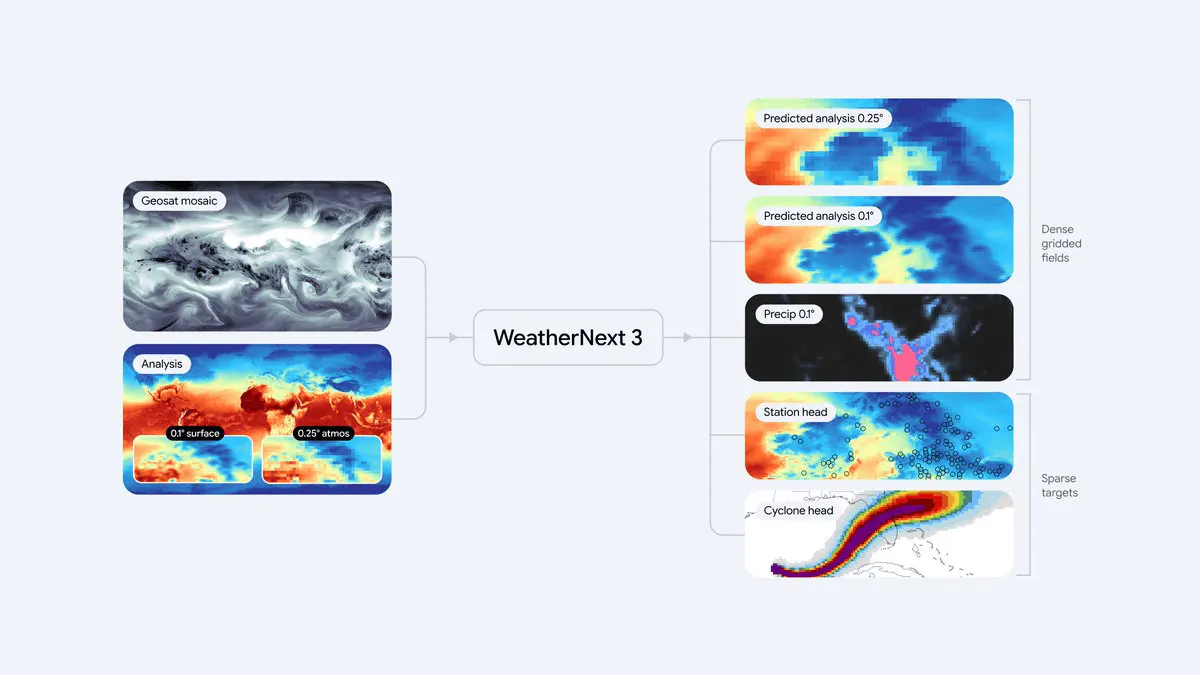
Google DeepMind's new weather AI trains on raw satellite feeds and station data, delivering hourly 5km forecasts with up to 50% better rain accuracy.
No stories match these filters.