Back to News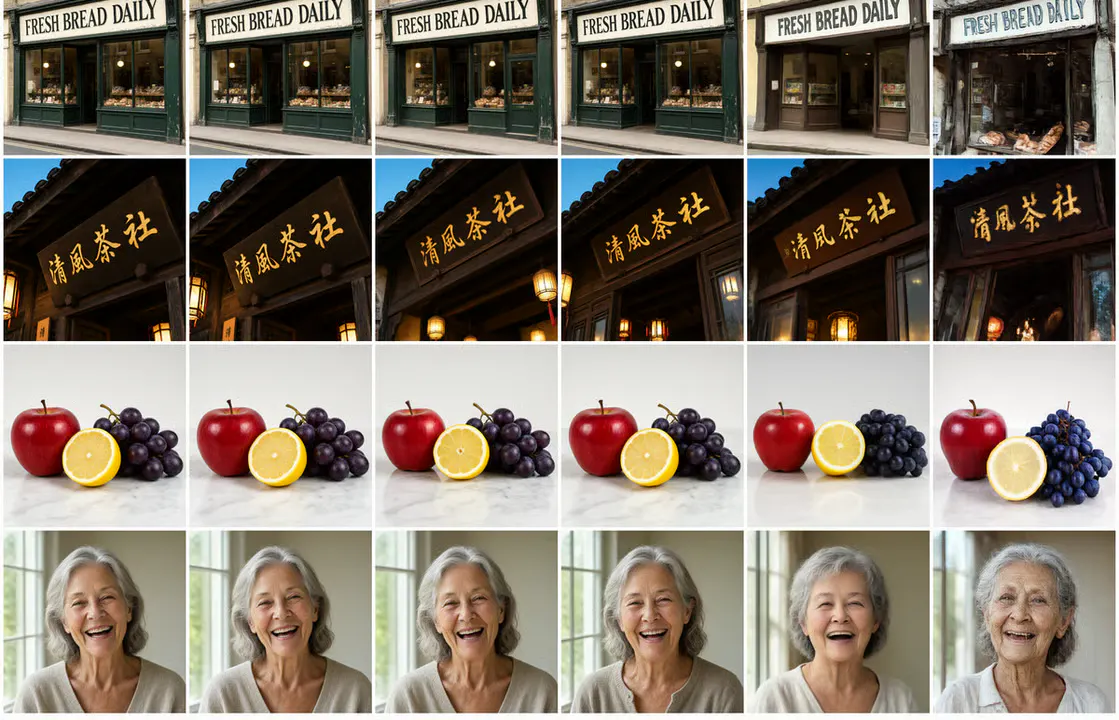
AtomicChat Shrinks Qwen-Image-2.1-Turbo From 14 GB to 2.55 GB
AtomicChat released GGUF quantizations of Qwen's 8-step image model with per-tensor quant layouts that stay 21% closer to BF16 than plain quants.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
AtomicChat released GGUF quantizations of Qwen's 8-step image model with per-tensor quant layouts that stay 21% closer to BF16 than plain quants.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report