

Jina AI's jina-ocr-v1 Parses PDF Pages at 2.57 Pages per Second
Jina AI released jina-ocr-v1, a 3.4B mixture-of-experts document parser with speculative decoding that turns pages into Markdown at 2.57 pages per second.
hermes-ai.net
Read docs →A focused feed of models, agents, research and open-source releases for people building with AI.
Jina AI released jina-ocr-v1, a 3.4B mixture-of-experts document parser with speculative decoding that turns pages into Markdown at 2.57 pages per second.
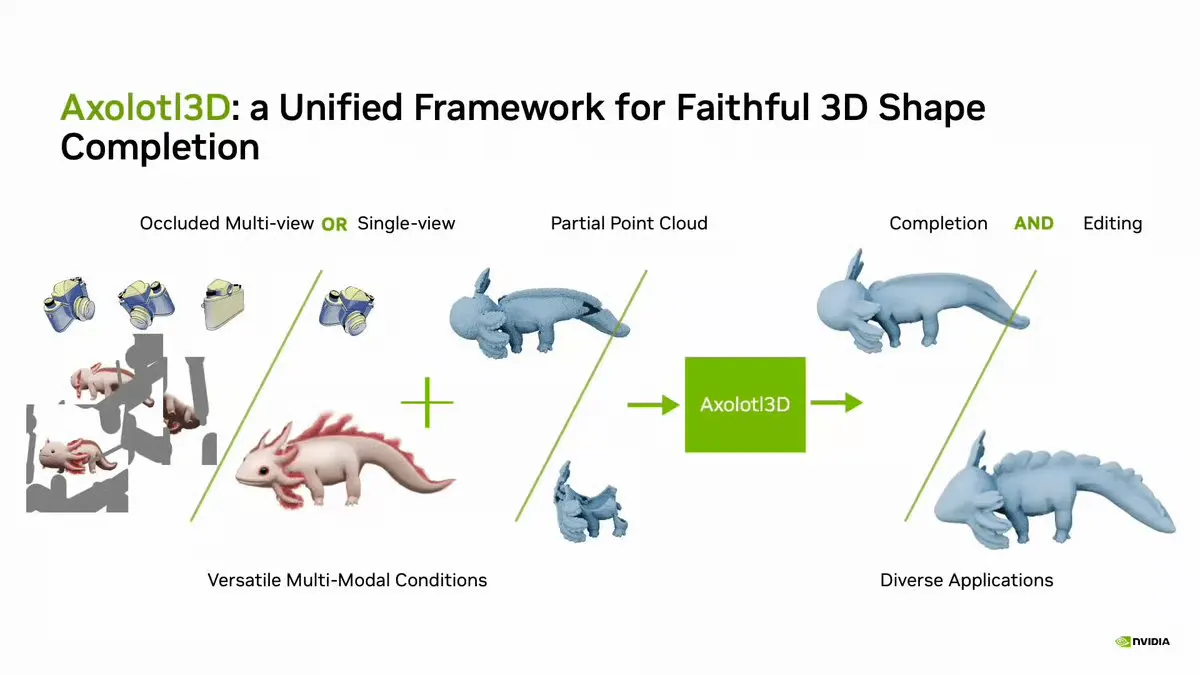
NVIDIA's Axolotl3D fuses images, camera poses, and partial point clouds into one diffusion pipeline that completes occluded 3D shapes faithfully.
Marigold V2 turns Qwen-Image-Edit into a single-step depth, normals, and albedo predictor, fine-tuned on one 32 GB consumer GPU.
Comfy-Org has repackaged the MAP team's YuE2 music model into single-file safetensors, and ComfyUI now ships native nodes to run it.
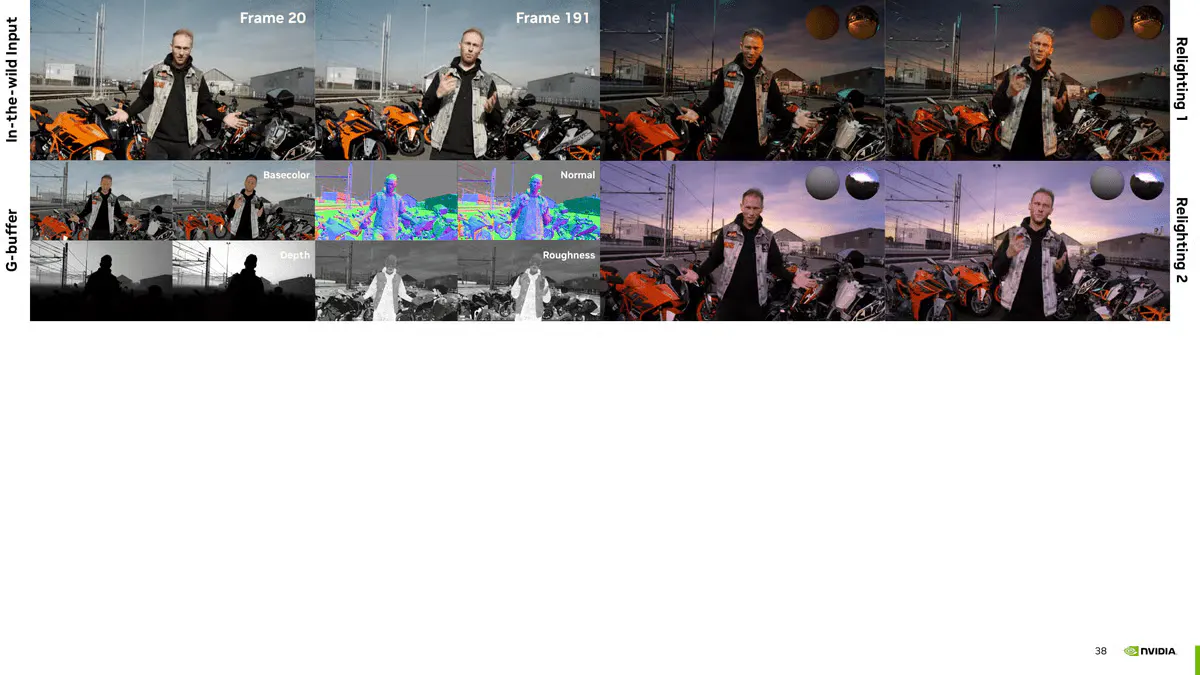
NVIDIA and USC present HorizonRelight, a diffusion transformer method that keeps lighting stable across long videos by propagating context between chunks.
Google Pics packages Nano Banana into a Workspace-native image editor with object-level control, in-image text editing, and live collaboration.
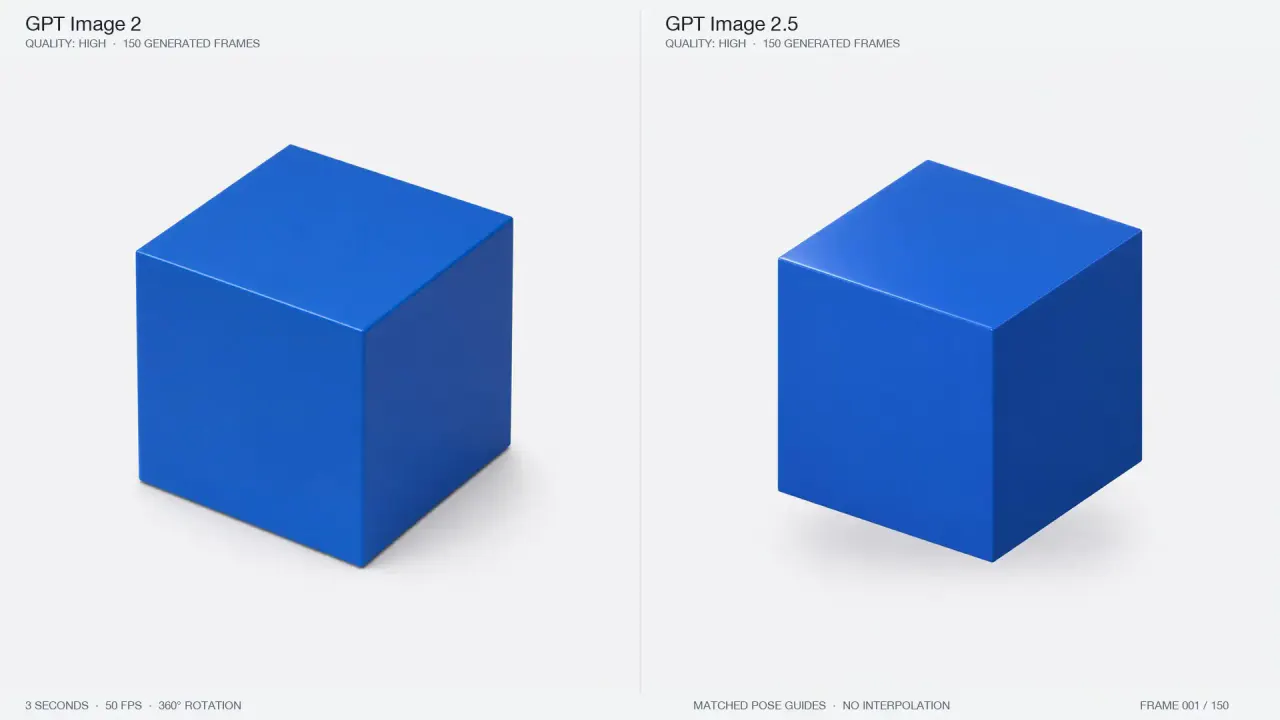
OpenAI's new image model brings 50% faster generation, precision comment-based edits, in-chat sketching, and two new API tiers for developers.
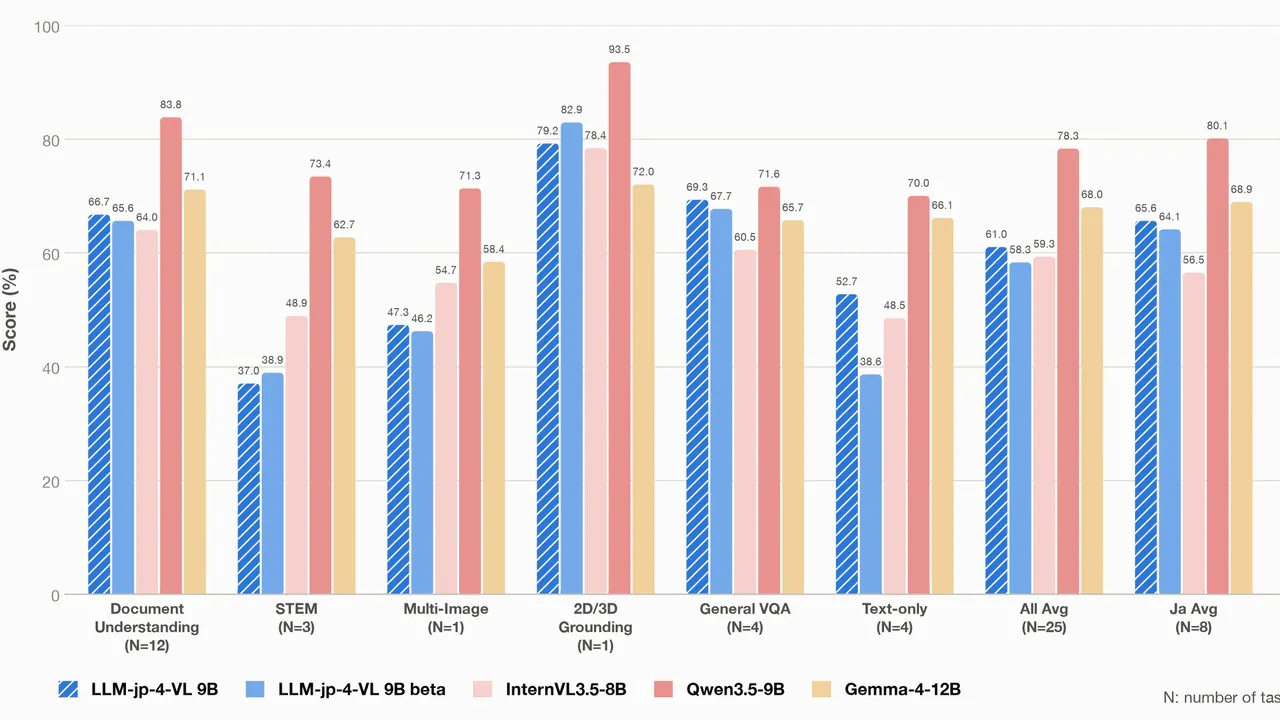
Japan's national LLM project releases an Apache-2.0 vision-language model with reasoning traces, trained on a scrubbed 29M-sample dataset.
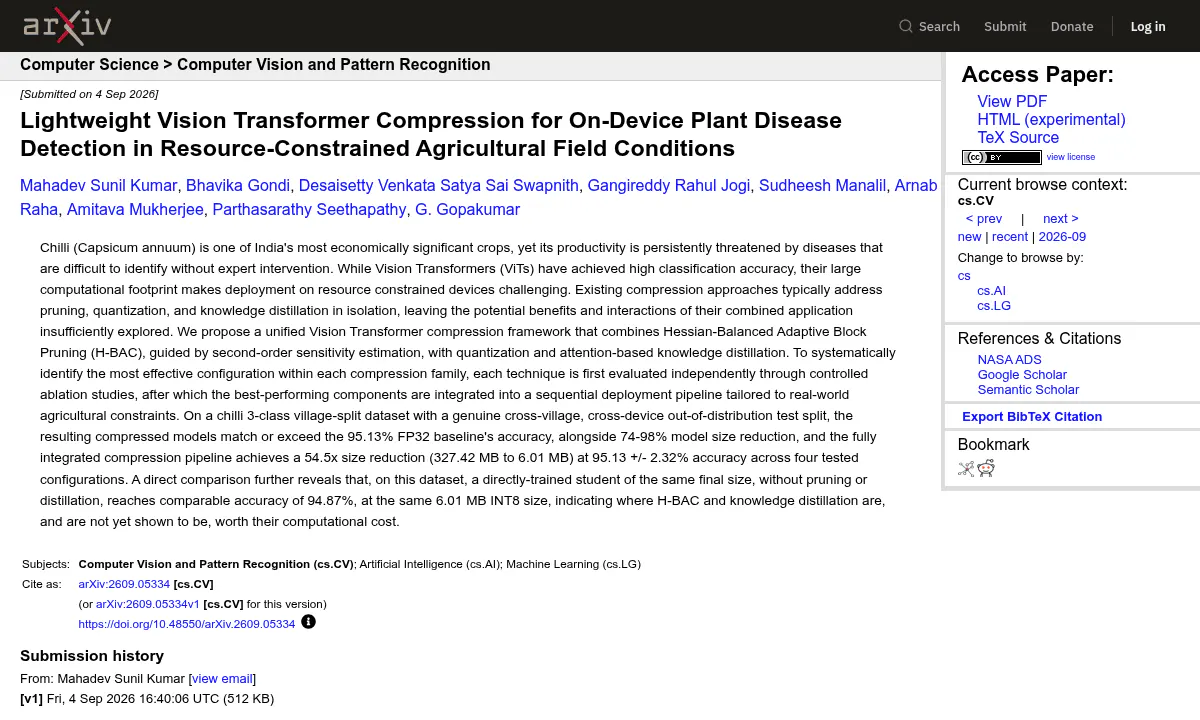
A unified pruning, quantization and distillation pipeline shrinks a Vision Transformer 54.5x while holding 95.13% accuracy on out-of-distribution chilli disease images.

InclusionAI open-sources a 124B-parameter mixture-of-experts vision-language model with 5.5B active parameters, 256K context, and MIT license.
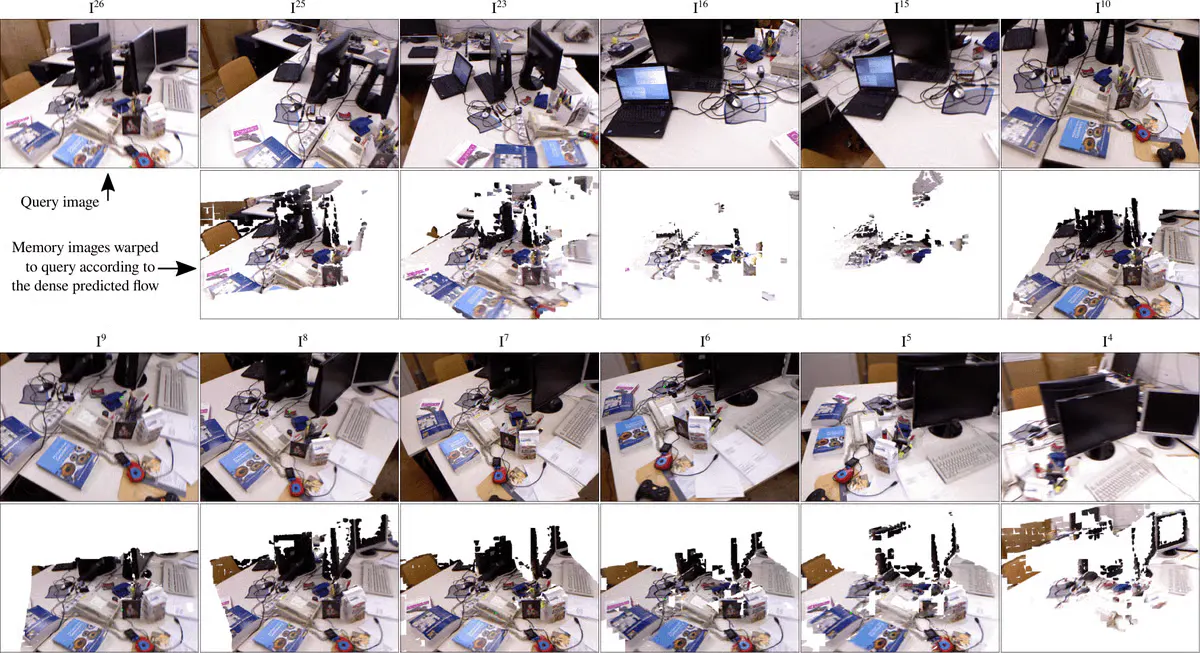
A new hybrid Structure-from-Motion framework from NAVER Labs unifies real-time SLAM and offline reconstruction, beating even calibrated systems while running uncalibrated.
Krea opens the beta for a new agent platform that turns natural-language prompts into finished visual assets, sitting on top of its existing creative suite.
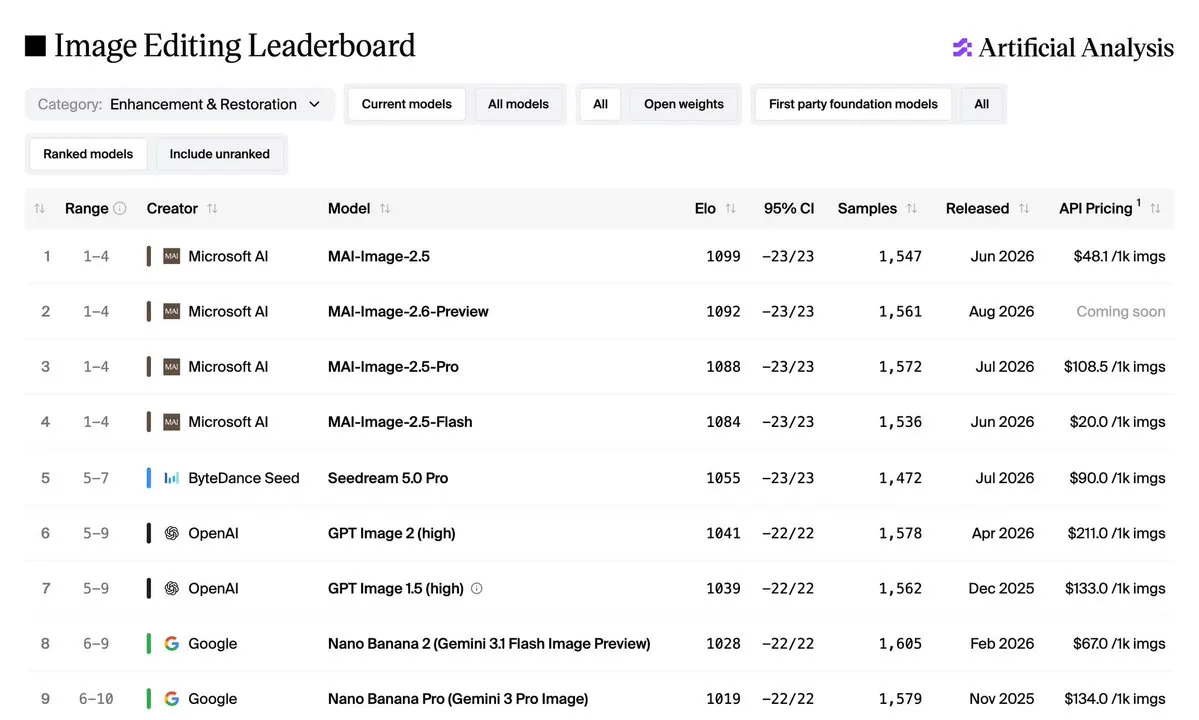
Artificial Analysis rebuilt its Image Editing Arena with a two-axis taxonomy of editing actions and use cases, revealing which model wins each specific task.
A new frequency-domain training objective for pixel-space flow matching cuts convergence time by up to 40% without touching the architecture.
DeepSeek gives its Flash model eyes with an experimental multimodal release that matches Claude Opus 4.8 on agent tasks at a fraction of the cost.
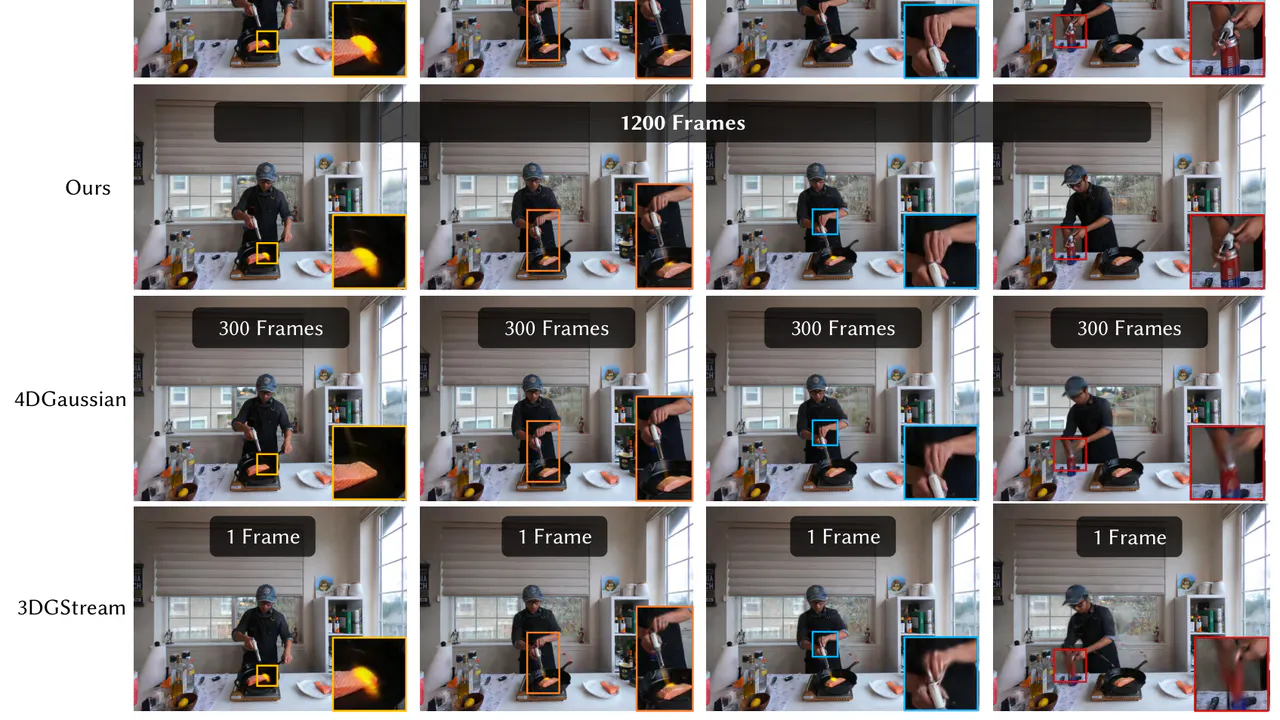
A new Gaussian splatting framework reconstructs volumetric videos with thousands of frames of complex motion, extending prior methods by roughly 70x in temporal coverage.
Krea previews a next-generation foundation model with strong editing plus a dedicated agent platform for creative work with MCP and API hooks.
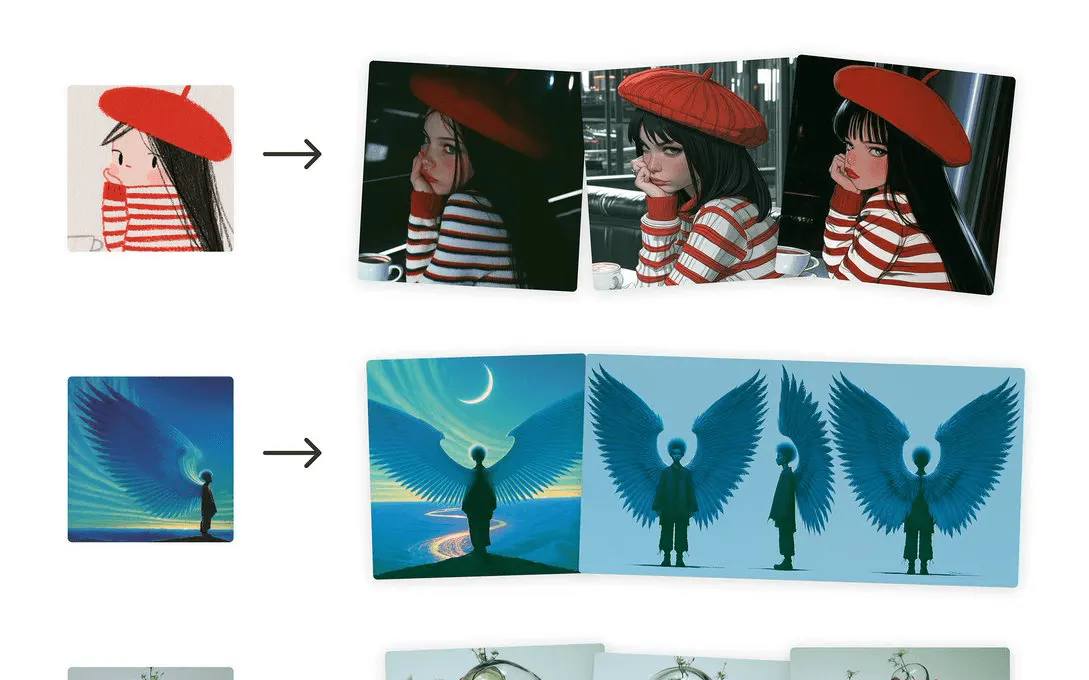
Midjourney is testing a V8.2 edit model that handles instruction-based editing, multi-image composition, inpainting, and outpainting in one system.
A 26B multimodal Gemma variant with refusal directions surgically removed lands on Hugging Face in GGUF format, ready for llama.cpp.
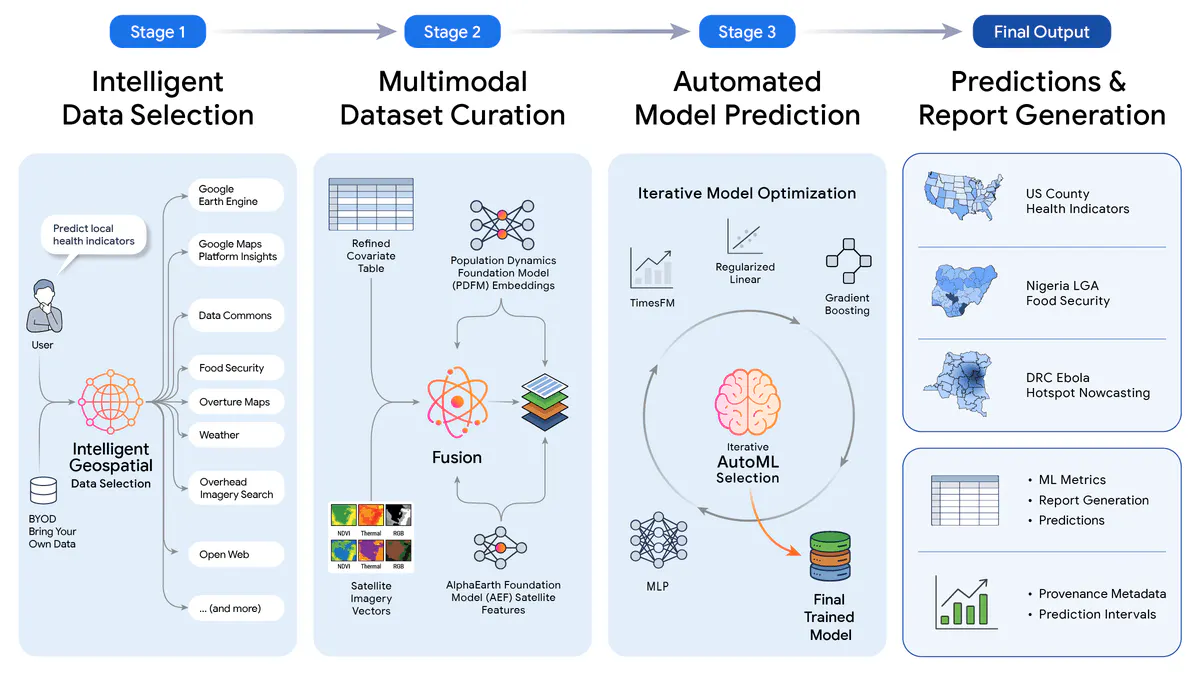
Google Research unveils an autonomous AI system that turns natural-language questions about food security, disease, and climate risk into trained geospatial models in minutes.
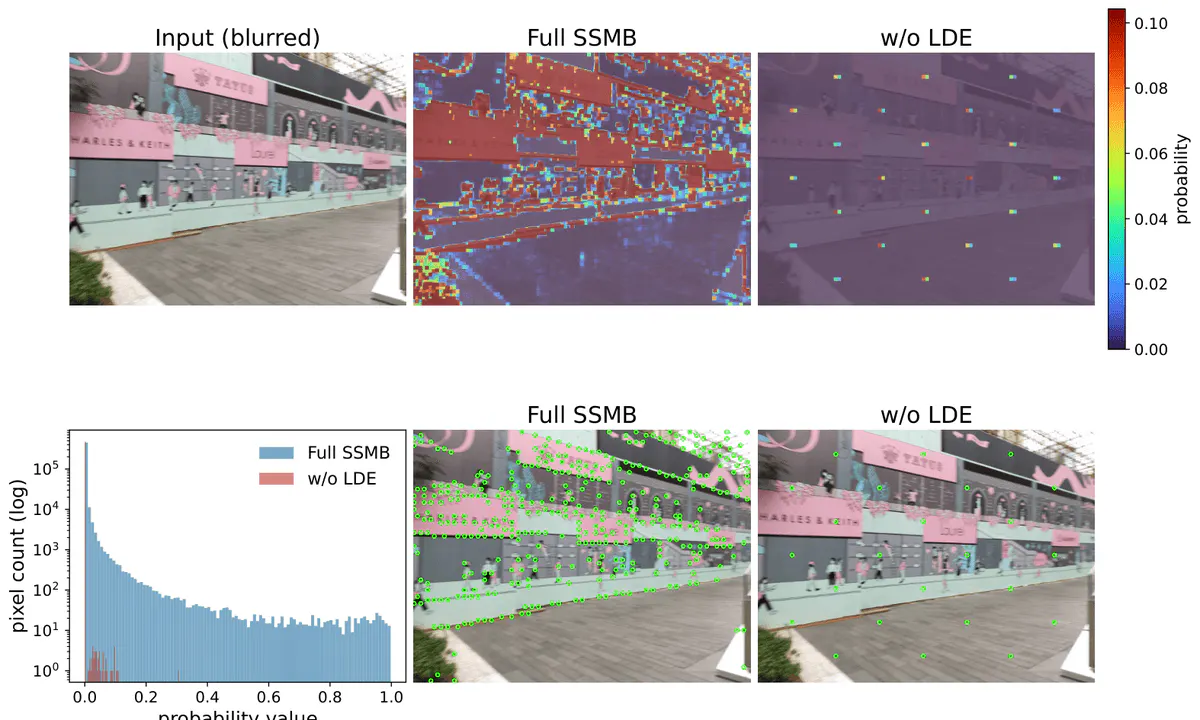
A new keypoint detector skips deblurring entirely, learning directly from blurred images through self-supervision and beating supervised baselines on matching and localization.
A group of vision researchers argues that pure vision, not language-tethered multimodal models, could be its own route to general intelligence.
A new agent skill turns a single reference image into diffable TypeScript that procedurally reconstructs the object as an animation-ready Three.js scene.
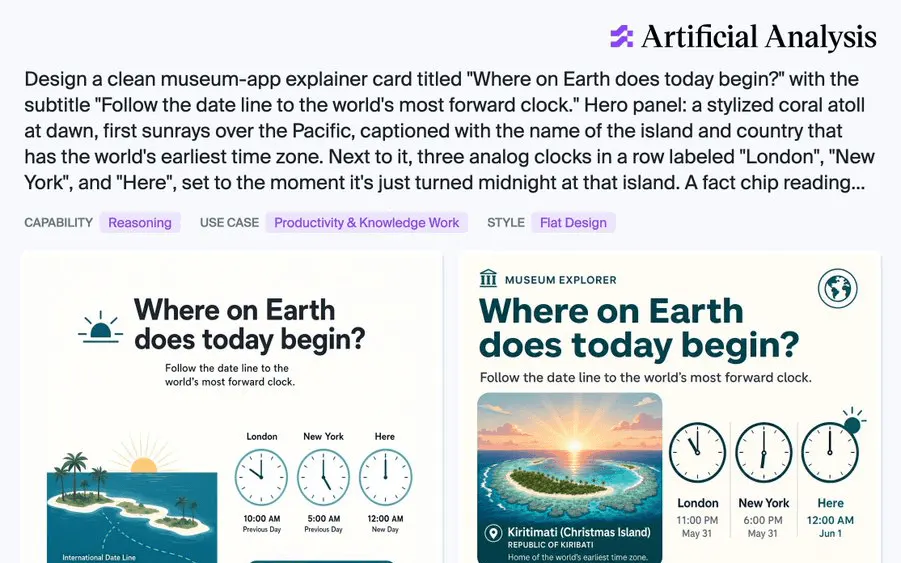
Alibaba's third-generation image model debuts at #6 in editing and #9 in text-to-image, with big Elo jumps and a productivity-first pitch.
No stories match these filters.