Back to News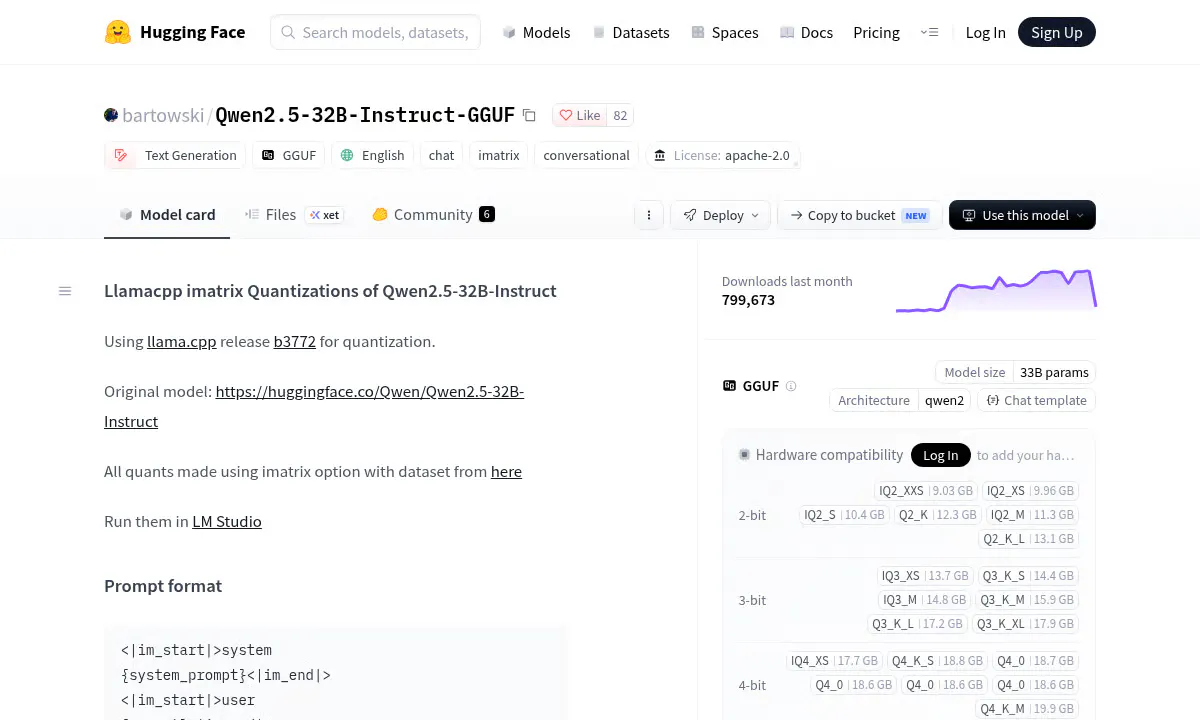
Bartowski Packs Qwen2.5-32B Into a 9GB File for Local Machines
A full set of imatrix GGUF quantizations lets you run Qwen2.5-32B-Instruct locally, from a 9GB phone-friendly build up to lossless 65GB weights.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A full set of imatrix GGUF quantizations lets you run Qwen2.5-32B-Instruct locally, from a 9GB phone-friendly build up to lossless 65GB weights.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report