APIUp to 28% cheaper than official pricesTry the API →
Hermes
// Intelligence

Llms

A focused feed of models, agents, research and open-source releases for people building with AI.

Updated
01
Swift 1.5 Heretic Build Cuts Refusals but Slows Decoding Speed by 28%
modelLlmsGpusAlphaSignal ·

Swift 1.5 Heretic Build Cuts Refusals but Slows Decoding Speed by 28%

Partially decensored GGUF of Swift 1.5 Qwen3.8-27B built with Heretic , with vision and MTP intact. Scores 97.6% GSM8K, 86.67% MMLU-Pro, 92.98% IFEval prompt-strict on the quantized file. Follows through on roughly 1 in 5 prompts the original Swift 1.5 refused; not fully uncensored.
03
Google Runs Gemma 4 on a TPU in Orbit for the First Time
newsLlmsGpusGoogle Gemma ·

Google Runs Gemma 4 on a TPU in Orbit for the First Time

Google's Project Suncatcher ran Gemma 4 on a data-center TPU in orbit, returning a haiku to Earth. Prototype satellite named MVP, built with Planet, launched Oct 1 on SpaceX Transporter-18. Carries four Trillium-generation TPUs running on roughly a 1 kW solar power budget.

06
ETH Zurich's LSA Slashes 10-Million-Token AI Processing by 72x
paperLlmsInfraAlphaSignal ·

ETH Zurich's LSA Slashes 10-Million-Token AI Processing by 72x

Prefrontal AI and ETH Zurich introduce Latent Sparse Attention (LSA), targeting the indexer bottleneck at 10M-token context At ultra-long context, the key-selection indexer consumes about 98% of a sparse attention layer's runtime LSA clusters keys hierarchically in a learned latent space so queries

11
A Developer Compiled a Full RISC-V CPU Into Qwen3.5's Weights
modelLlmsOpen SourceAlphaSignal ·

A Developer Compiled a Full RISC-V CPU Into Qwen3.5's Weights

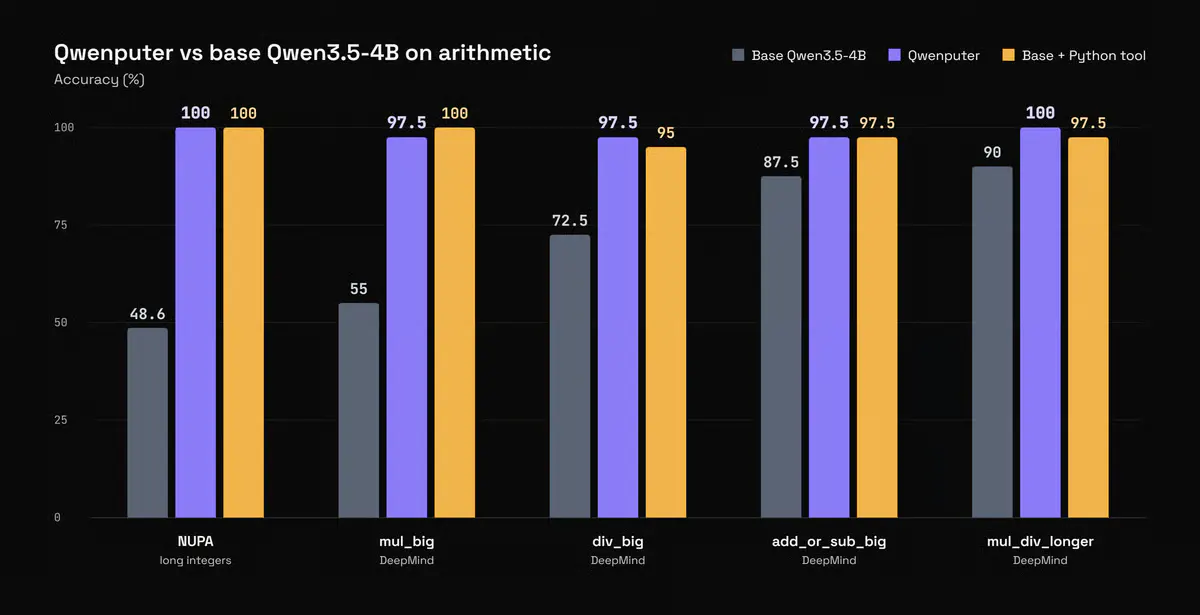
Qwenputer compiles a 32-bit RISC-V CPU directly into Qwen3.5-4B's weights , no external runtime. Gated DeltaNet layers become addressable RAM via one-hot keys with gate and write strength pinned to 1. Benchmarks: 100% on NUPA versus 48.6% base Qwen; 97.5% on DeepMind mul_big versus 55% base.

15
OpenGVLab's InternVL2-1B Beats Larger 4B Vision Models at Under 2GB
modelImageLlmsAlphaSignal ·

OpenGVLab's InternVL2-1B Beats Larger 4B Vision Models at Under 2GB

OpenGVLab released InternVL2-1B , a 0.9B parameter vision language model under MIT license. Combines InternViT-300M-448px vision encoder with Qwen2-0.5B-Instruct language backbone via MLP projector. Scores 754 on OCRBench, beating larger PaliGemma-3B (614) and Mini-InternVL-2B (654).

18
Sharp-Spark Squeezes a 4B Coding AI Into 6 GB GPUs
modelGpusLlmsAlphaSignal ·

Sharp-Spark Squeezes a 4B Coding AI Into 6 GB GPUs

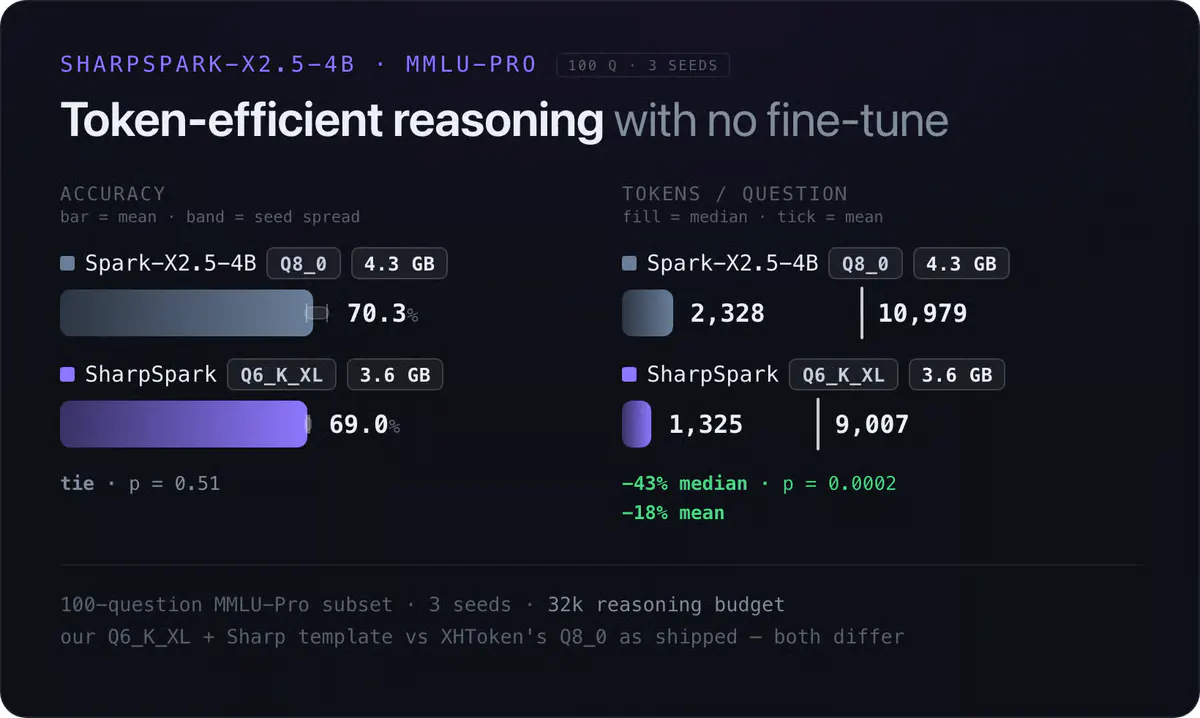
Sharp-Spark-X2.5-4B-GGUF is an imatrix-quantized repack of Spark-X2.5-4B targeting 6 GB VRAM GPUs. Q6 ties upstream Q8 on MMLU-Pro while using 43% fewer tokens at the median. Ties Anthropic Haiku 4.5 on an SWE-bench-Live slice at 4B parameters.

23
Zyphra's ZHA Tree Router Scans Just 2.8% of Keys at 256K Tokens
paperLlmsInfraAlphaSignal ·

Zyphra's ZHA Tree Router Scans Just 2.8% of Keys at 256K Tokens

Zyphra introduces ZHA , a tree-structured sparse attention that is asymptotically subquadratic. Queries descend a tree of compressed KV summaries, skipping entire branches instead of scoring every key. Projected speedups: 35x over dense at 10M tokens, up to 417x at 1B tokens.