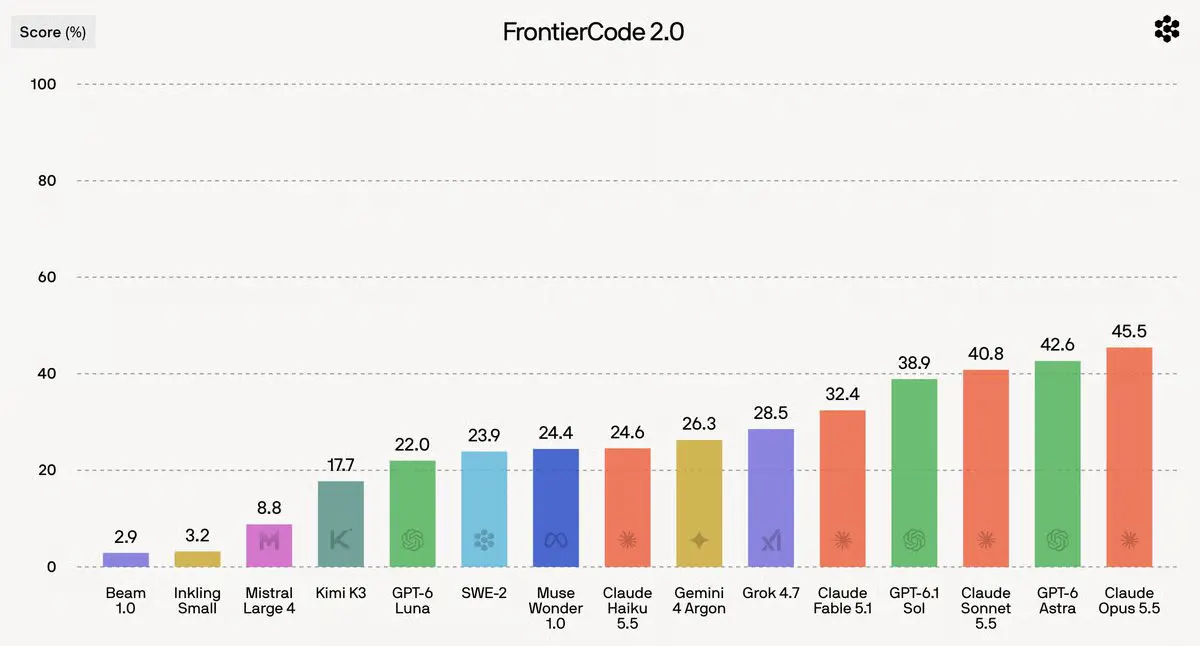
Cognition's FrontierCode 2.0 Reveals Every AI Coder Fails Half of Real Engineering Tasks
Cognition's new coding benchmark tests whether agents respect unstated constraints, with top model Opus 5.5 scoring just 45% on tasks maintainers built over 40+ hours each.
Source
Cognition
Published
Author
AlphaSignal Newsroom
Read
1 min read
Cognition's new coding benchmark tests whether agents respect unstated constraints, with top model Opus 5.5 scoring just 45% on tasks maintainers built over 40+ hours each.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.