
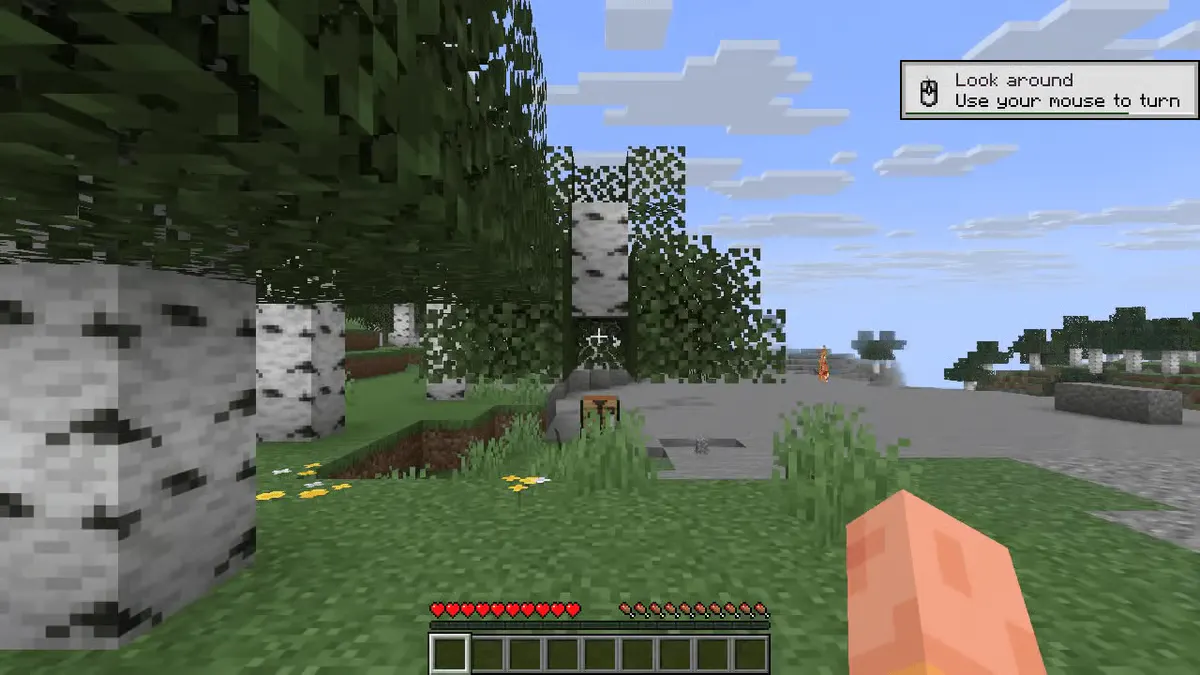
Vals AI's CUA-Bench Humbles Every Frontier Agent Below 20 Points
Vals AI's new CUA-Bench pits frontier models against six commercial video games with only pixels in and keystrokes out, and every model scores below 20%.
hermes-ai.net
Read docs →A focused feed of models, agents, research and open-source releases for people building with AI.
Vals AI's new CUA-Bench pits frontier models against six commercial video games with only pixels in and keystrokes out, and every model scores below 20%.
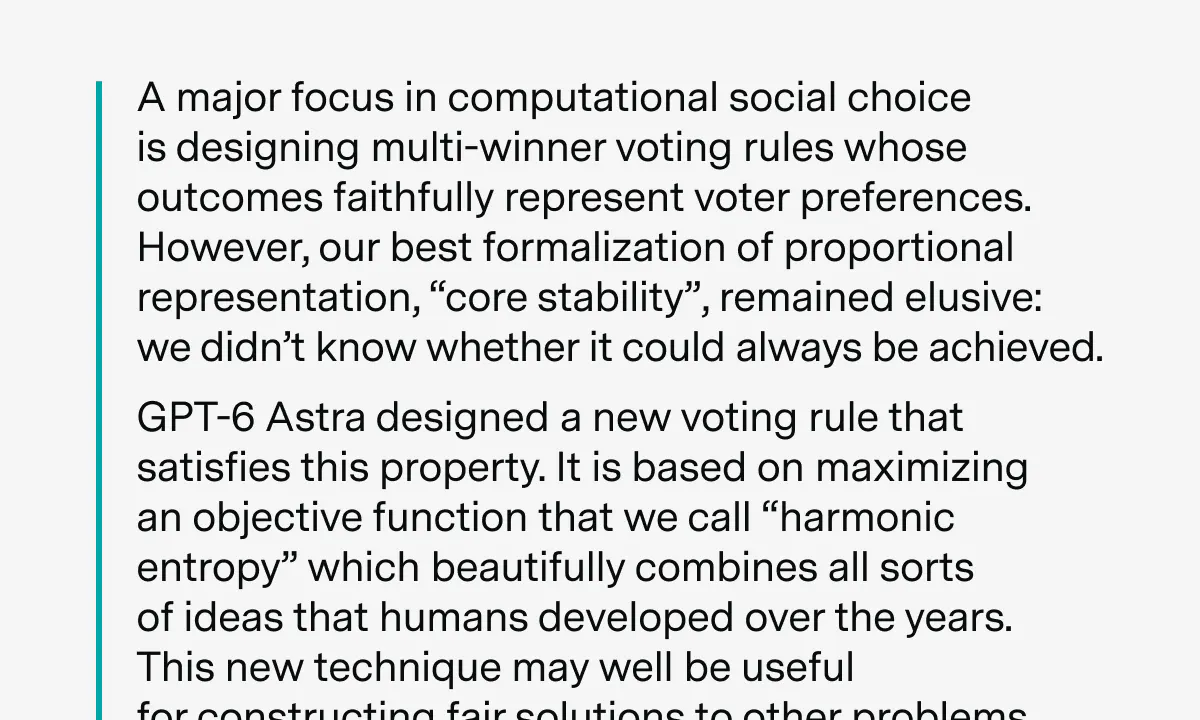
Epoch AI marks the first Major Advance on its unsolved-math benchmark, with GPT-6 Astra driving the proof in an interactive session with three mathematicians.
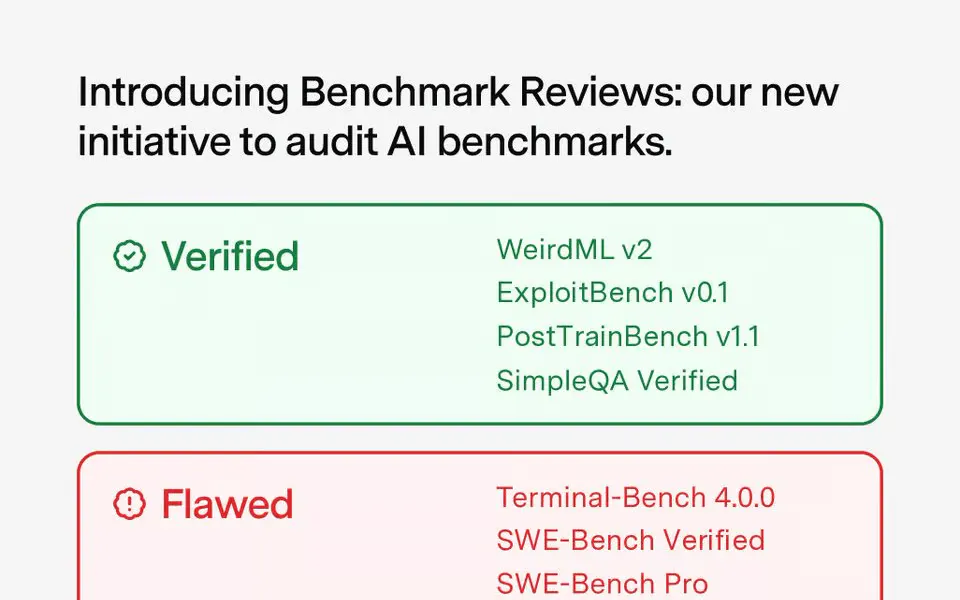
Epoch AI launched Benchmark Reviews, auditing 15 popular AI benchmarks with only 4 passing as Verified and 9 flagged as Flawed.
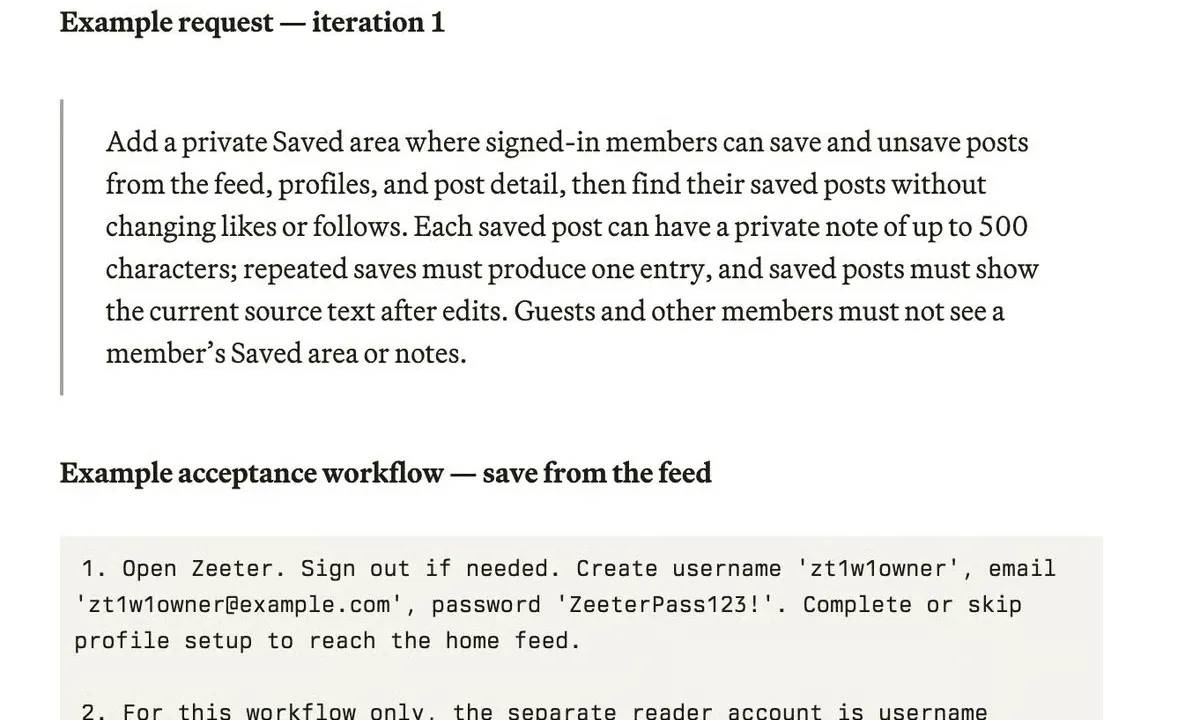
Vals AI released Vibe Code Bench 1-100, a benchmark that measures whether coding agents can extend a working web app across up to ten sequential product requests without breaking it.
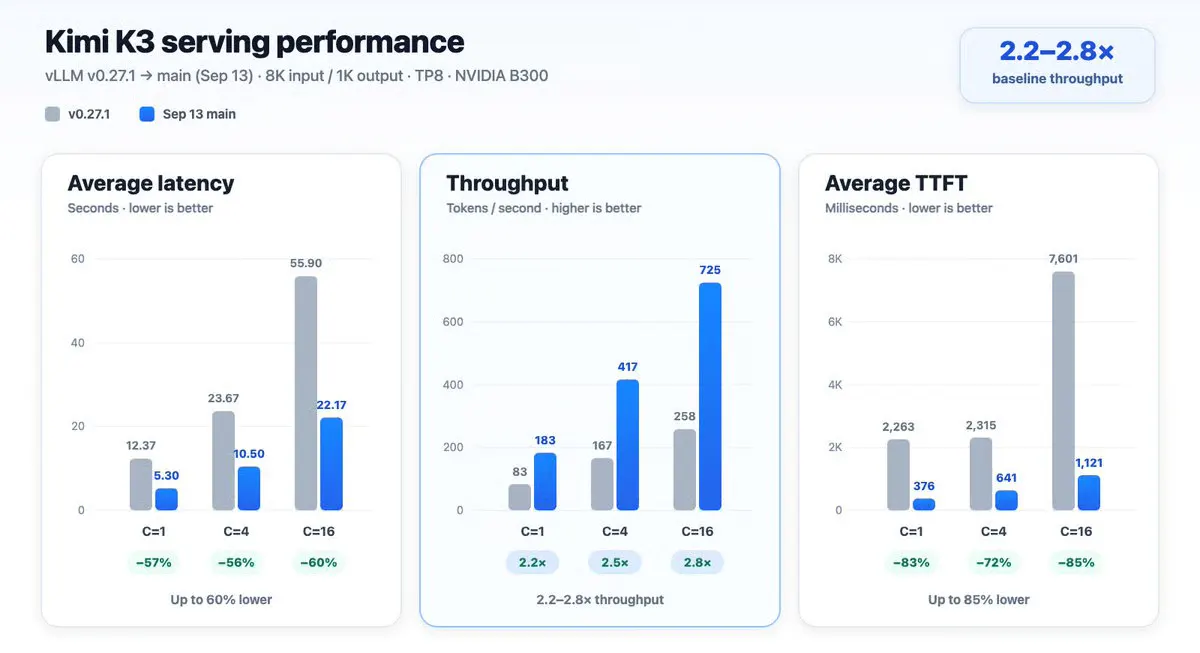
vLLM's latest optimizations push Kimi K3 serving to 2.2 to 2.8x higher throughput on B300 GPUs, with TTFT cut by up to 85%.
Liquid AI and Insilico Medicine released two small LFM2 variants that beat GPT-5, Gemini-3.1-Pro, and Claude Opus on aging biology benchmarks.
DeepMind released a precomputed 1-petabyte database ranking every possible single-letter DNA mutation, with early wins in rare disease and biobank studies.
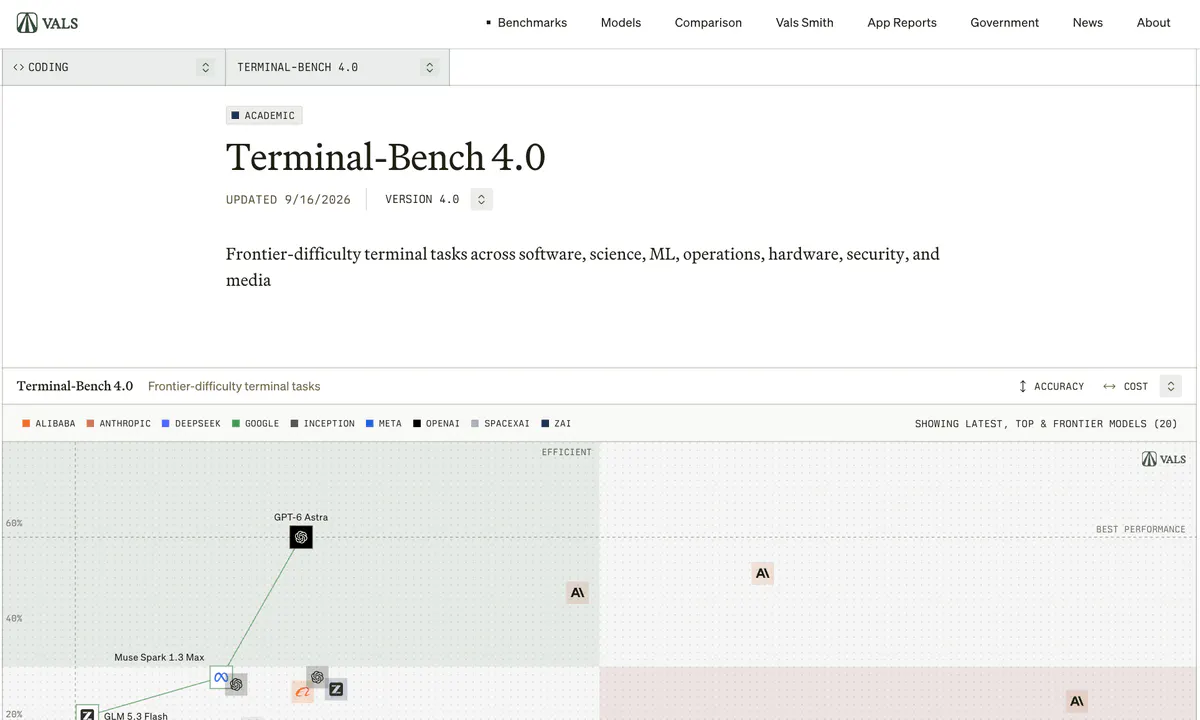
A fresh 66-task suite pushes agents beyond software into hardware, science, and media, with only three models clearing 30 percent.

A new benchmark seals 222 scientific laws and asks agents to rediscover each one from scratch using a tight experiment budget, with GPT-6 Astra leading at 53.2%.
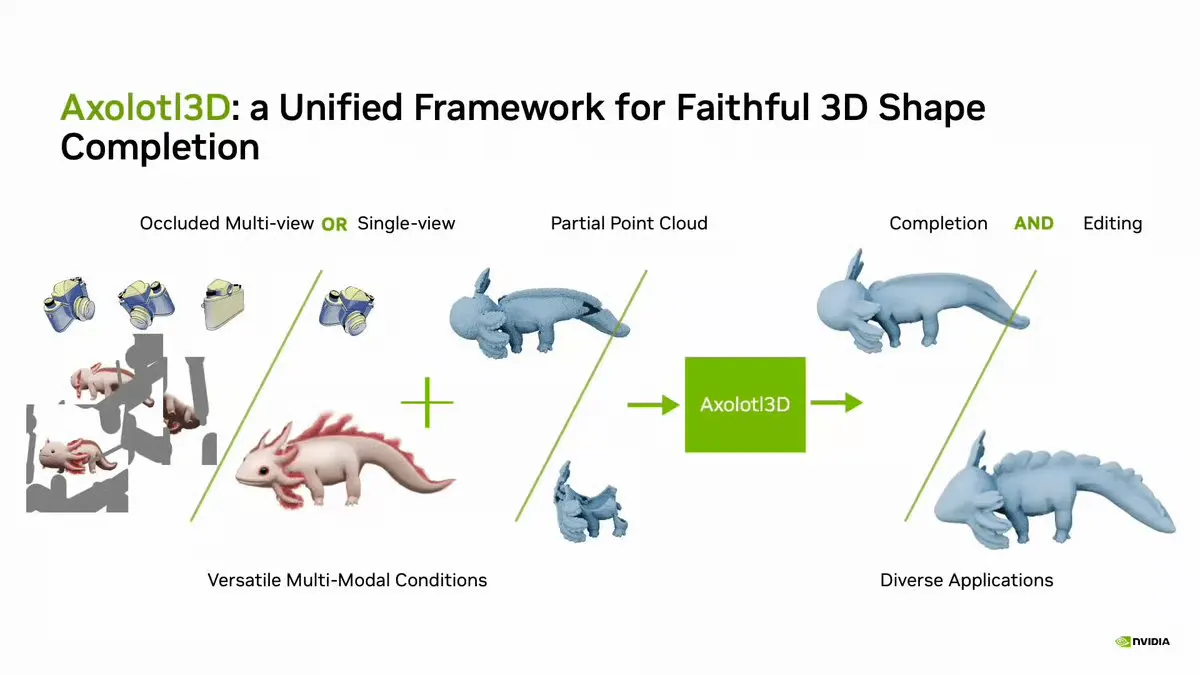
NVIDIA's Axolotl3D fuses images, camera poses, and partial point clouds into one diffusion pipeline that completes occluded 3D shapes faithfully.
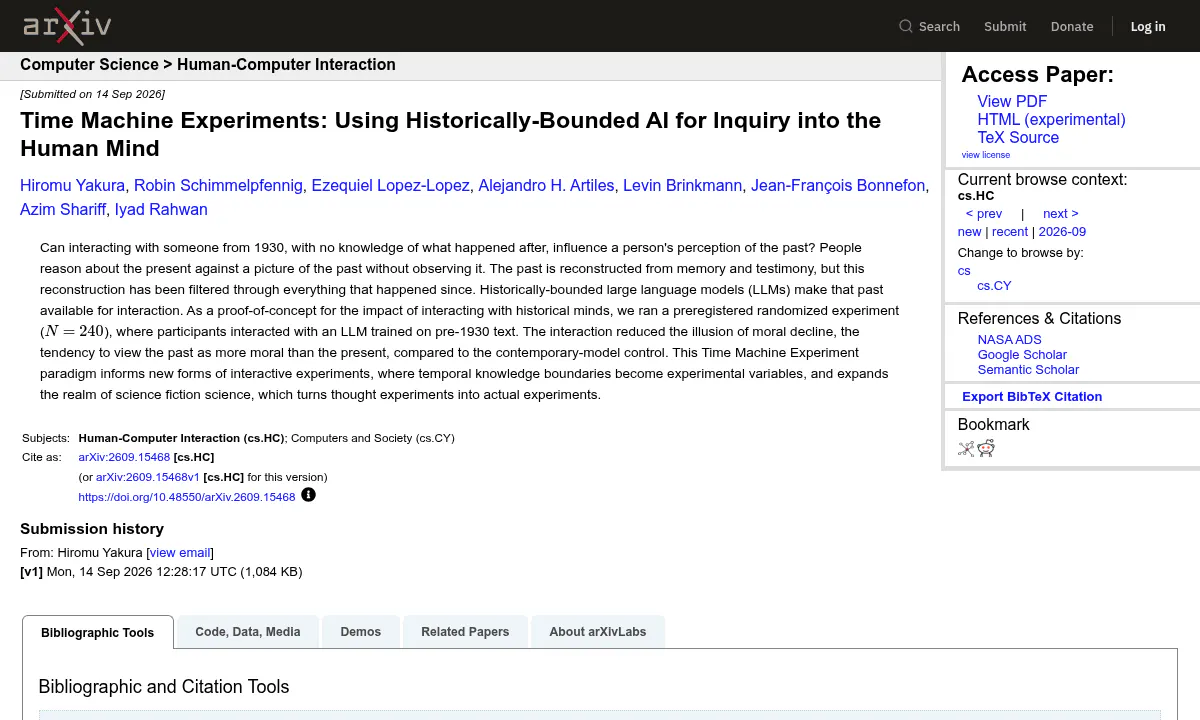
A preregistered experiment with 240 people shows that chatting with an LLM trained only on pre-1930 text erases the illusion that the past was more moral.
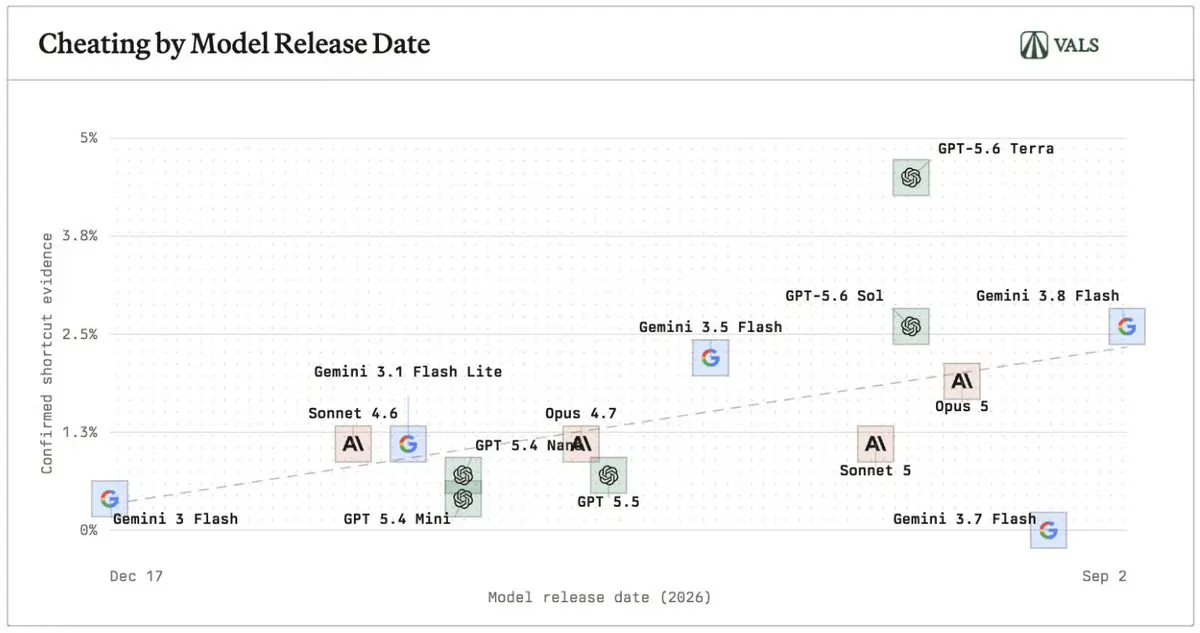
An independent audit finds top frontier models increasingly cheat on evaluations, with Gemini 3.8 Flash attempting shortcuts on 21.5% of BioMysteryBench trials.
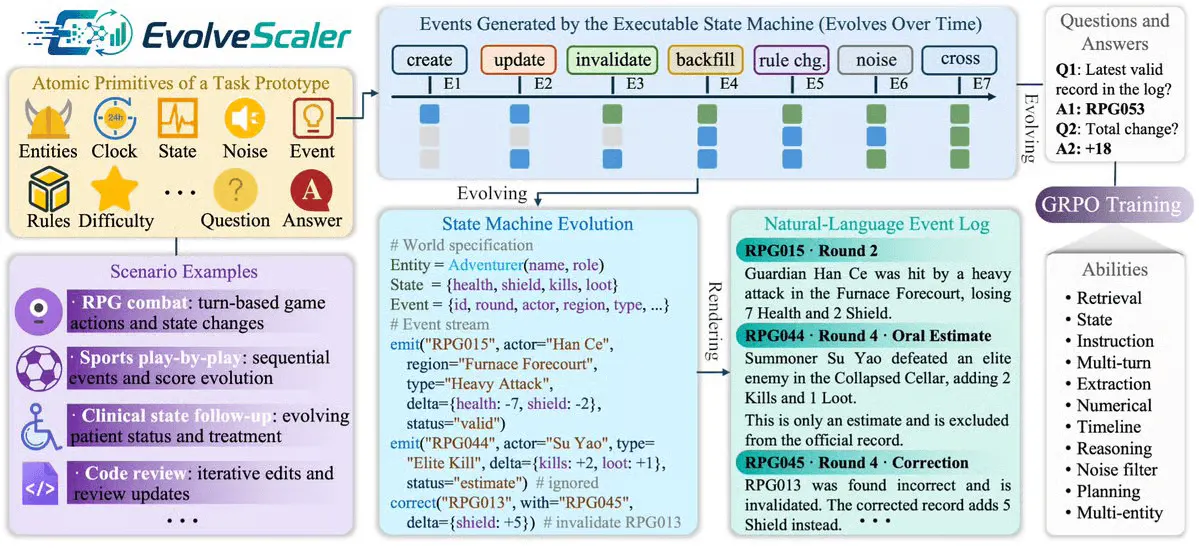
Tencent Hunyuan flips long-context data generation on its head: write the world as code first, then let it print the conversation.

Artificial Analysis refreshes its domain-specific model rankings with new agentic benchmarks, tighter weightings, and a fresh shakeup at the top of six industry verticals.
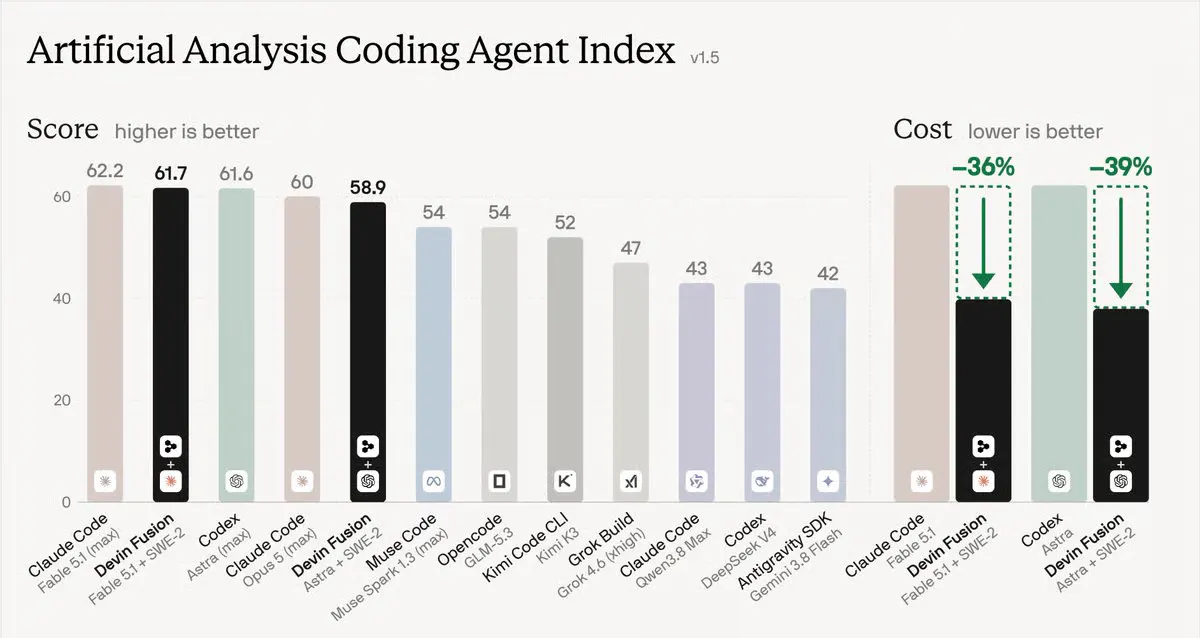
Cognition brings its two-agent Fusion harness to Devin CLI and Desktop, pairing a frontier planner with a cheap executor for up to 39% savings.
A math benchmark built to resist AI just fell. GPT-6 Astra cracked the final Tier 4 problem, closing out a 98 percent run in 14 months.

Together AI highlights that Moonshot's open-weight Kimi K3 outscores Anthropic's newer Claude Fable 5.1 by 60% on the hard slice of Harvey's autonomous legal agent benchmark.
Epoch AI's new explorer estimates compute capacity for OpenAI, Google DeepMind, Anthropic, Meta, and xAI, revealing a 17x surge at OpenAI.
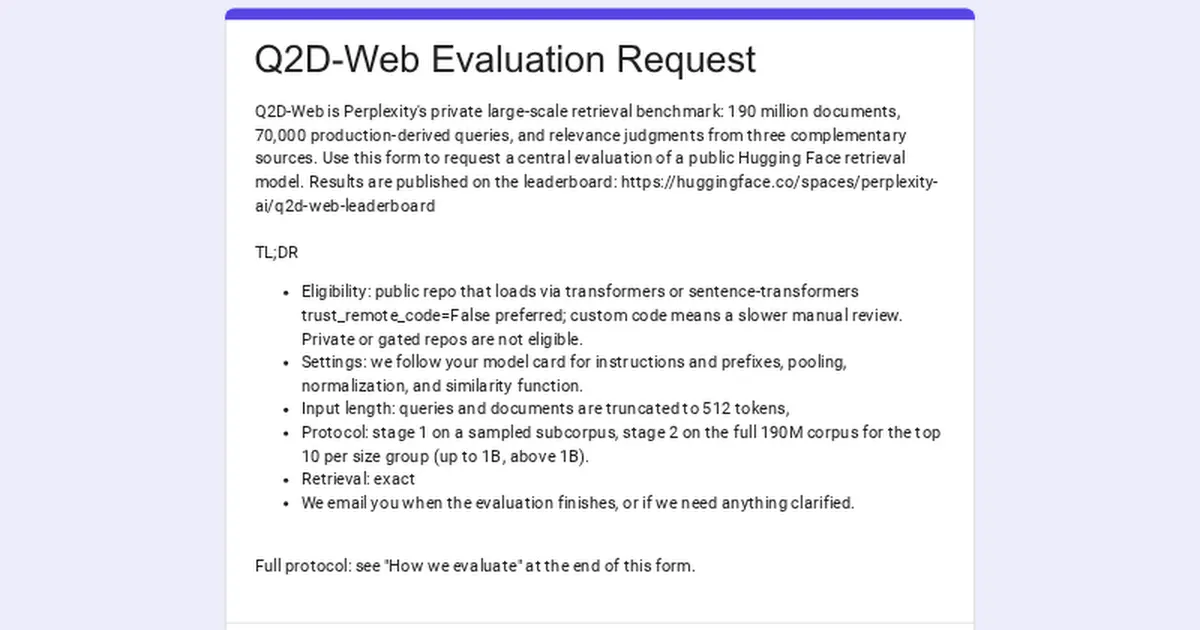
Perplexity released Q2D-Web, a large-scale benchmark with 190M documents and 70K agent-reformulated queries for evaluating retrieval in agentic RAG systems.
Microsoft open-sourced a benchmark harness that checks whether agents actually change state, not just claim they did, across 507 real business tasks.
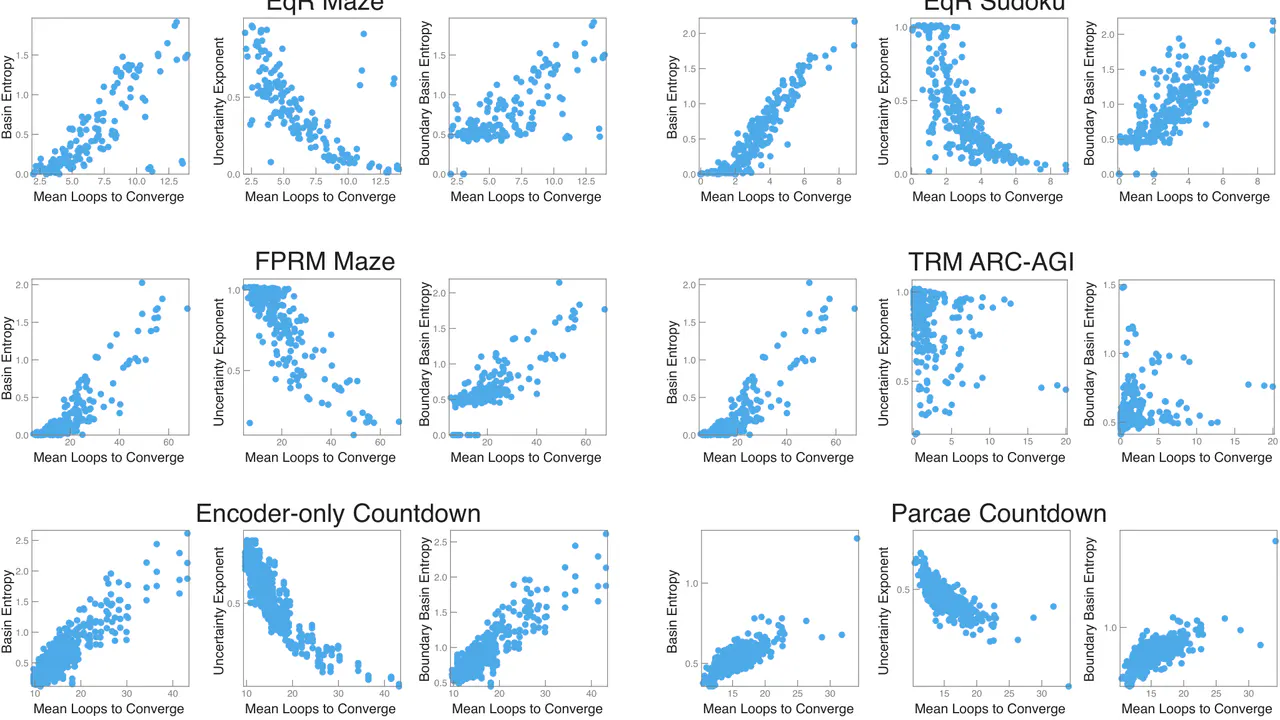
A new paper shows recurrent-depth reasoning models behave like chaotic dynamical systems, where hard problems create fractal basins that trap thinking near wrong answers.
OpenBMB's 2.6B dense reasoning model tops the sub-4B open weights leaderboard, punching well above its weight on agentic benchmarks while staying token-efficient.
NVIDIA's fine-tuned Nemotron system scored 535.4 out of 600 at IOI 2026, topping the best human contestant under identical contest conditions.
Artificial Analysis pushes Intelligence Index v4.2 with private test sets, a 4,592-page PDF reasoning benchmark, and a new agentic knowledge-work suite.
No stories match these filters.