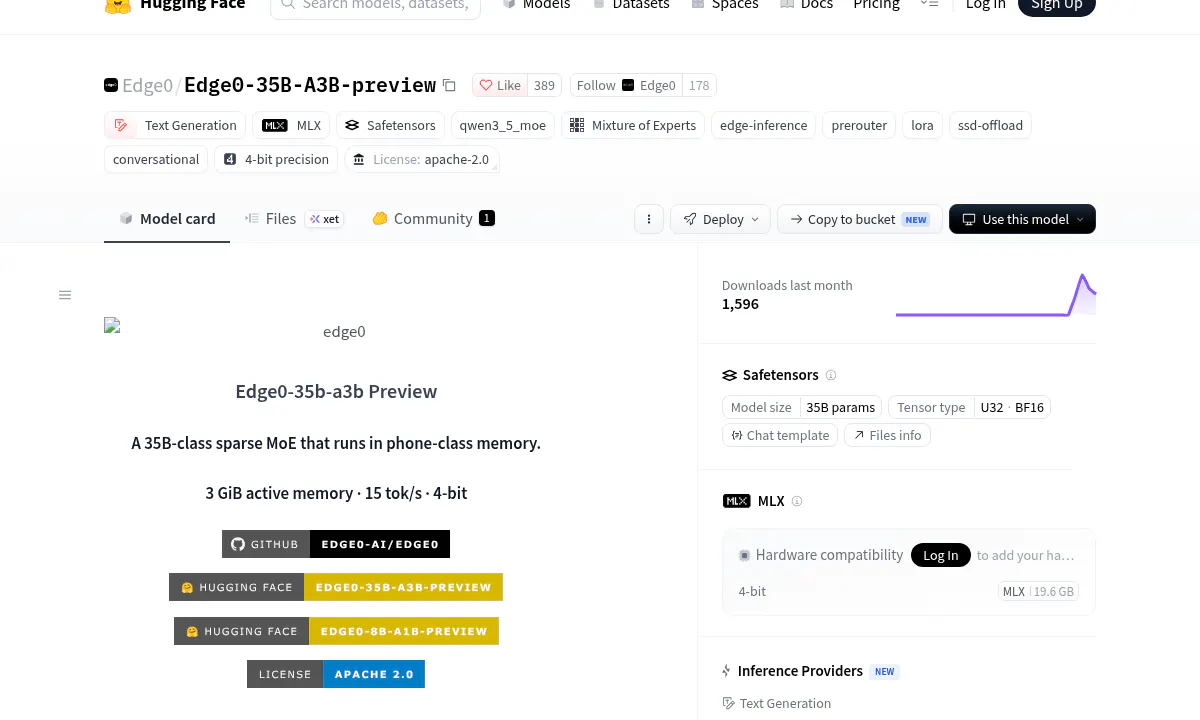
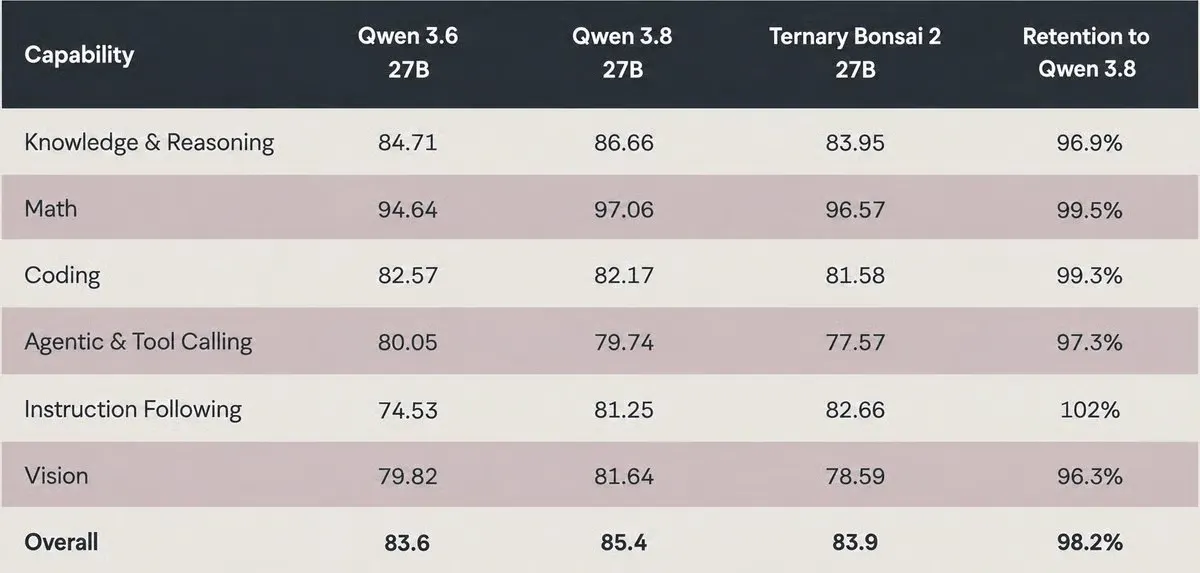
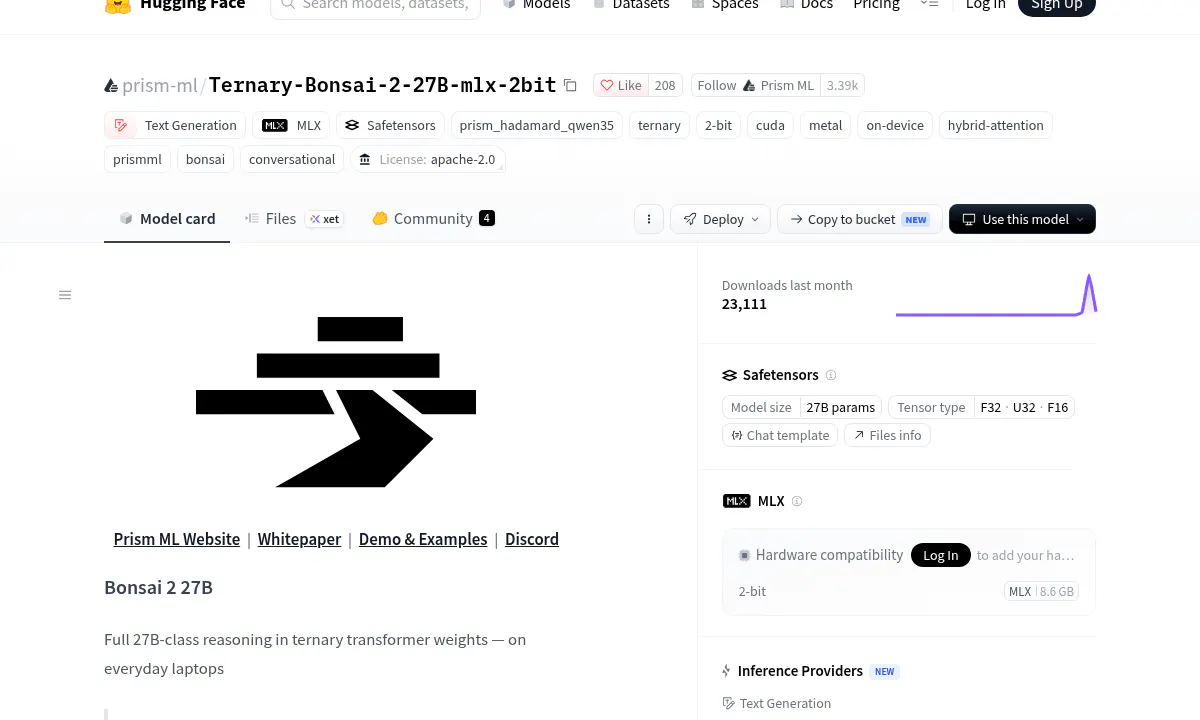
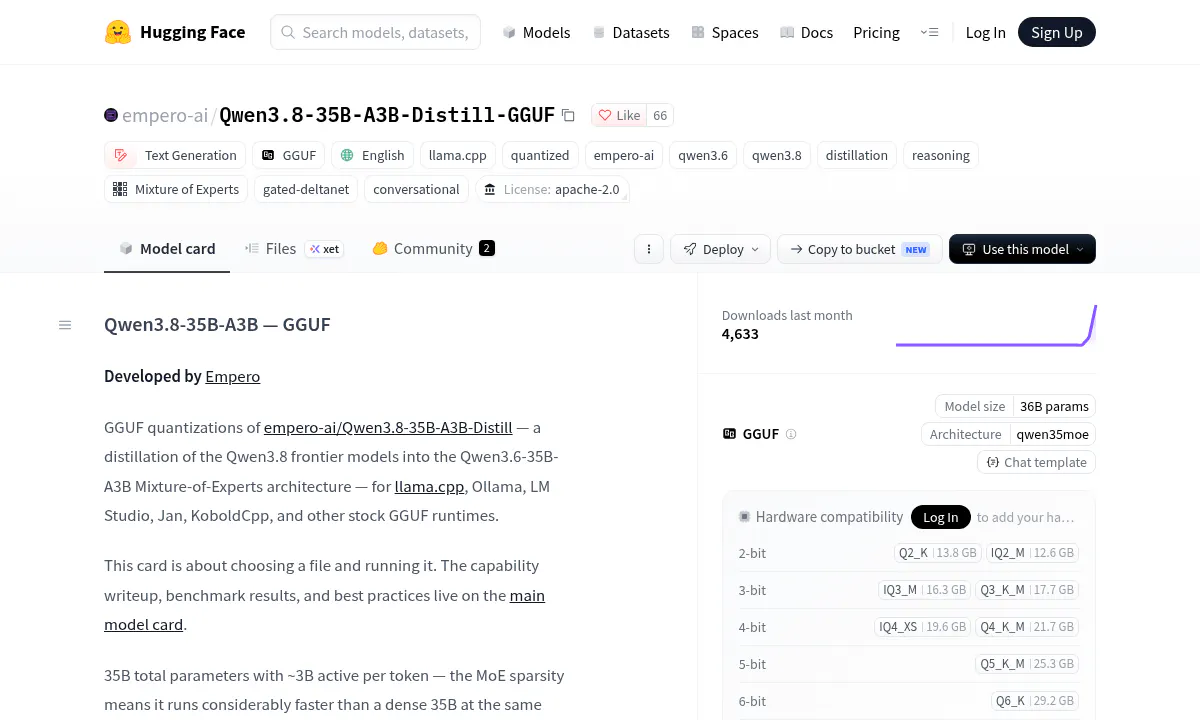
←Back to NewsAI News/LlmsmodelLlmsGpusEdge0 Runs a 35B AI Model on an iPhone With Just 2.9 GiBEdge0 streams a 35B Mixture-of-Experts model from SSD on an iPhone, holding under 3 GB of active RAM while decoding at 15 tokens per second.SourceAlphaSignalPublishedSep 12, 2026, 7:59 PMAuthorAlphaSignal NewsroomRead1 min readEdge0 streams a 35B Mixture-of-Experts model from SSD on an iPhone, holding under 3 GB of active RAM while decoding at 15 tokens per second.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsPrismML · newsPrismML Squeezes Qwen3.8 27B Into 5.9 GB With 98% Performance RetainedPrismML · modelPrism ML's Ternary Bonsai 2 Squeezes a 27B Reasoning Model Into 8.6 GBAlphaSignal · modelEmpero Distills Qwen3.8 Reasoning Into a Lean 35B Open Model