Back to News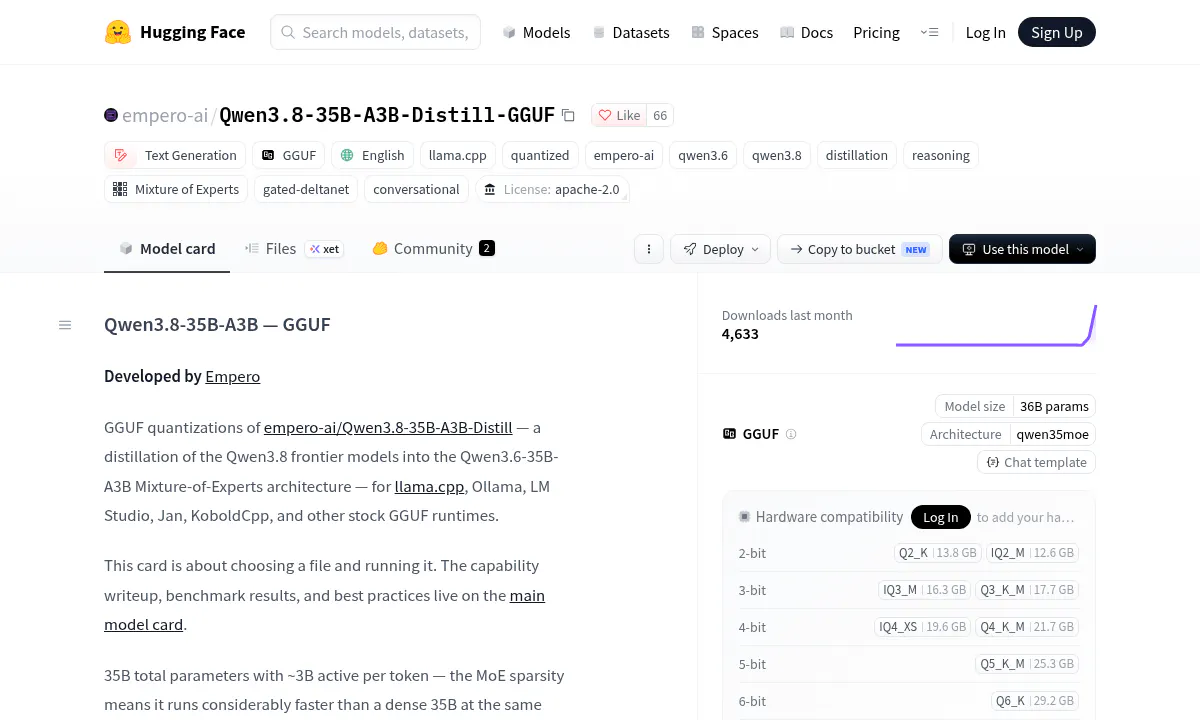
Empero Distills Qwen3.8 Reasoning Into a Lean 35B Open Model
Empero distilled Qwen3.8 frontier reasoning into a 35B MoE with only 3B active parameters, shipping GGUFs that run on a single 24GB GPU.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
Empero distilled Qwen3.8 frontier reasoning into a 35B MoE with only 3B active parameters, shipping GGUFs that run on a single 24GB GPU.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report