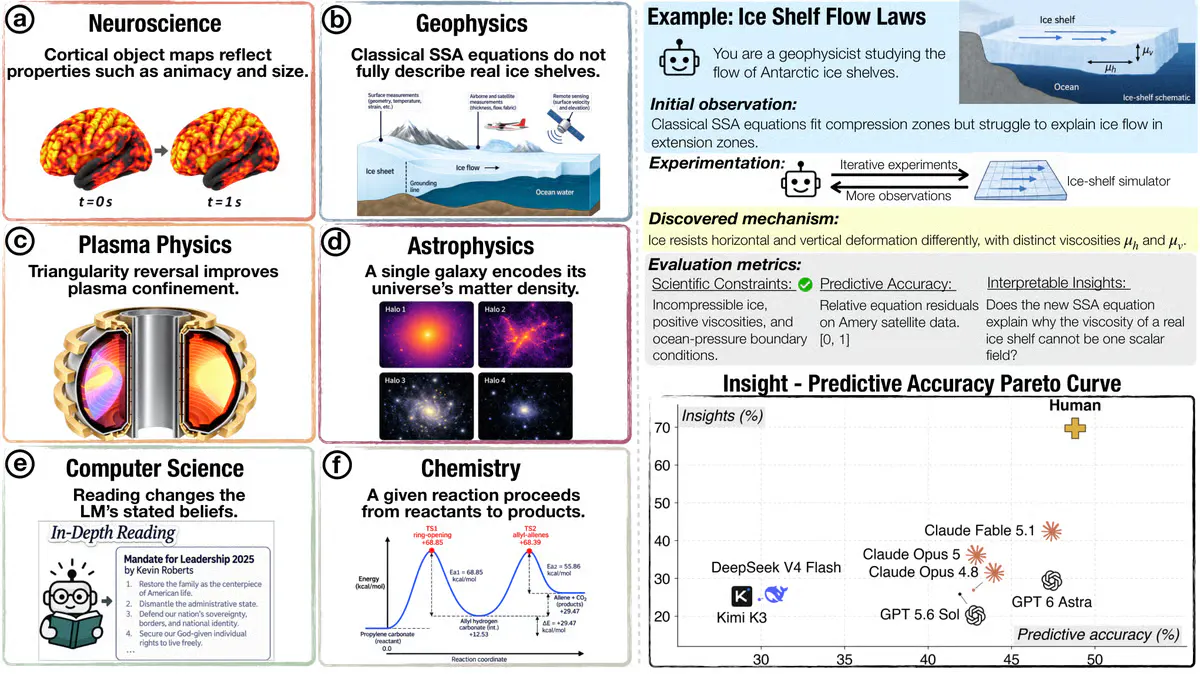
←Back to NewsAI News/AgentspaperAgentsBenchmarksEurekaBench Reveals AI Agents Still Fall 27 Points Behind Humans on Real ScienceA new benchmark shows frontier agents can match human predictive accuracy on scientific problems but still fail to produce real understanding.SourceAlphaSignalPublishedSep 30, 2026, 6:00 PMAuthorAlphaSignal NewsroomRead1 min readA new benchmark shows frontier agents can match human predictive accuracy on scientific problems but still fail to produce real understanding.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsVals AI · newsVals AI Rebuilds Vals Index 2.1 Adding Tax and Overhauled Coding ScoresAlphaSignal · paperLibraryDesignBench Catches AI Coding Agents Rebuilding Code That Already ExistsArtificial Analysis · newsStanford's Terminal-Bench-Science Exposes GPT-6 Astra Leading at 63% on Real Science Tasks