
FrostWolfAI Squeezes Spark-X2.6's 1M Context Window Into 2.6 GB
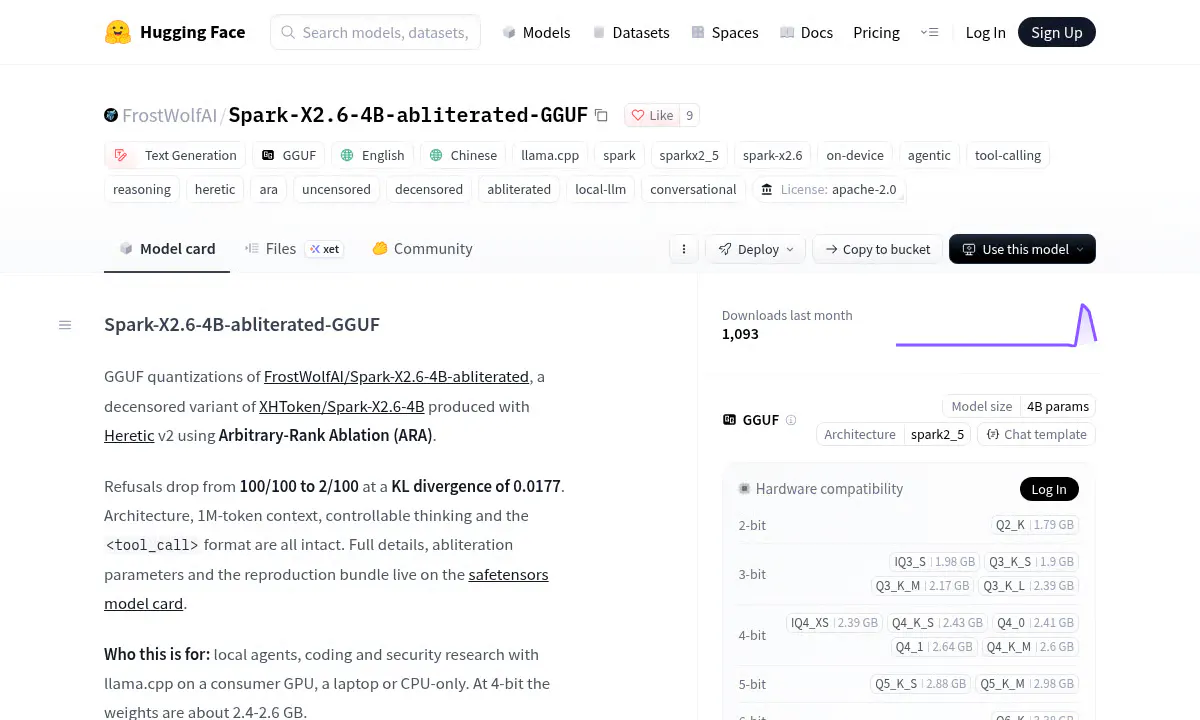
FrostWolfAI released Spark-X2.6-4B-abliterated-GGUF , a 4B uncensored local model in 14 quantization formats. Refusals drop from 100/100 to 2/100 at just 0.0177 KL divergence from the base model. Retains 1M-token context, controllable chain-of-thought reasoning, and native tool calling intact.
Takeaways
- FrostWolfAI released Spark-X2.6-4B-abliterated-GGUF , a 4B uncensored local model in 14 quantization formats.
- Refusals drop from 100/100 to 2/100 at just 0.0177 KL divergence from the base model.
- Retains 1M-token context, controllable chain-of-thought reasoning, and native tool calling intact.
- Recommended Q4_K_M quant fits in 2.60GB and hits 240 tok/s decode on a 4090.
- Built with Heretic v2 Arbitrary-Rank Ablation, Apache-2.0 licensed, runs on llama.cpp, Ollama, LM Studio.
- Requires llama.cpp with spark2_5 architecture support; author warns against public-facing unmoderated deployments.
FrostWolfAI has published a GGUF release of Spark-X2.6-4B with 14 quantized variants and a BF16 reference. The recommended Q4_K_M file occupies 2.60 GB, while the smallest Q2_K build is 1.79 GB. The conversion retains the model’s advertised 1,048,576-token context window, controllable reasoning mode, and native tool-calling format.
The files convert FrostWolfAI’s abliterated checkpoint of XHToken’s Spark-X2.6-4B. The model carries an Apache-2.0 license, and its card lists llama.cpp, Ollama, LM Studio, Jan, vLLM, and Docker Model Runner as target runtimes, subject to architecture support in each engine.
Refusal behavior reduced at the weights
Abliteration modifies refusal-related behavior without fine-tuning the model on a new dataset. The method searches internal activations for directions associated with refusal responses, then adjusts selected weight matrices to suppress those directions while limiting changes to the model’s broader output distribution.
FrostWolfAI used Heretic v2 and its Arbitrary-Rank Ablation method. Heretic examines the residual stream, the running vector of features passed between transformer layers, and orthogonalizes attention output and MLP down-projection matrices against refusal-associated directions. Its optimization balances refusal rate against KL divergence, a measure of how far the modified model’s token probabilities move from the original.
In the model card’s 100-prompt test, refusals fell from 100 to 2, with a reported KL divergence of 0.0177. The author’s checks also retained the original architecture, reasoning controls, context limit, and tool_call
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report

