Back to News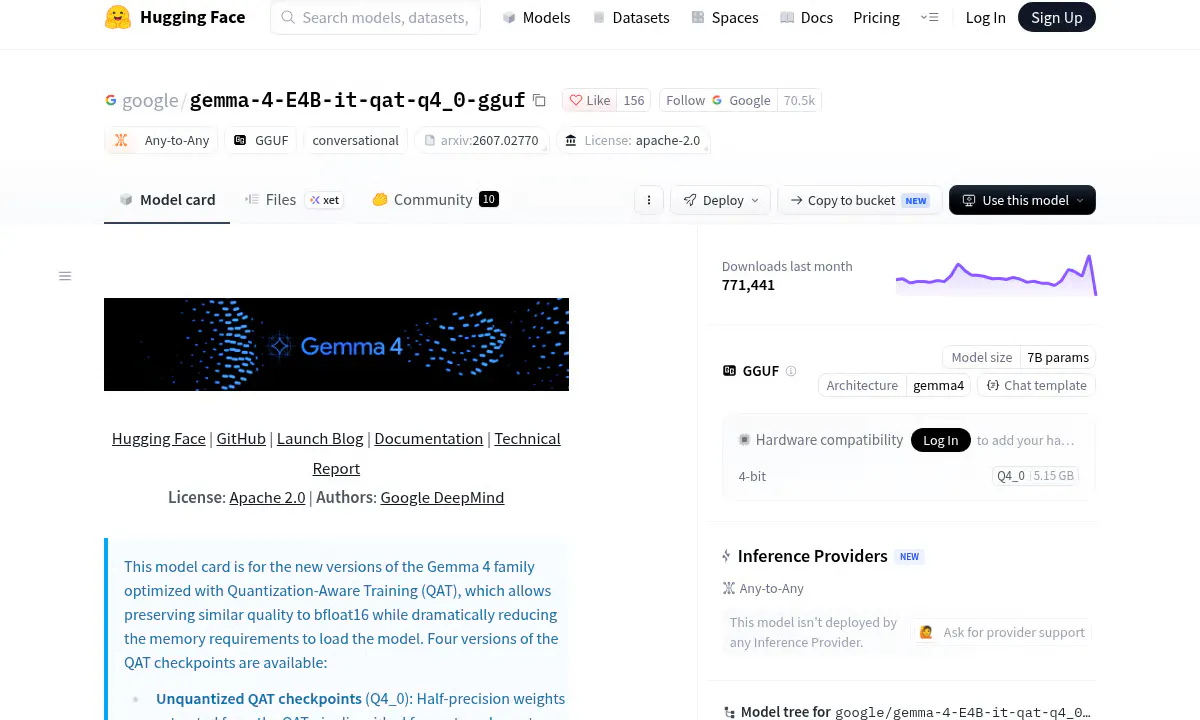
Google DeepMind Shrinks Gemma 4 E4B to 5GB Without Losing Reasoning Power
Google released quantization-aware trained Q4_0 GGUF checkpoints of Gemma 4 E4B, delivering near-bfloat16 quality in a 5.15 GB on-device package.
Source
Google
Published
Author
AlphaSignal Newsroom
Read
1 min read
Google released quantization-aware trained Q4_0 GGUF checkpoints of Gemma 4 E4B, delivering near-bfloat16 quality in a 5.15 GB on-device package.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report