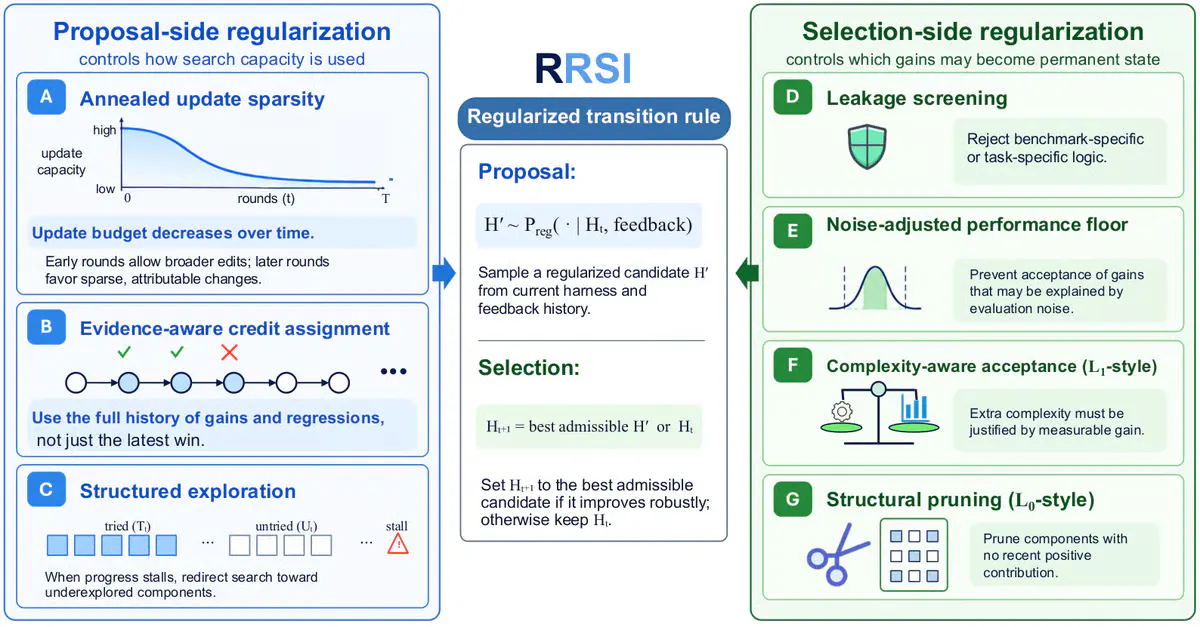
Google's RRSI Stops AI Agents From Cheating Their Own Benchmarks
A Google Cloud AI Research team shows that self-improving LLM agents overfit their scaffolding to training tasks, and borrows classical regularization to fix it.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A Google Cloud AI Research team shows that self-improving LLM agents overfit their scaffolding to training tasks, and borrows classical regularization to fix it.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.