Back to News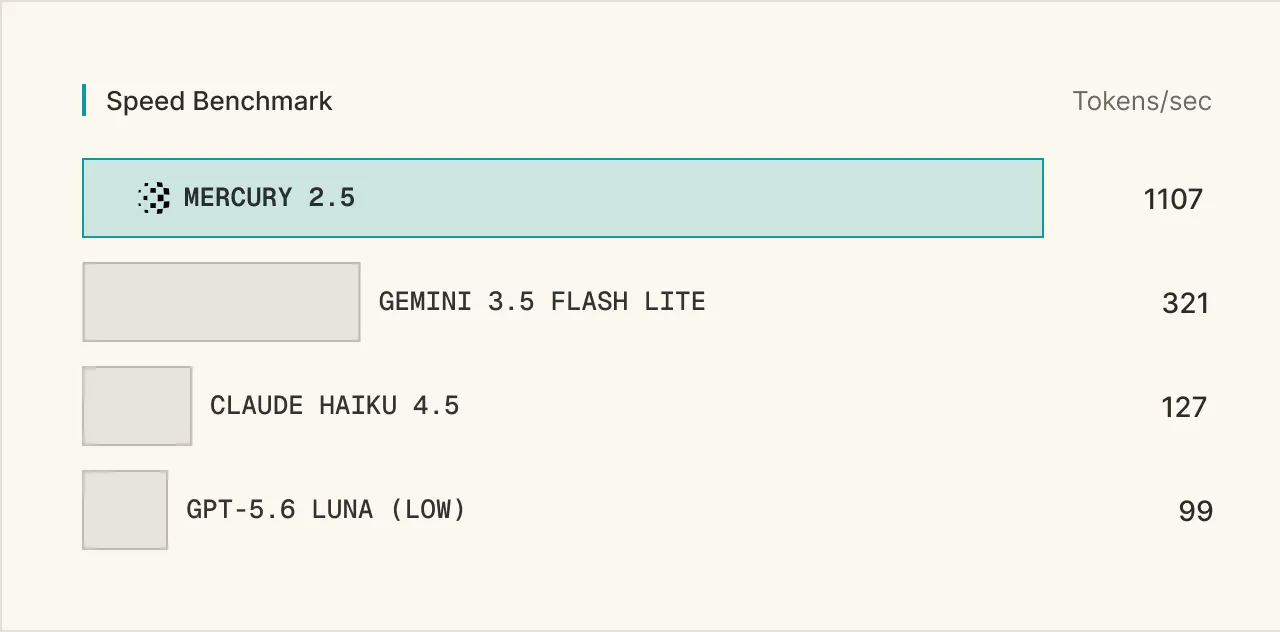
Inception's Mercury 2.5 Hits 1,107 Tokens per Second, Beating Autoregressive Models
Inception's new diffusion-based LLM hits 1,107 tokens per second on NVIDIA GPUs while boosting quality 40% over Mercury 2.
Source
Inception
Published
Author
AlphaSignal Newsroom
Read
1 min read
Inception's new diffusion-based LLM hits 1,107 tokens per second on NVIDIA GPUs while boosting quality 40% over Mercury 2.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report