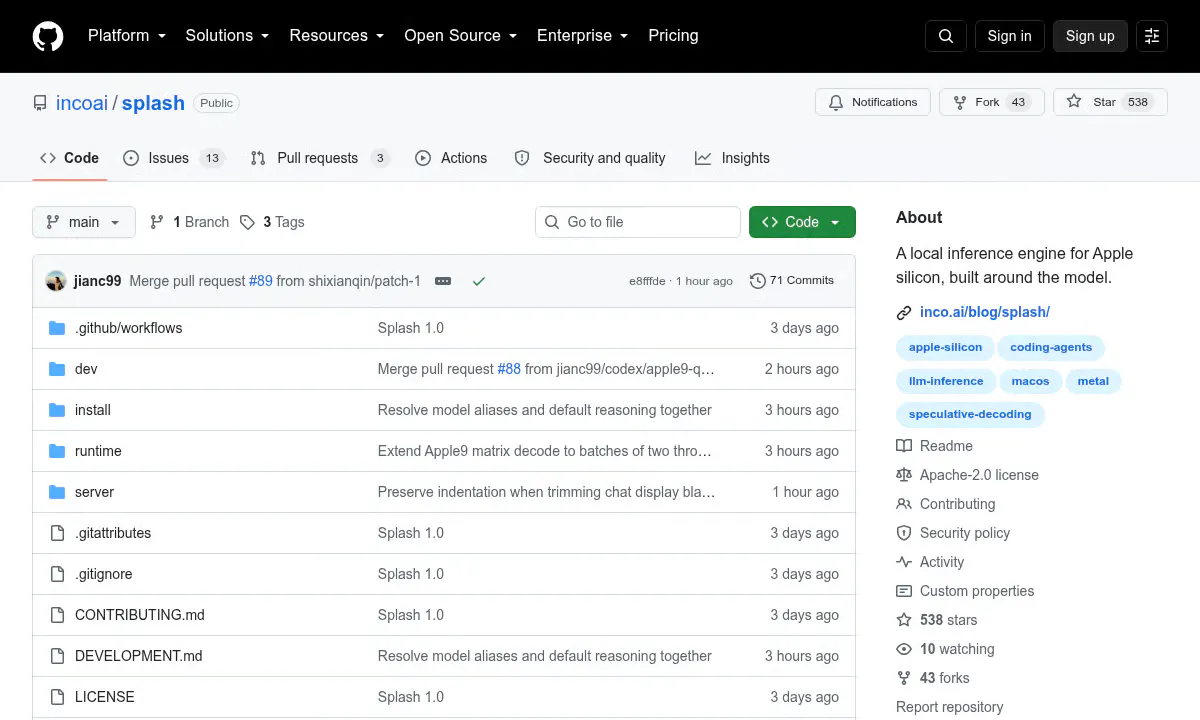
←Back to NewsAI News/InfrarepoInfraGpusInco AI's Splash Runs Qwen3.8-27B Twice as Fast on Apple SiliconInco's open-source Splash engine runs Qwen3.8-27B at 74 tok/s on an M5 Pro, hitting 2x oMLX and 3x Ollama on Apple silicon.SourceAlphaSignalPublishedSep 21, 2026, 6:35 PMAuthorAlphaSignal NewsroomRead1 min readInco's open-source Splash engine runs Qwen3.8-27B at 74 tok/s on an M5 Pro, hitting 2x oMLX and 3x Ollama on Apple silicon.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsTogether AI · newsTogether AI's ThunderKittens Hits 22.4 PFLOPS on NVIDIA's RubinIntelligent Internet · newsIntelligent Internet's Meta-Zenith Agent Rewrote vLLM Kernels for a 4x SpeedupPyTorch · newsNVIDIA's CUDA Python 1.0 Makes Python a First-Class GPU Citizen