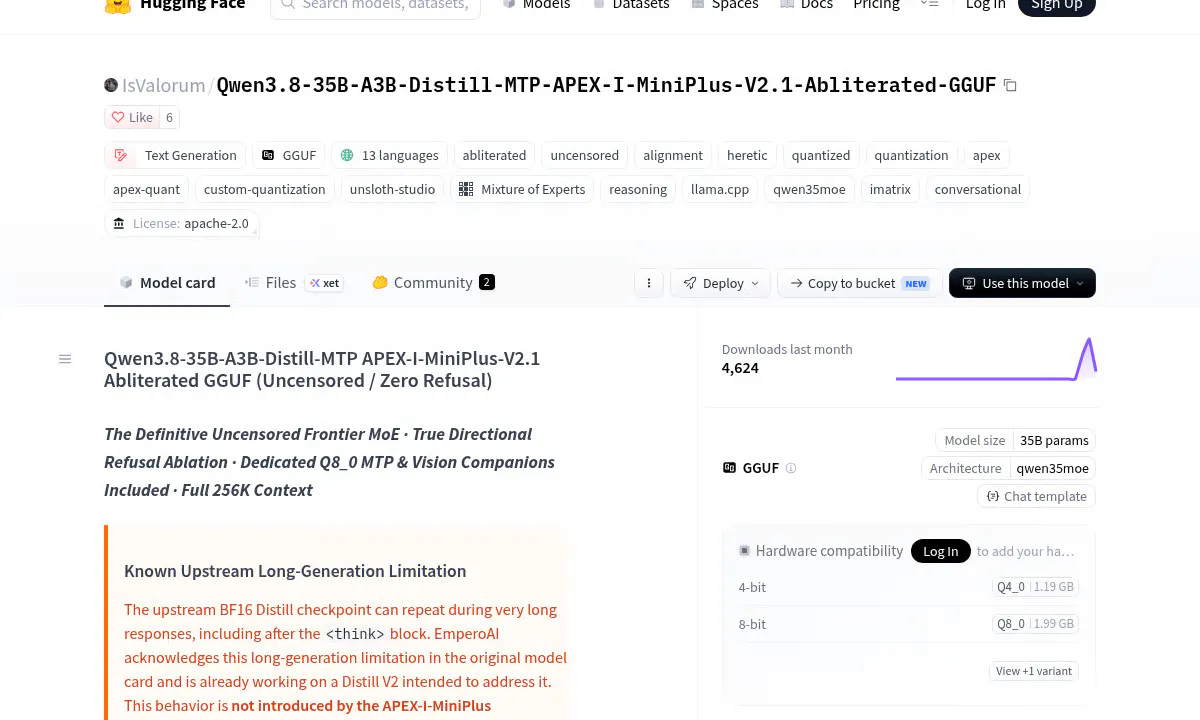
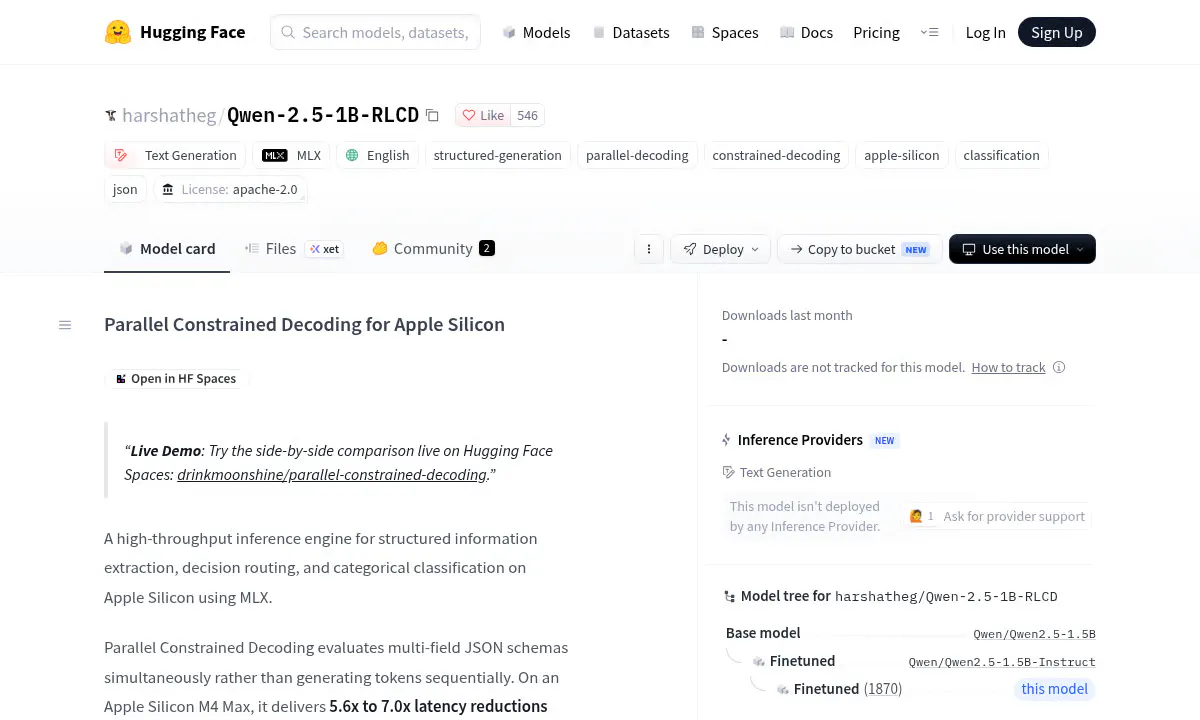
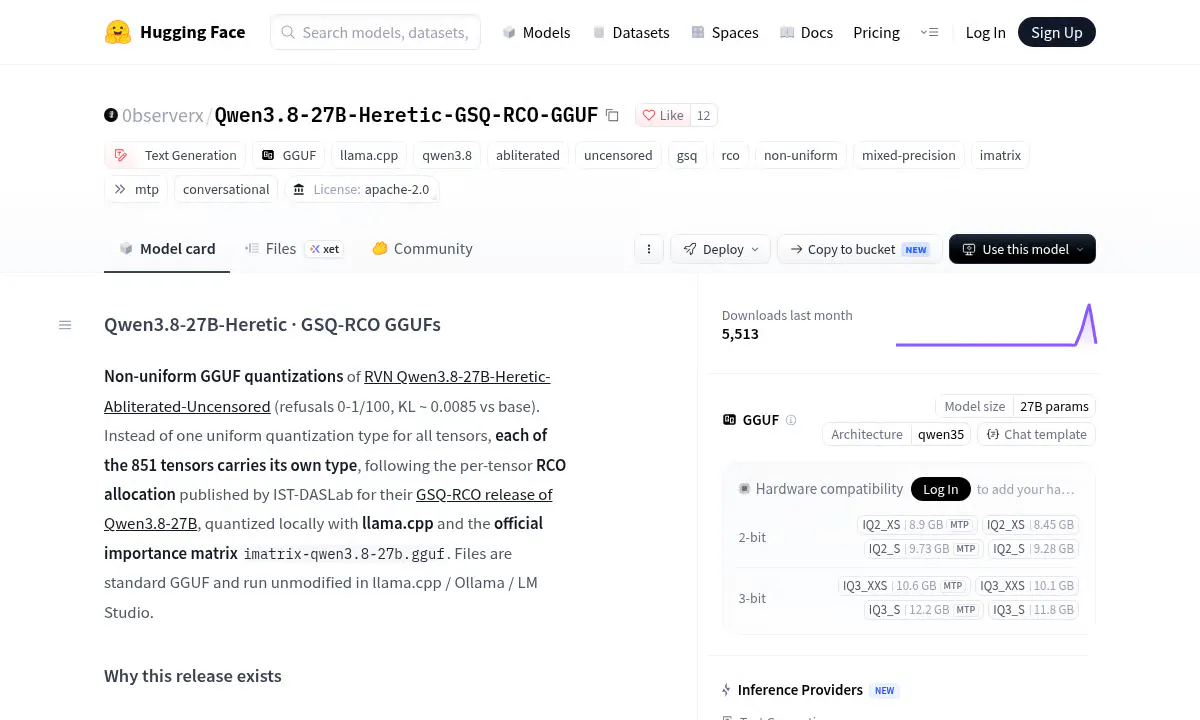
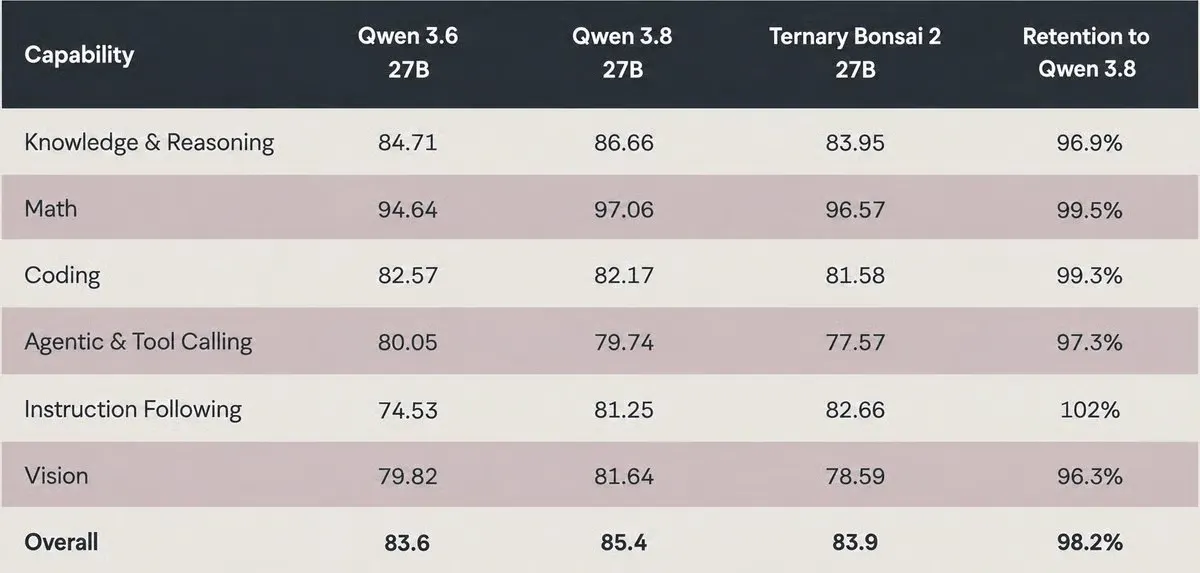
←Back to NewsAI News/LlmsmodelLlmsGpusIsValorum Squeezes a 35B Open-Source Qwen3.8 Model Into 14.65 GBA 35B Qwen mixture-of-experts release strips refusal vectors and squeezes the whole model plus 256K context into 24GB of VRAM.SourceAlphaSignalPublishedSep 20, 2026, 11:59 PMAuthorAlphaSignal NewsroomRead1 min readA 35B Qwen mixture-of-experts release strips refusal vectors and squeezes the whole model plus 256K context into 24GB of VRAM.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsAlphaSignal · modelQwen-2.5-1B-RLCD Scores JSON Fields in Parallel, Running 7x Faster on Apple SiliconAlphaSignal · modelQwen3.8 Squeezed to 11.8 GB Runs at 150 Tokens per SecondPrismML · newsPrismML Squeezes Qwen3.8 27B Into 5.9 GB With 98% Performance Retained