Back to News
Kindling AI Shrinks GLM-5.3's 744B Expert Weights to Fit Memory-Constrained Clusters
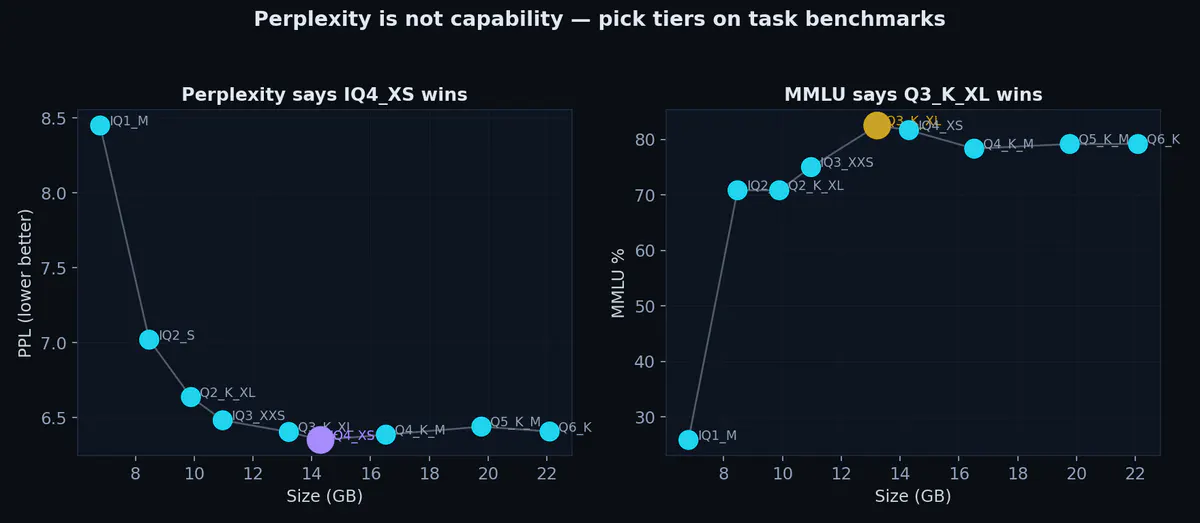
Kindling AI uploaded a preview EXLR8 v2 quantization of Z.ai's 744B GLM-5.3 MoE, tuned for NVIDIA GB10 unified-memory boxes.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
Kindling AI uploaded a preview EXLR8 v2 quantization of Z.ai's 744B GLM-5.3 MoE, tuned for NVIDIA GB10 unified-memory boxes.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report