
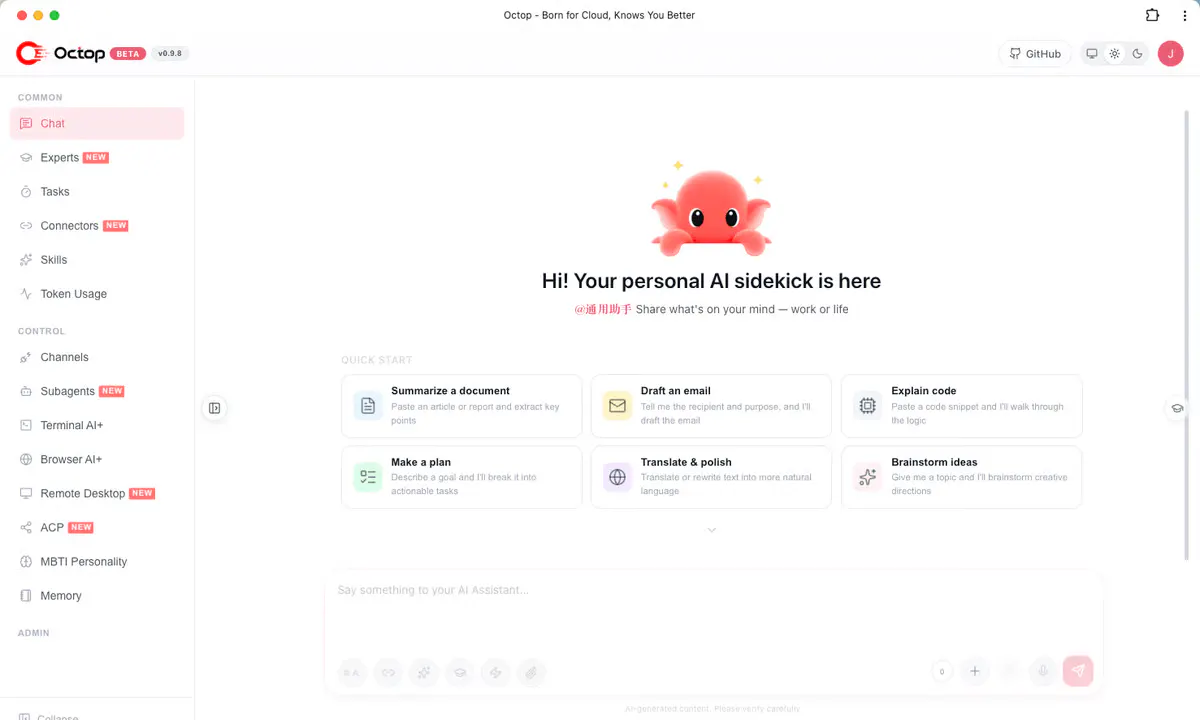
Tencent Releases Octop, a Self-Hosted Multi-User AI Platform in One Process
Tencent Cloud open-sourced Octop, a single-process, self-hosted AI assistant that gives every user their own team of MBTI-flavored agents across web, CLI, and chat apps.
hermes-ai.net
Read docs →A focused feed of models, agents, research and open-source releases for people building with AI.
Tencent Cloud open-sourced Octop, a single-process, self-hosted AI assistant that gives every user their own team of MBTI-flavored agents across web, CLI, and chat apps.
Bolt adds DeepSeek V4.1 Flash to its Forge open-model lineup, promising 10x the usage of V4 Pro and stronger visual design output.
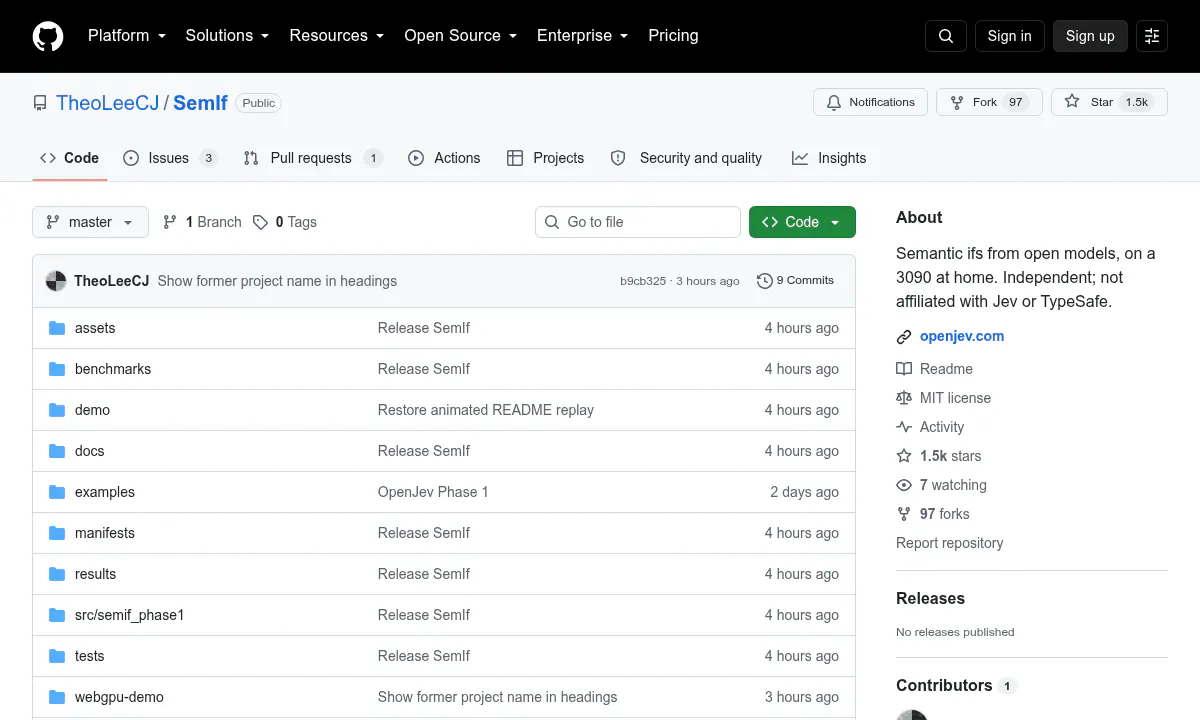
OpenJev reproduces TypeSafe's semantic if-statement service using open 4B models on a single RTX 3090, reading option logits directly instead of parsing generated JSON.
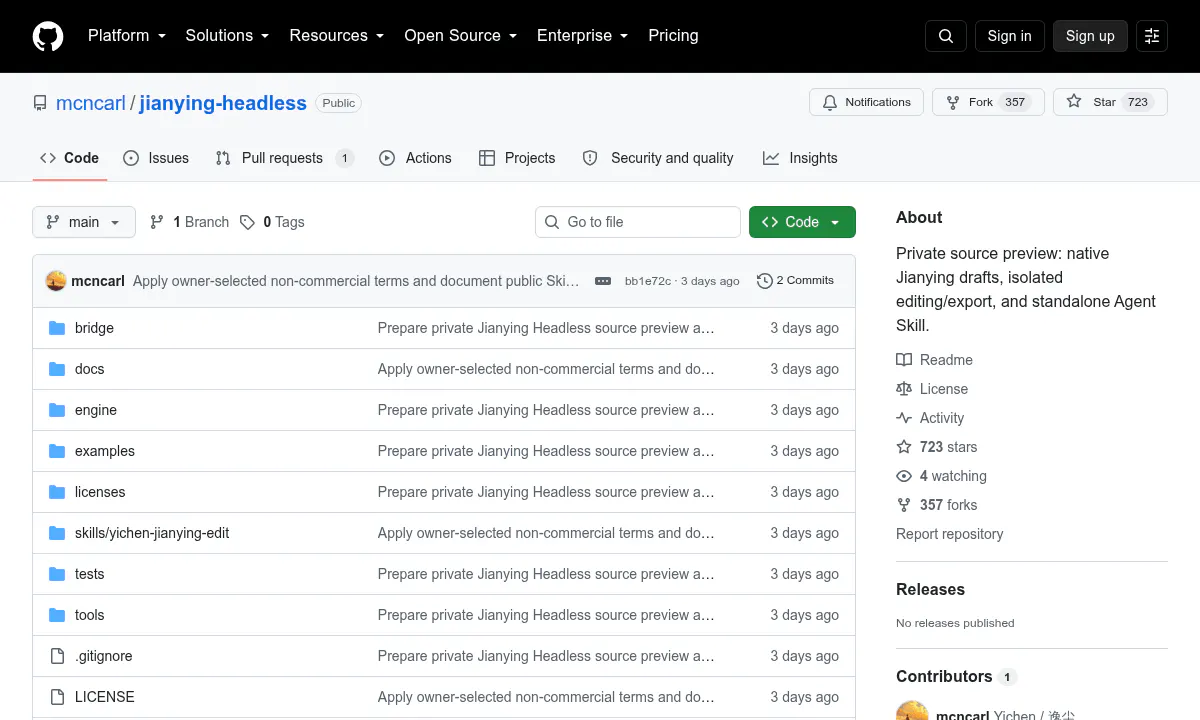
A reverse-engineered toolkit lets AI agents drive CapCut's Chinese sibling Jianying entirely from the command line, producing native editable drafts and MP4 exports.
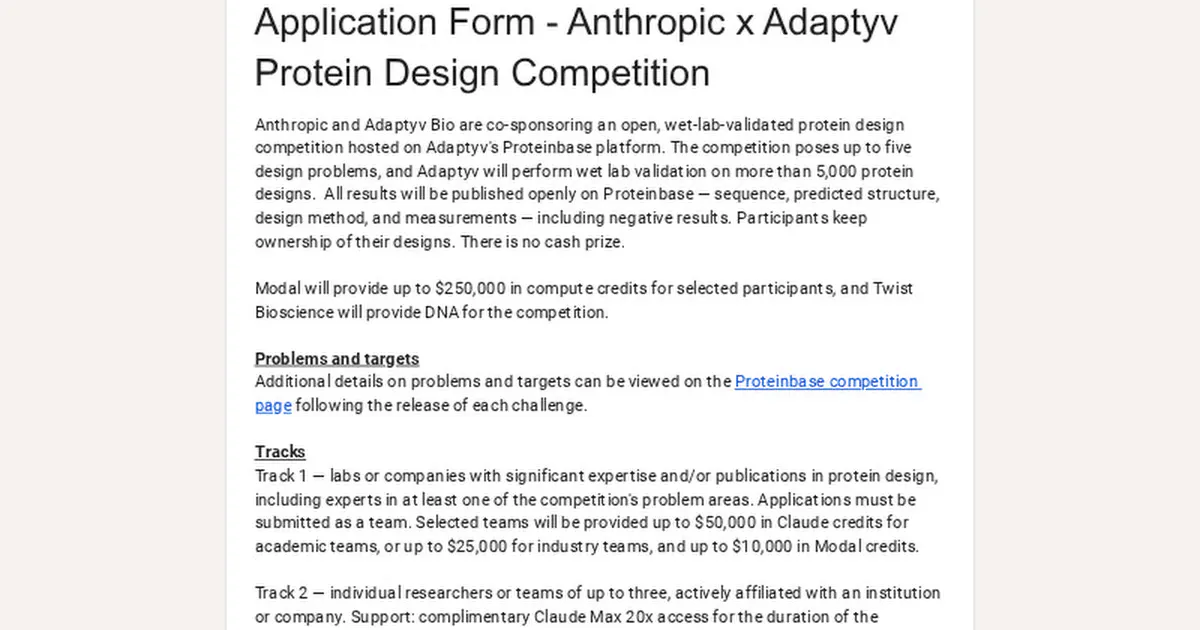
Claude accelerated over 30 open-source biology models by roughly 4x, letting a single GPU node predict structures once out of reach.

Jina AI released jina-ocr-v1, a 3.4B mixture-of-experts document parser with speculative decoding that turns pages into Markdown at 2.57 pages per second.
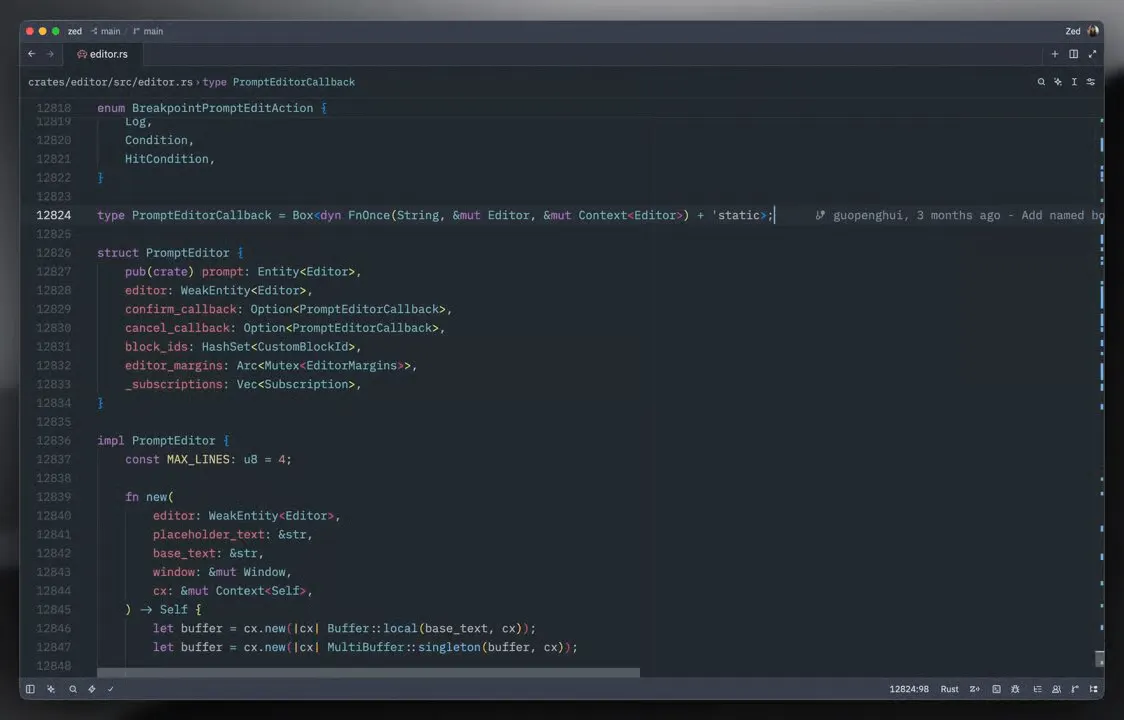
Zed's weekly release adds animated cursors, Emmet wrap-with-abbreviation, configurable window titles, and Markdown files that open straight into rendered preview.
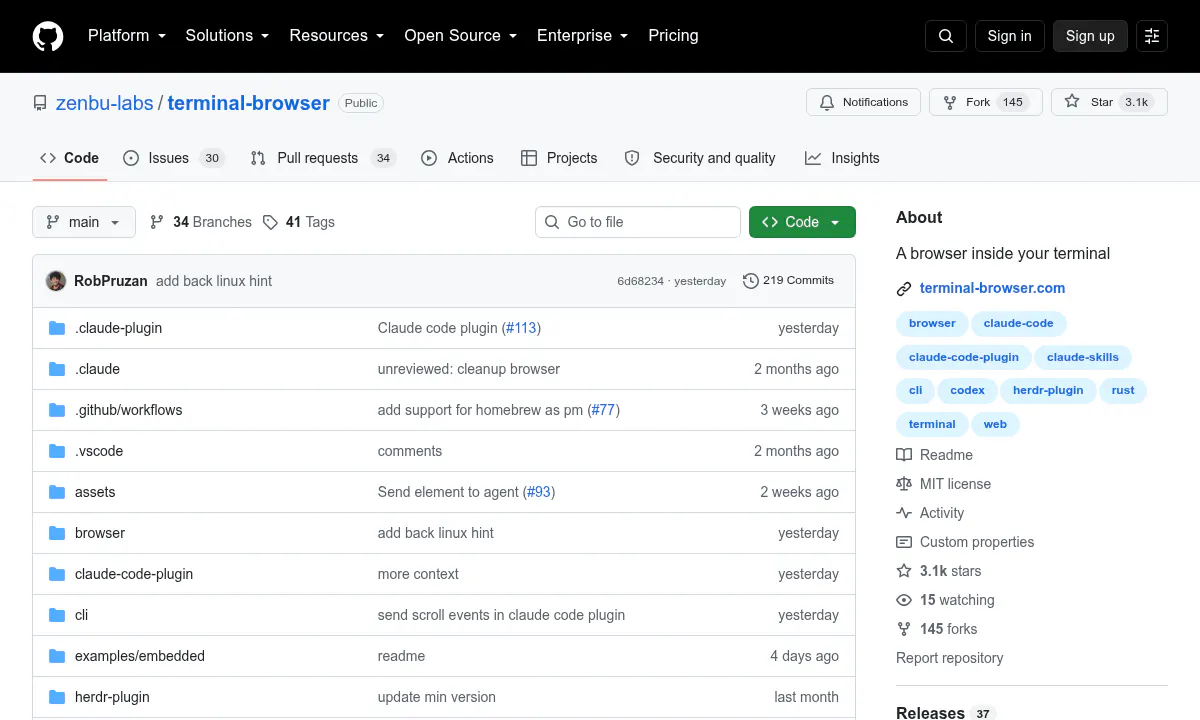
Zenbu Labs shipped a Chromium-powered browser that renders inside your terminal, giving coding agents a real web surface they can drive alongside your code.
Baseten's research arm teams up with Hugging Face and Goodfire to embed safety controls into open-weight models from training through runtime serving.
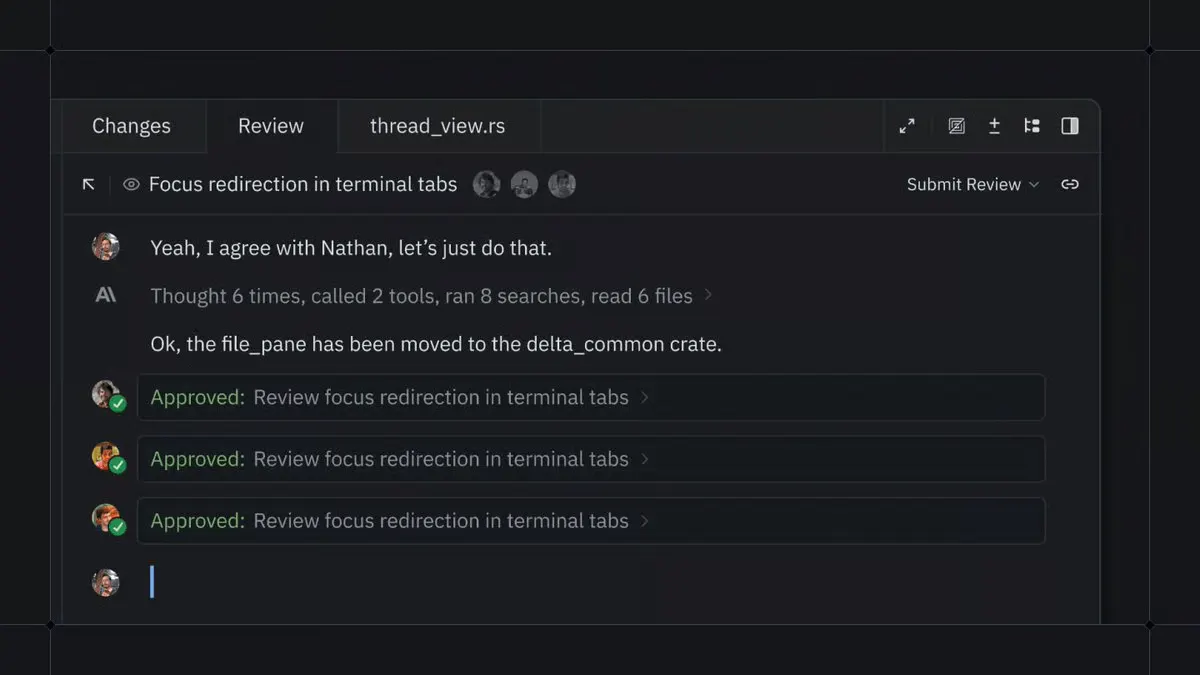
Zed's new Delta environment replaces GitHub pull requests with agent-aware threads, backed by a version control system that records every edit.
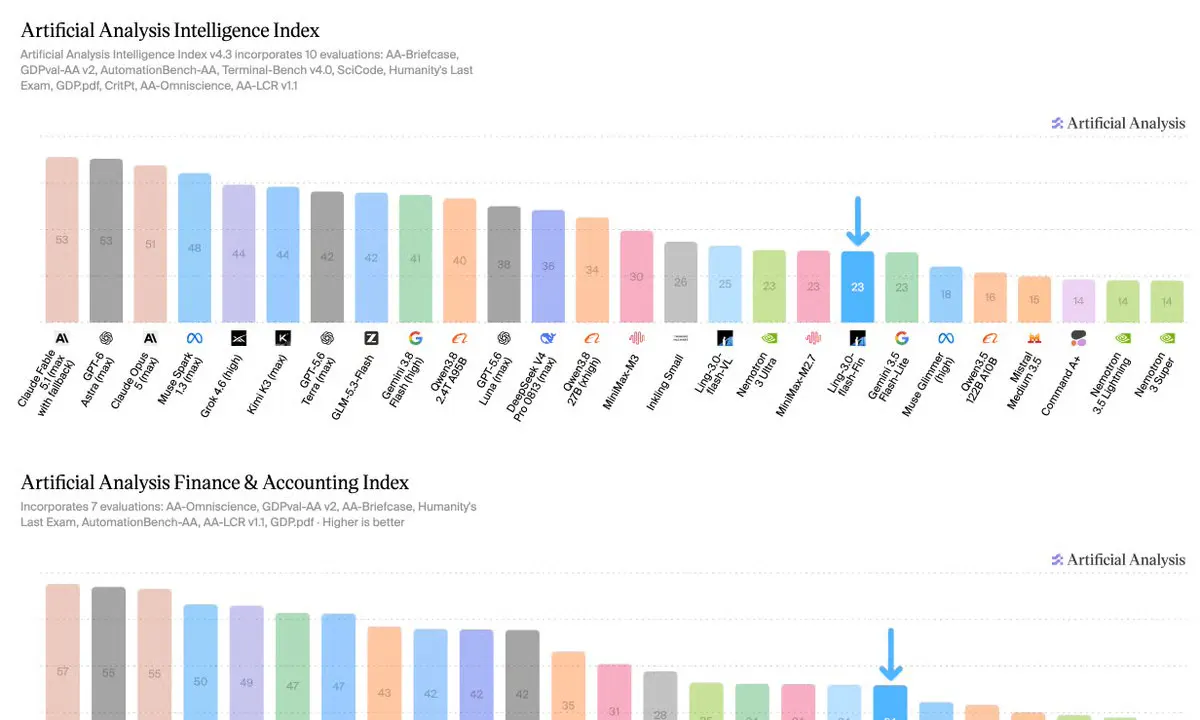
Ant Group's Ling-3.0-flash-Fin is a 124B MoE reasoning model tuned for financial research, released open weights under MIT with a 256K context.
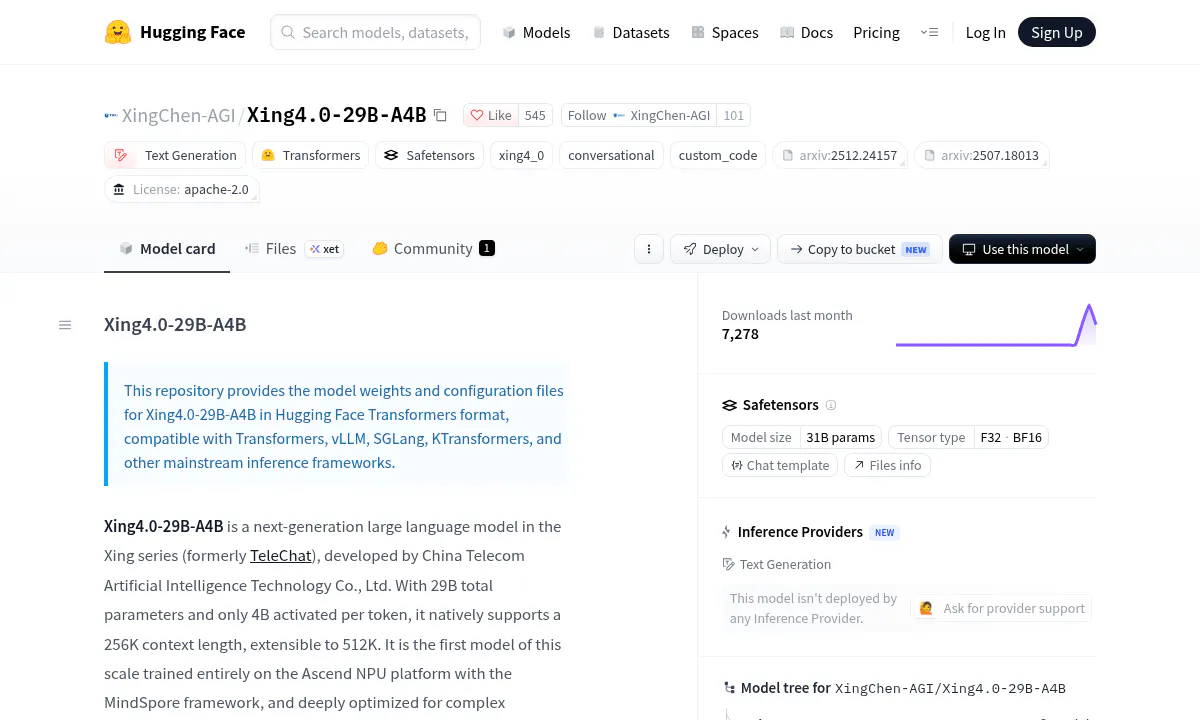
China Telecom released Xing4.0-29B-A4B , a 29B MoE with 4B active parameters, Apache 2.0. Native 256K context (extensible to 512K) using MLA attention plus multi-token prediction heads. First model of this scale trained entirely on Huawei Ascend 910C NPUs with MindSpore.
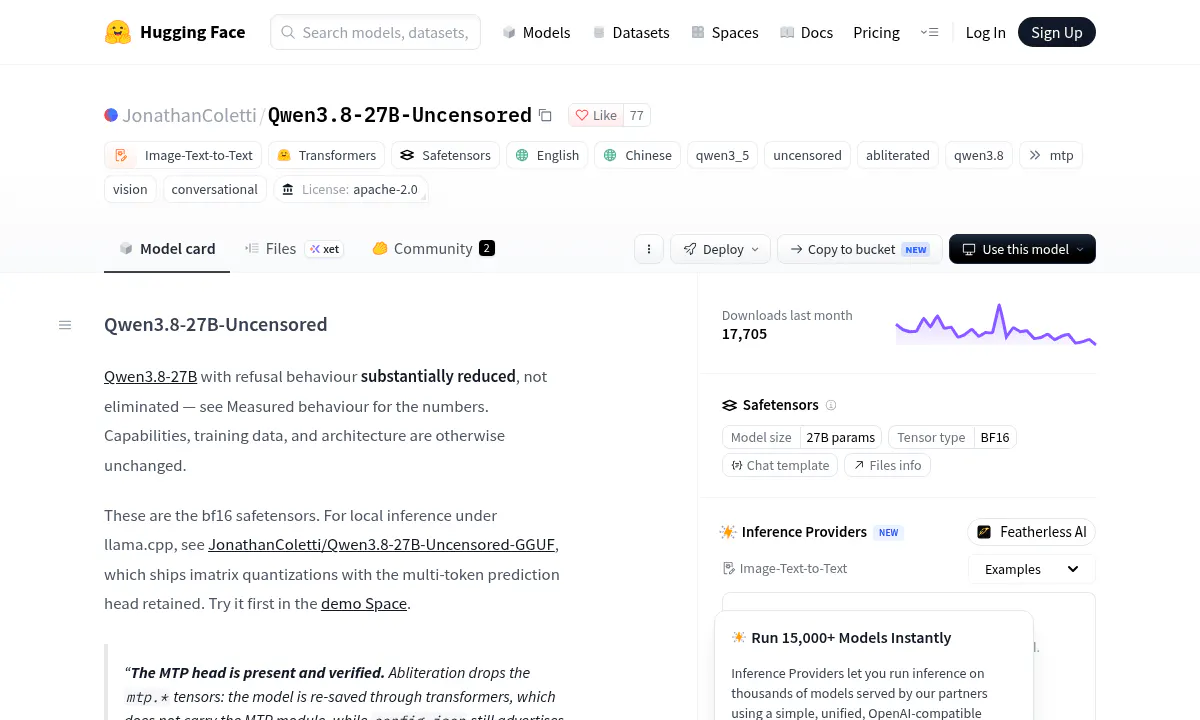
A community developer stripped refusal behavior from Qwen3.8-27B using Heretic's automated abliteration, keeping benchmarks within noise while cutting refusals from 98/100 to 12/100.
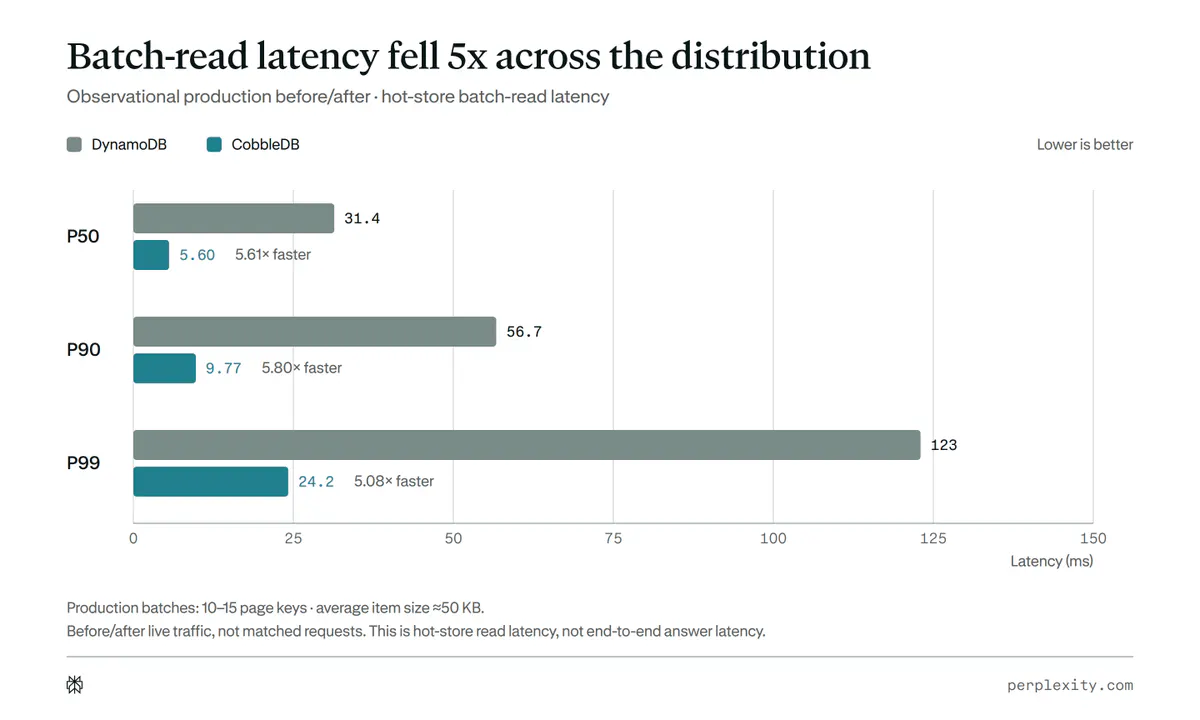
Perplexity rebuilt its search hot store from scratch, cutting batch-read latency 5x and slashing costs 20% versus DynamoDB.
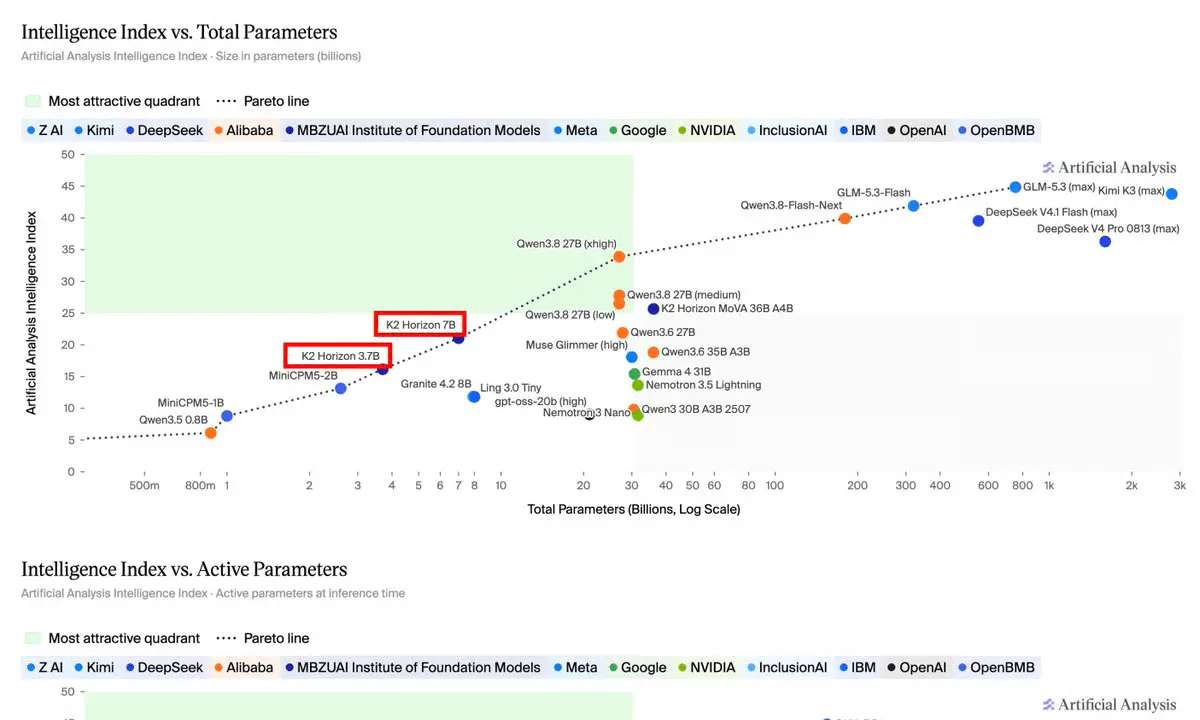
IFM released three open-weight K2-Horizon models spanning 3.7B to 36B parameters, plus a diffusion adapter that delivers up to 2.2x speedup.
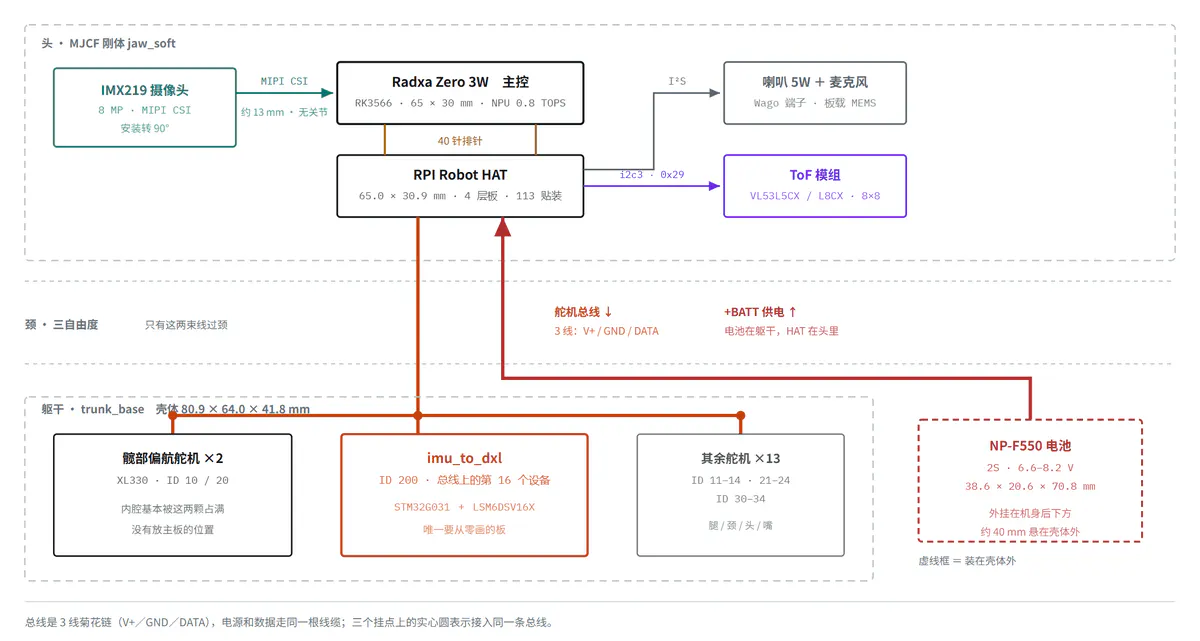
A solo developer reverse-engineered Pollen Robotics' closed hardware from its open MJCF sim files, publishing full assembly drawings, CAD, and electronics.
Kevin Zakka's new library steps thousands of MuJoCo simulations in parallel on a single CPU, unlocking RL and MPC workloads without a GPU.
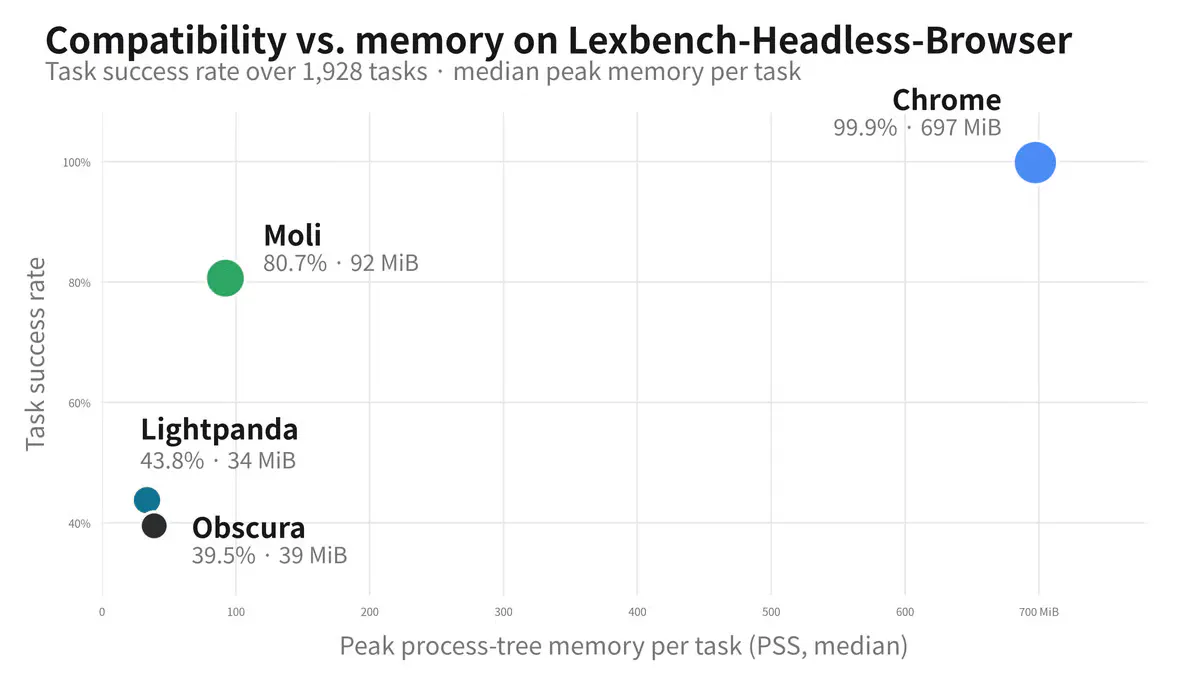
Moli is a headless browser built in Rust from scratch that skips rendering by default, cutting memory use to roughly one-tenth of Chrome for agent workloads.
Marigold V2 turns Qwen-Image-Edit into a single-step depth, normals, and albedo predictor, fine-tuned on one 32 GB consumer GPU.
LiteReality-Agent turns iPhone LiDAR scans of real rooms into editable, physics-ready 3D scenes represented as Python code that an agent iteratively refines.
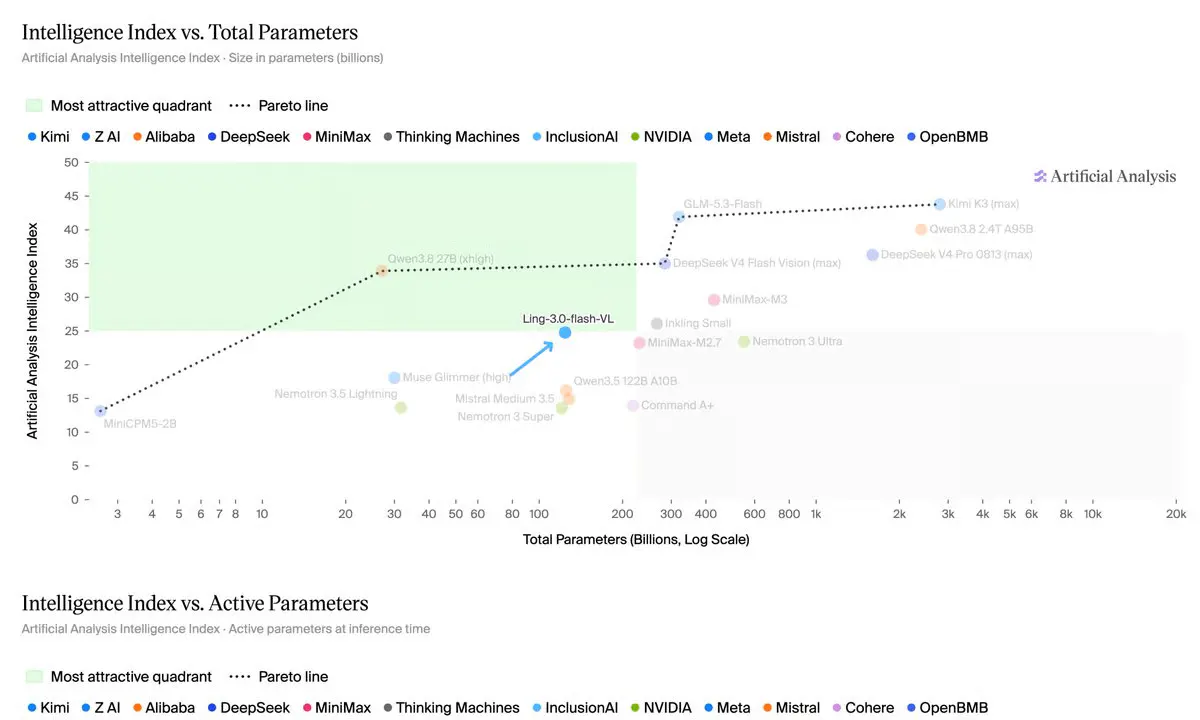
Ant Group's InclusionAI lab dropped an MIT-licensed 124B mixture-of-experts vision model that activates just 5.5B parameters per token and ingests text, images, and video.
NVIDIA Labs released SoL-Pi, a coding agent extension that cuts token cost by roughly one-third using four mechanisms discovered by auto-research loops.

Sakana AI's Fugu Max and Fugu Ultra v2 orchestrate pools of open models to beat frontier LLMs on cost and capability simultaneously.
Edge0 is an open source framework that streams MoE experts from SSD, letting a 35B parameter model run on a 24GB Mac mini with under 3GB active memory.
No stories match these filters.