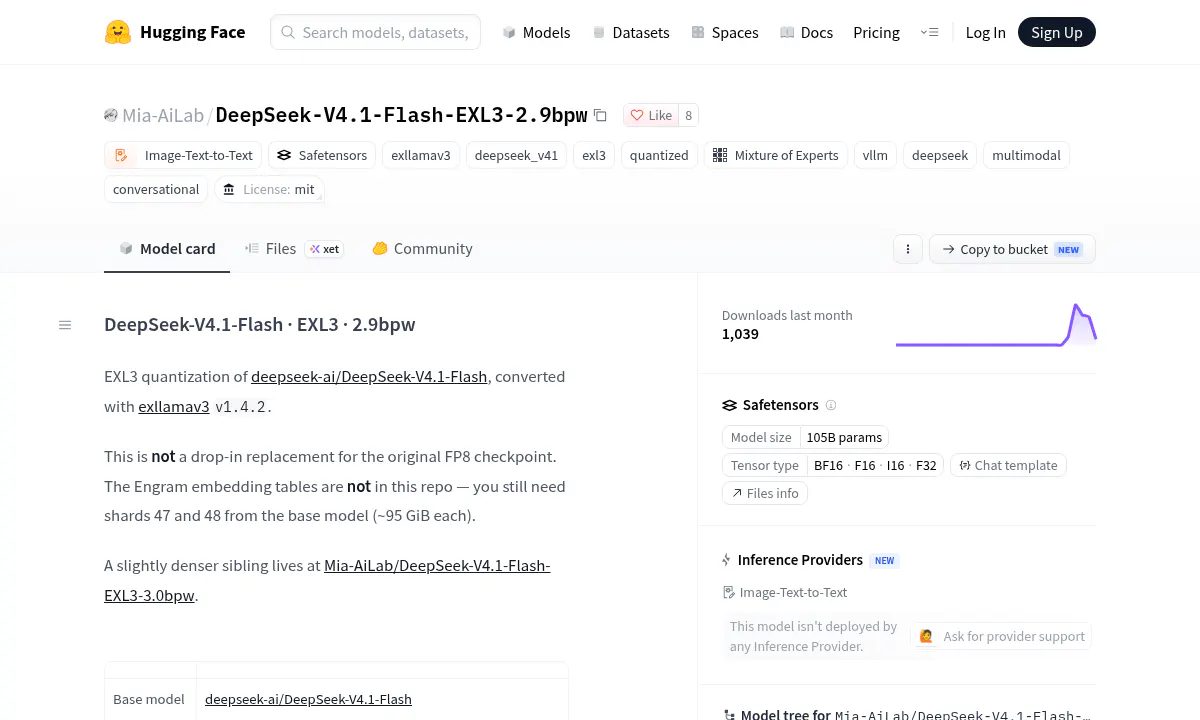
Mia's AI Lab Squeezes DeepSeek V4.1 Flash's 552B Model onto Two Desktop Nodes
A community quantization squeezes DeepSeek's 552B multimodal MoE onto two desktop DGX Sparks, holding decode speeds across half a million tokens of context.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A community quantization squeezes DeepSeek's 552B multimodal MoE onto two desktop DGX Sparks, holding decode speeds across half a million tokens of context.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.