Back to News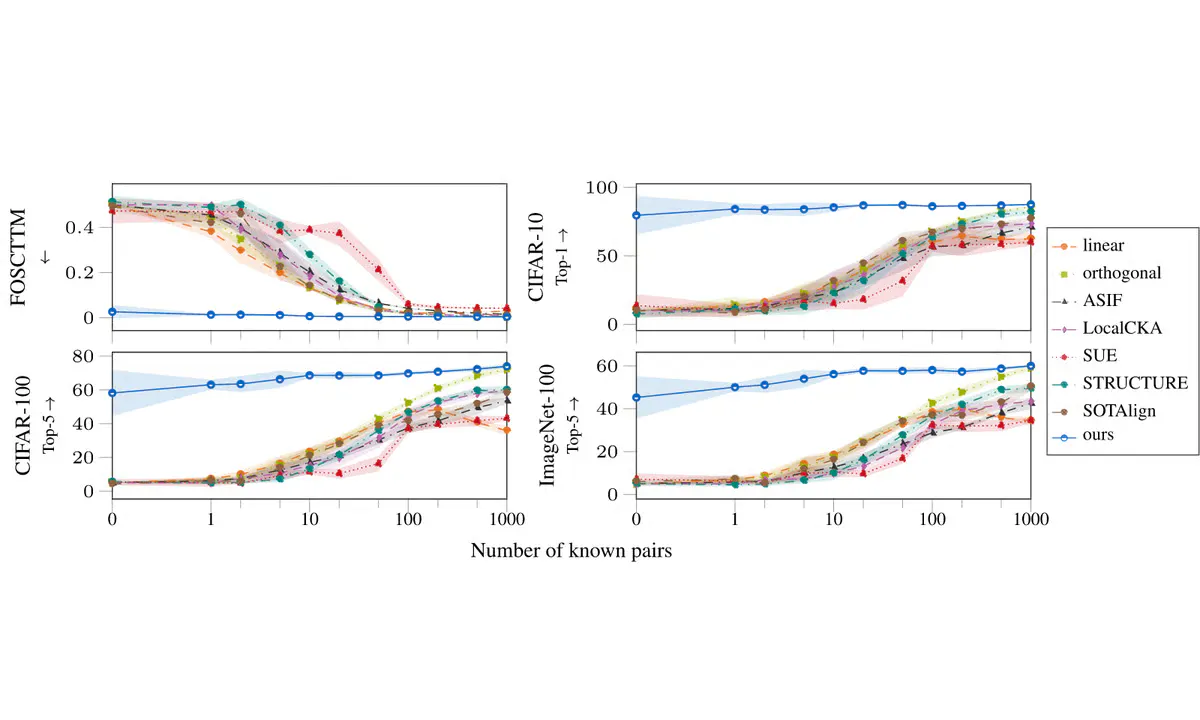
MIT and ETH Zurich Bridge Vision and Language AI Without Paired Training Data
A new method aligns vision and language embedding spaces using geometry alone, with zero image-caption pairs, hitting near-perfect retrieval on COCO.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new method aligns vision and language embedding spaces using geometry alone, with zero image-caption pairs, hitting near-perfect retrieval on COCO.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report