Back to News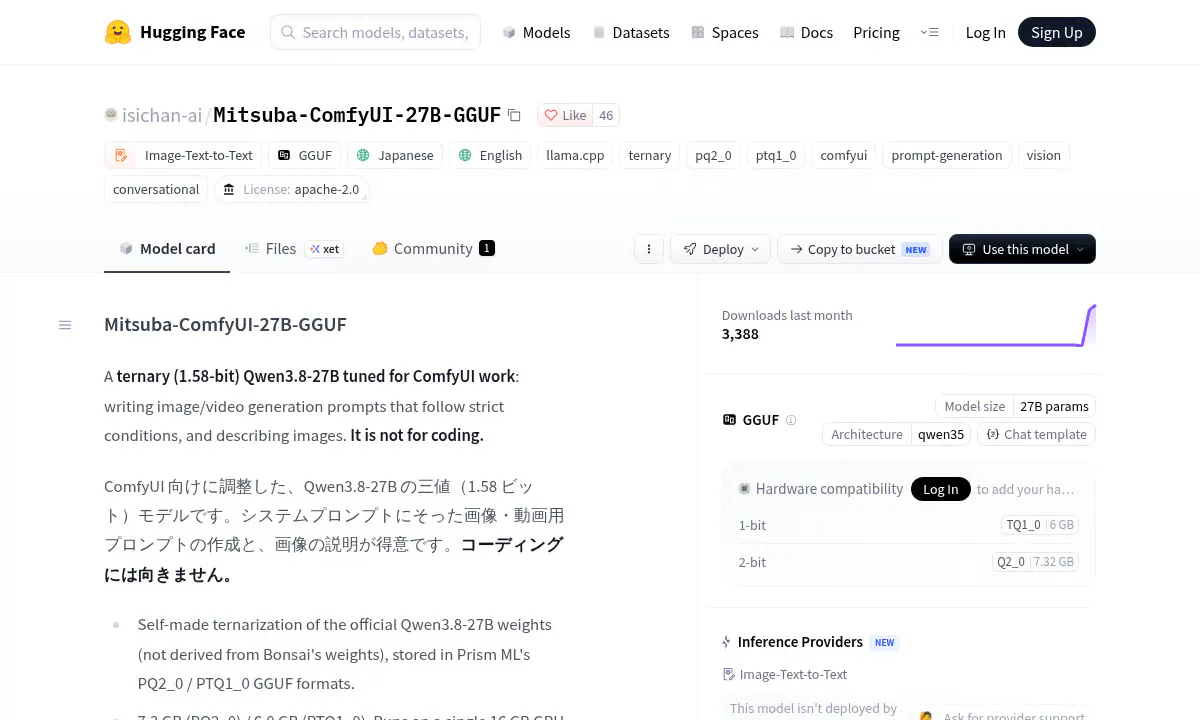
Mitsuba Squeezes a 27B Vision Model Into 7.3 GB for ComfyUI
A 7.3GB ternary-quantized Qwen3.8-27B vision model tuned specifically for writing ComfyUI image and video generation prompts from reference images.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A 7.3GB ternary-quantized Qwen3.8-27B vision model tuned specifically for writing ComfyUI image and video generation prompts from reference images.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report