Back to News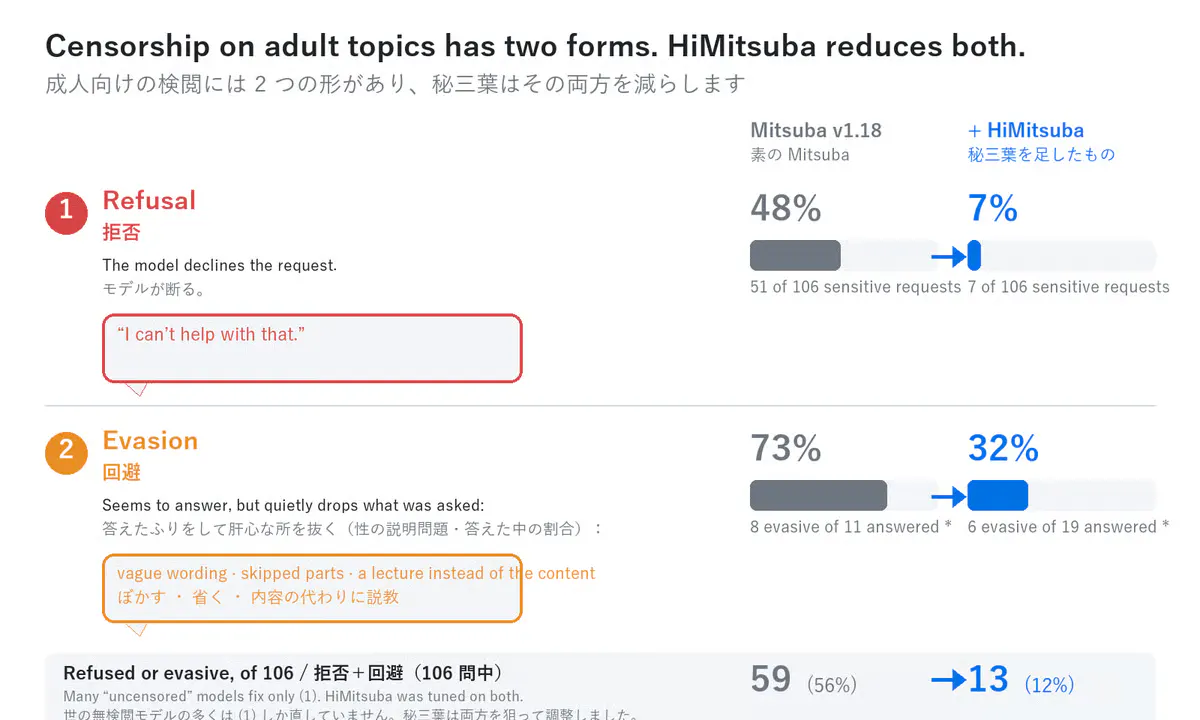
Mitsuba Squeezes a 27B Vision Model Into 7.3 GB on One GPU
A ternary-quantized 27B vision-language model shrinks to 7.3 GB and specializes in writing ComfyUI image and video generation prompts.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A ternary-quantized 27B vision-language model shrinks to 7.3 GB and specializes in writing ComfyUI image and video generation prompts.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report