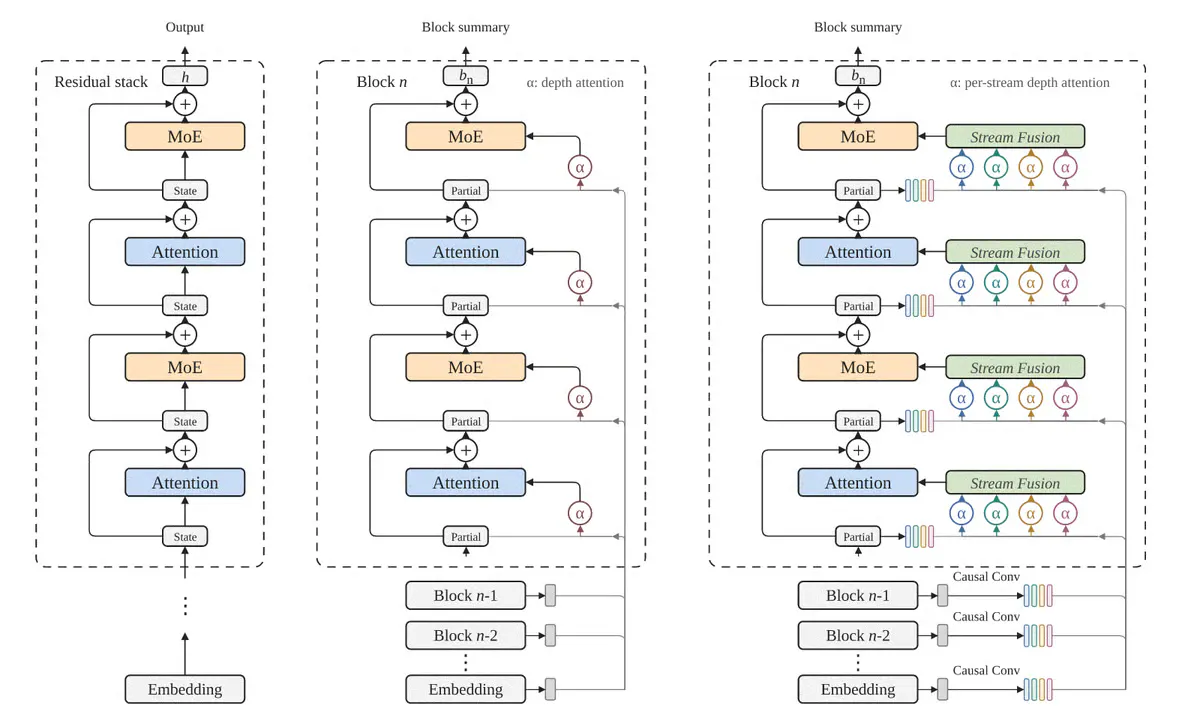
MSAR Cuts Transformer Training Compute by 37% With Smarter Residual Connections
A new residual connection design borrows the multi-head trick from attention and applies it along network depth, delivering 1.58x compute speedup over standard residuals at MoE scale.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new residual connection design borrows the multi-head trick from attention and applies it along network depth, delivering 1.58x compute speedup over standard residuals at MoE scale.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.