hermes-ai.netis an unofficial, independent community guide to Hermes Agent, with localized docs, release notes, desktop notes, and practical setup paths.
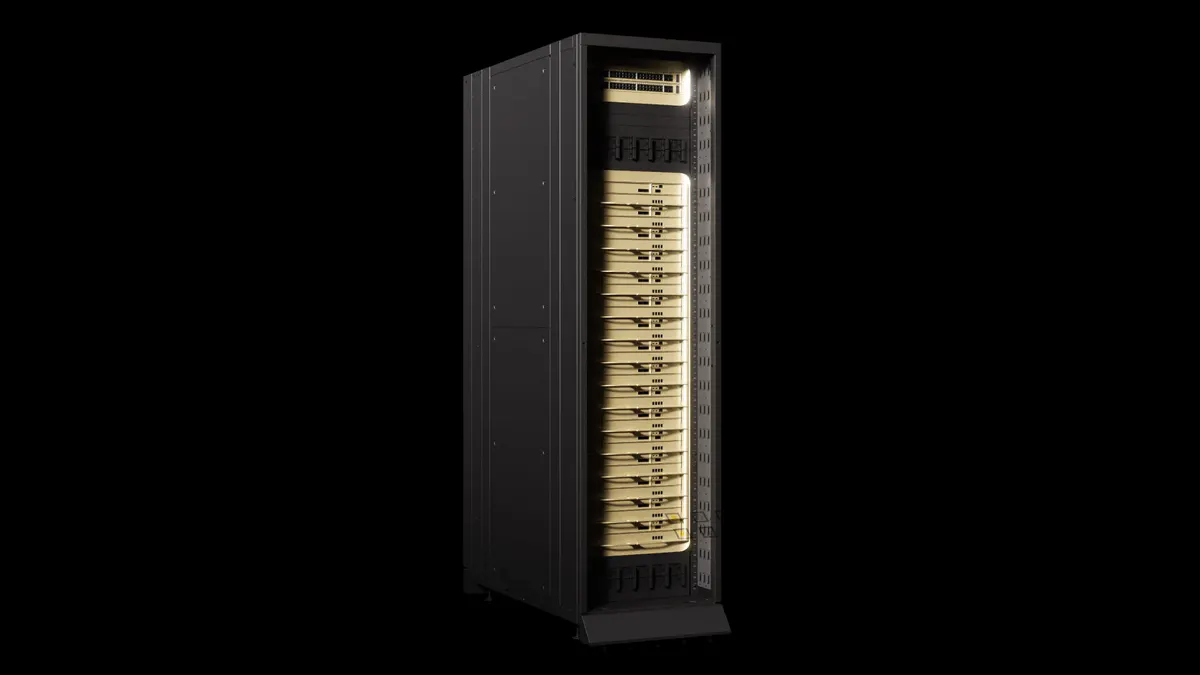
NVIDIA's new inference accelerator hit 3,431 tokens/second on Gemma 4 31B at 100K context, roughly 4x the fastest public endpoint in third-party testing.
Source
Artificial Analysis
Published
Author
AlphaSignal Newsroom
Read
1 min read
NVIDIA's new inference accelerator hit 3,431 tokens/second on Gemma 4 31B at 100K context, roughly 4x the fastest public endpoint in third-party testing.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.