Back to News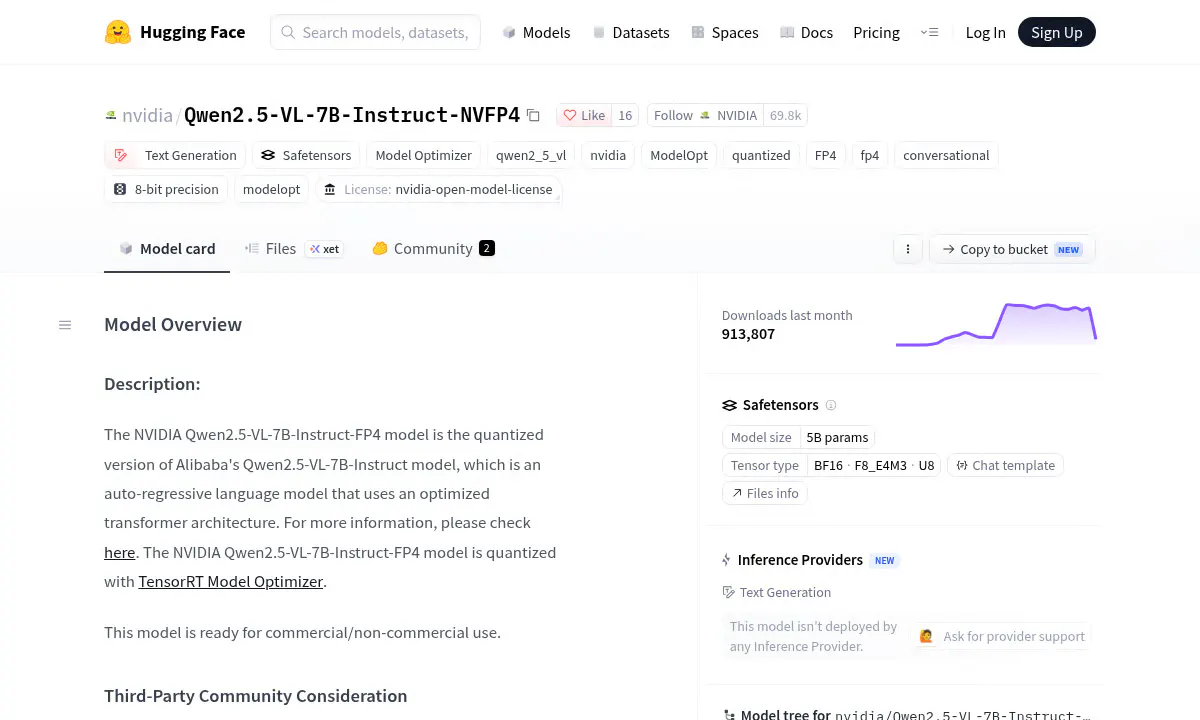
NVIDIA Ships Qwen2.5-VL Optimized for 3.6x Smaller Blackwell GPU Inference
NVIDIA published a 4-bit NVFP4 build of Qwen2.5-VL-7B-Instruct that runs on Blackwell Tensor Cores through TensorRT-LLM, cutting memory roughly 3.5x.
Source
NVIDIA AI
Published
Author
AlphaSignal Newsroom
Read
1 min read
NVIDIA published a 4-bit NVFP4 build of Qwen2.5-VL-7B-Instruct that runs on Blackwell Tensor Cores through TensorRT-LLM, cutting memory roughly 3.5x.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report