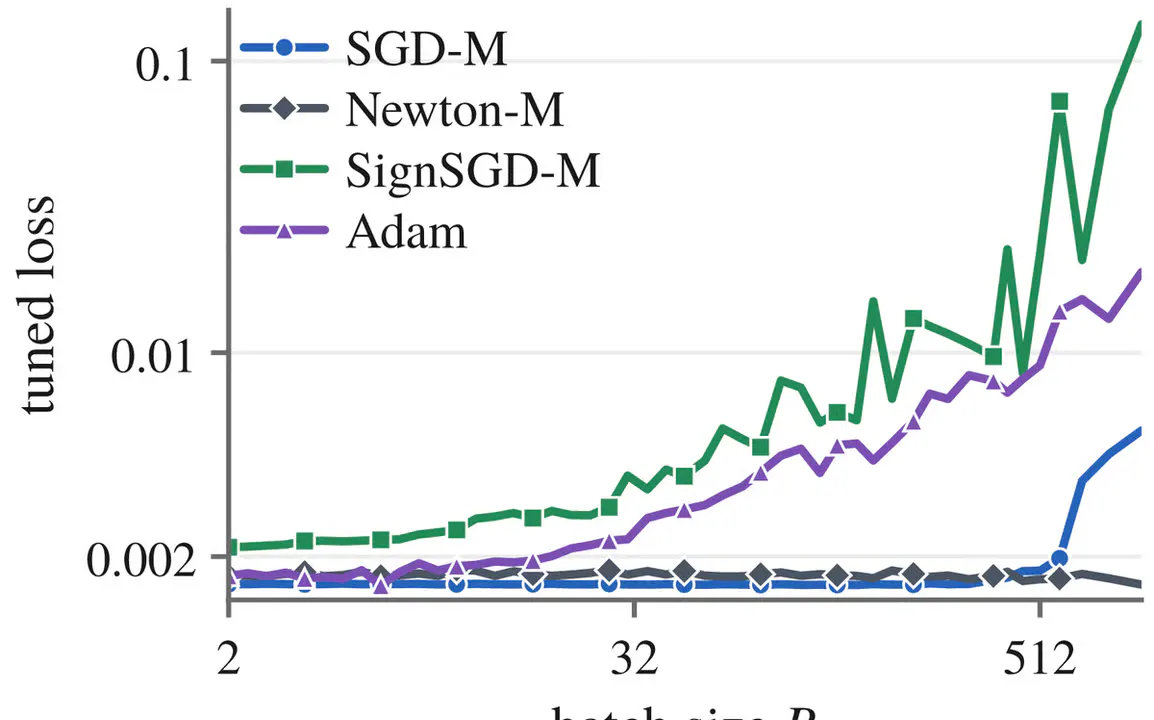
Optimizer Rankings Flip as Batch Size Grows, Study Warns ML Engineers
A new study finds no principled hyperparameter scaling rule consistently preserves optimizer performance across batch sizes, undermining single-batch benchmarks.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new study finds no principled hyperparameter scaling rule consistently preserves optimizer performance across batch sizes, undermining single-batch benchmarks.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.