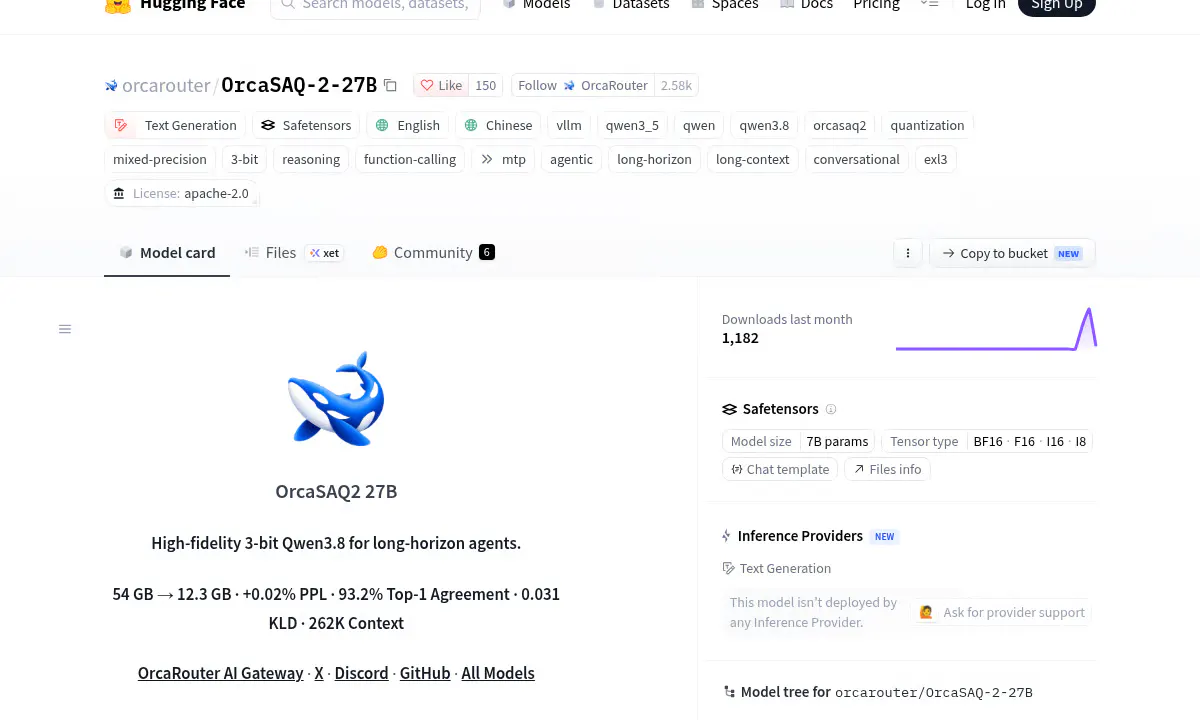
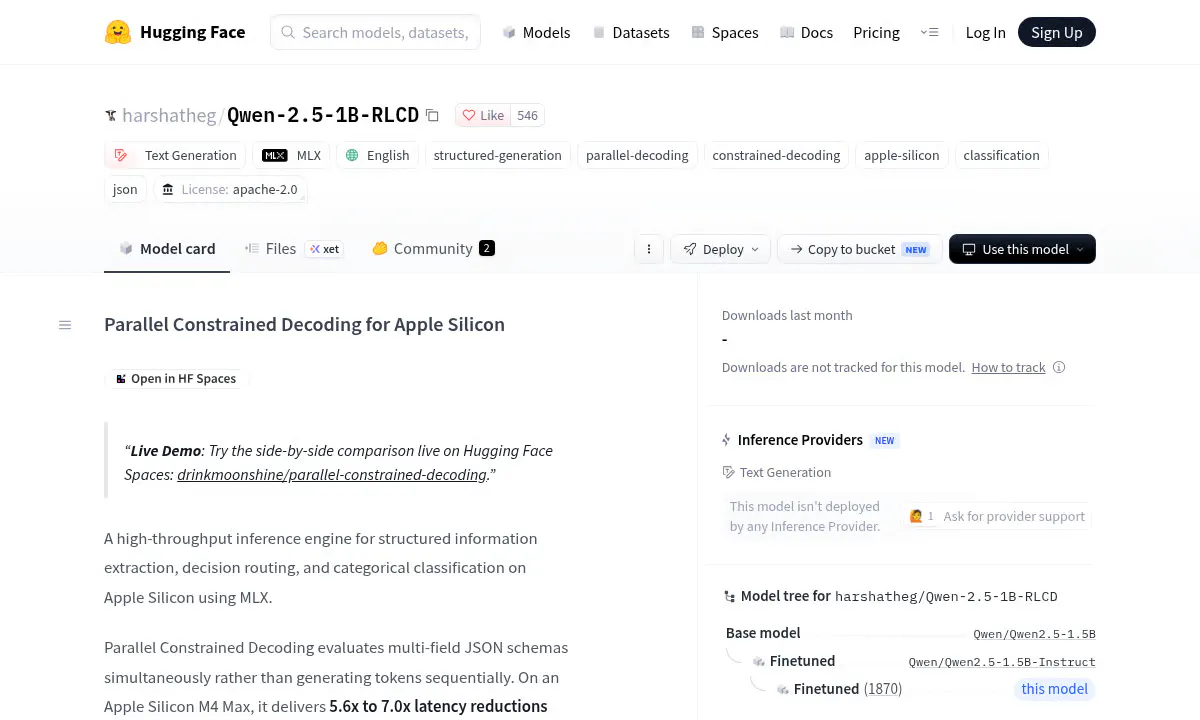
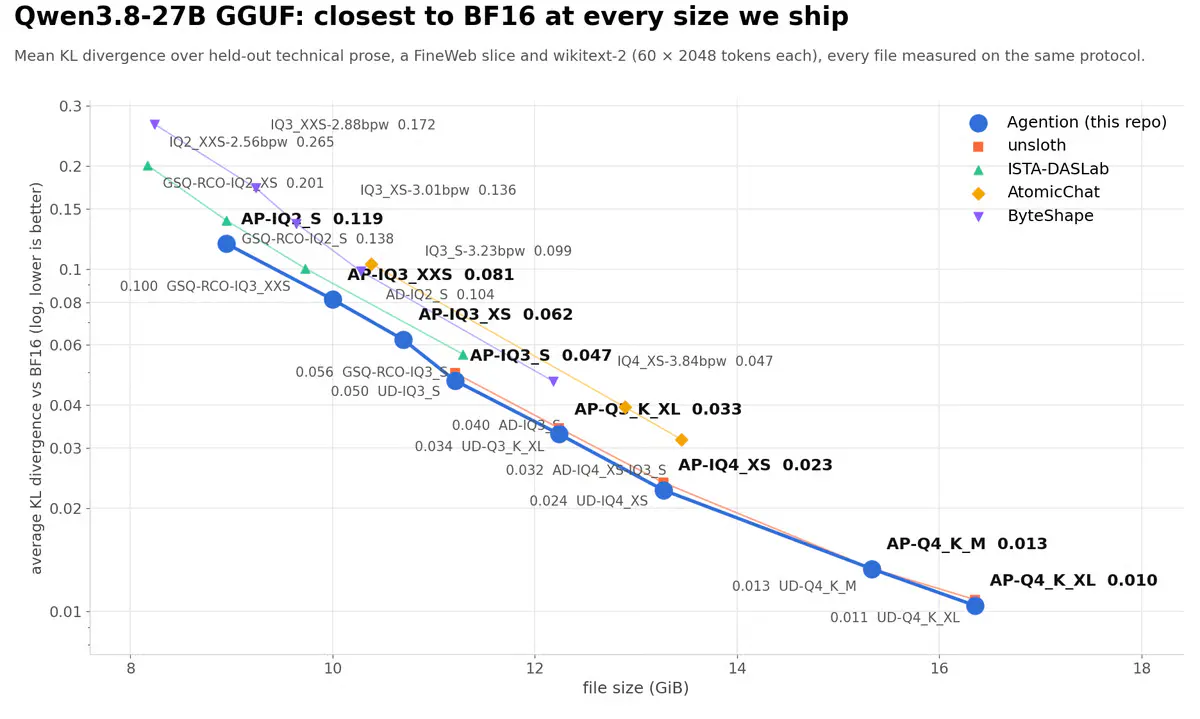
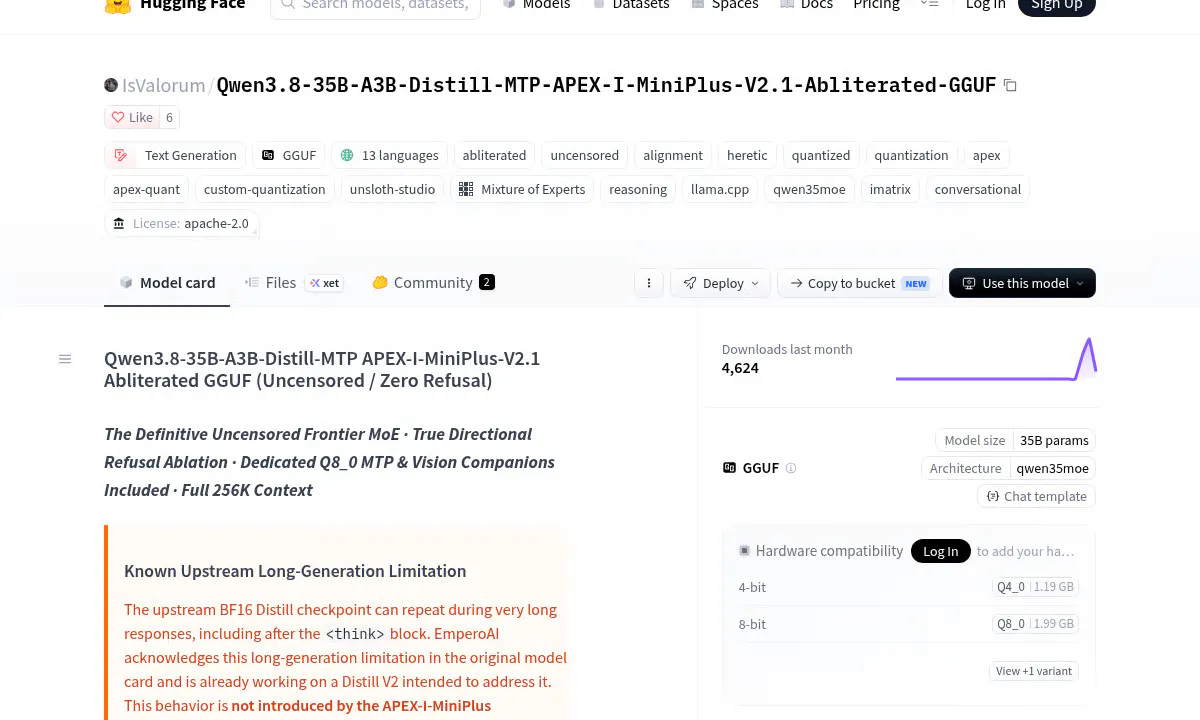
←Back to NewsAI News/LlmsmodelLlmsGpusOrcaRouter's OrcaSAQ2 Squeezes a 27B Coding Agent Into 16 GB GPUsOrcaRouter shrinks Qwen3.8-27B from 54GB to 12.3GB using 3-bit mixed-precision quantization, keeping 70% SWE-bench Verified on a single 16GB GPU.SourceAlphaSignalPublishedSep 24, 2026, 3:44 AMAuthorAlphaSignal NewsroomRead1 min readOrcaRouter shrinks Qwen3.8-27B from 54GB to 12.3GB using 3-bit mixed-precision quantization, keeping 70% SWE-bench Verified on a single 16GB GPU.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsAlphaSignal · modelQwen-2.5-1B-RLCD Scores JSON Fields in Parallel, Running 7x Faster on Apple SiliconAlphaSignal · modelSolo Developer Shrinks Qwen3.8-27B to 16 GiB With 10% Less DistortionAlphaSignal · modelIsValorum Squeezes a 35B Open-Source Qwen3.8 Model Into 14.65 GB