Back to News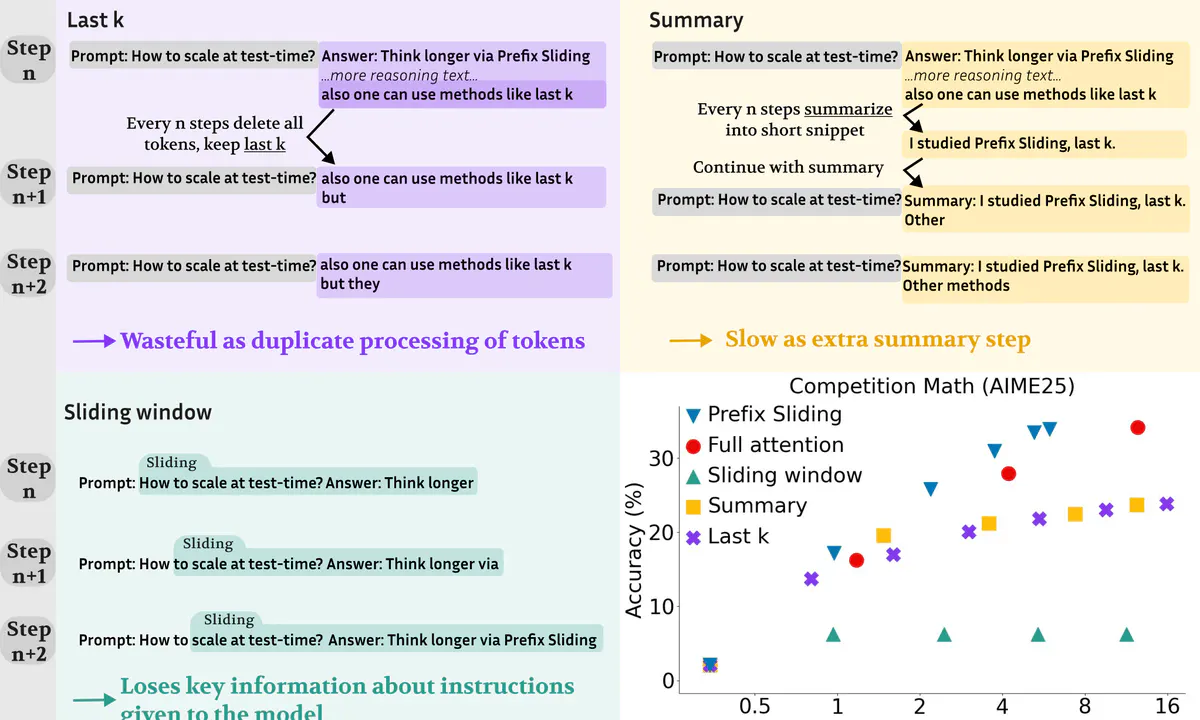
Prefix Sliding Cuts Reasoning AI Memory Costs With a 3x Speedup
A new method throws away most of a model's own reasoning trace mid-thought, cutting memory to a fixed cap and running inference 3x faster.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new method throws away most of a model's own reasoning trace mid-thought, cutting memory to a fixed cap and running inference 3x faster.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report