hermes-ai.netis an unofficial, independent community guide to Hermes Agent, with localized docs, release notes, desktop notes, and practical setup paths.
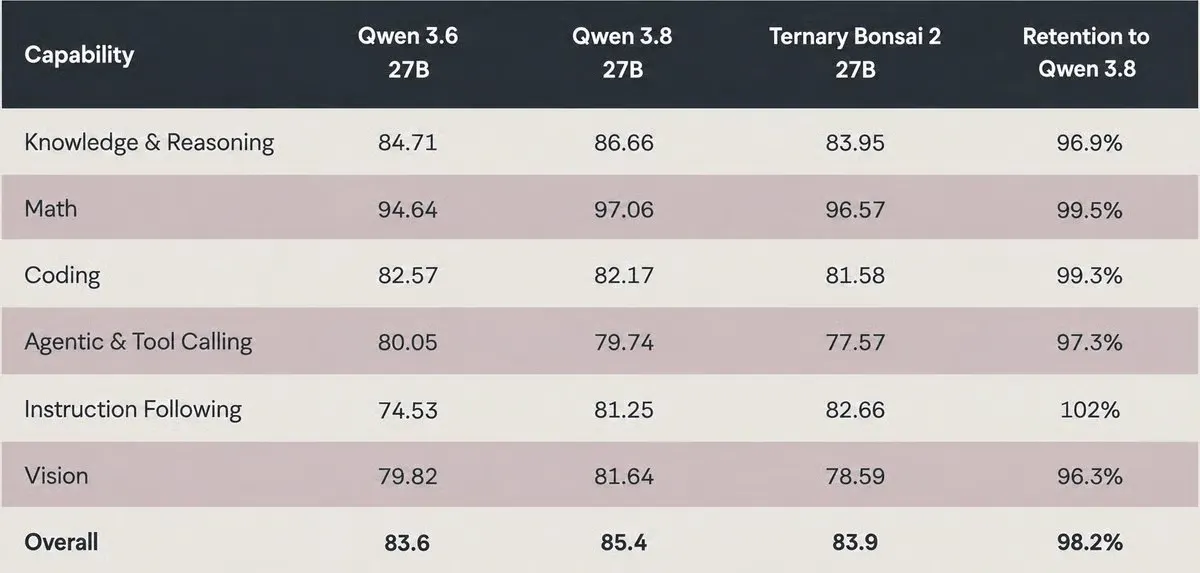
PrismML Squeezes Qwen3.8 27B Into 5.9 GB With 98% Performance Retained
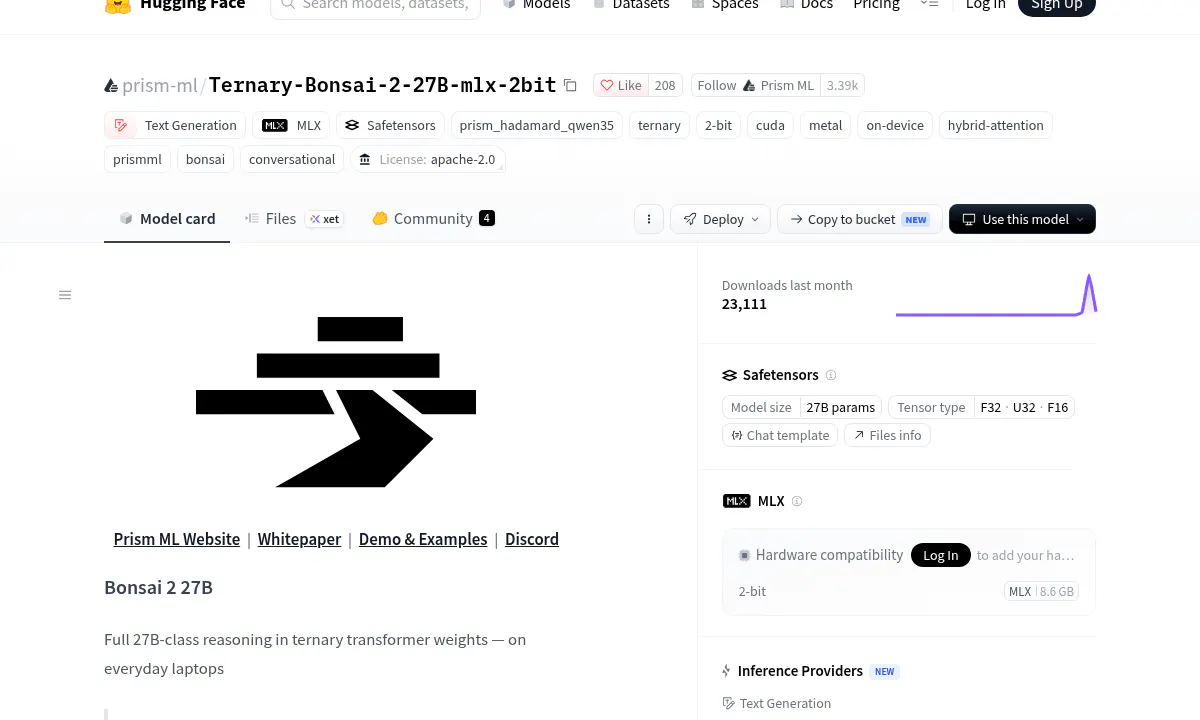
PrismML's ternary-quantized 27B model retains 98.2% of full-precision Qwen3.8 27B performance in a 5.9GB footprint, hitting 143 tokens/sec on an RTX 5090.
Source
PrismML
Published
Author
AlphaSignal Newsroom
Read
1 min read
PrismML's ternary-quantized 27B model retains 98.2% of full-precision Qwen3.8 27B performance in a 5.9GB footprint, hitting 143 tokens/sec on an RTX 5090.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.