Back to News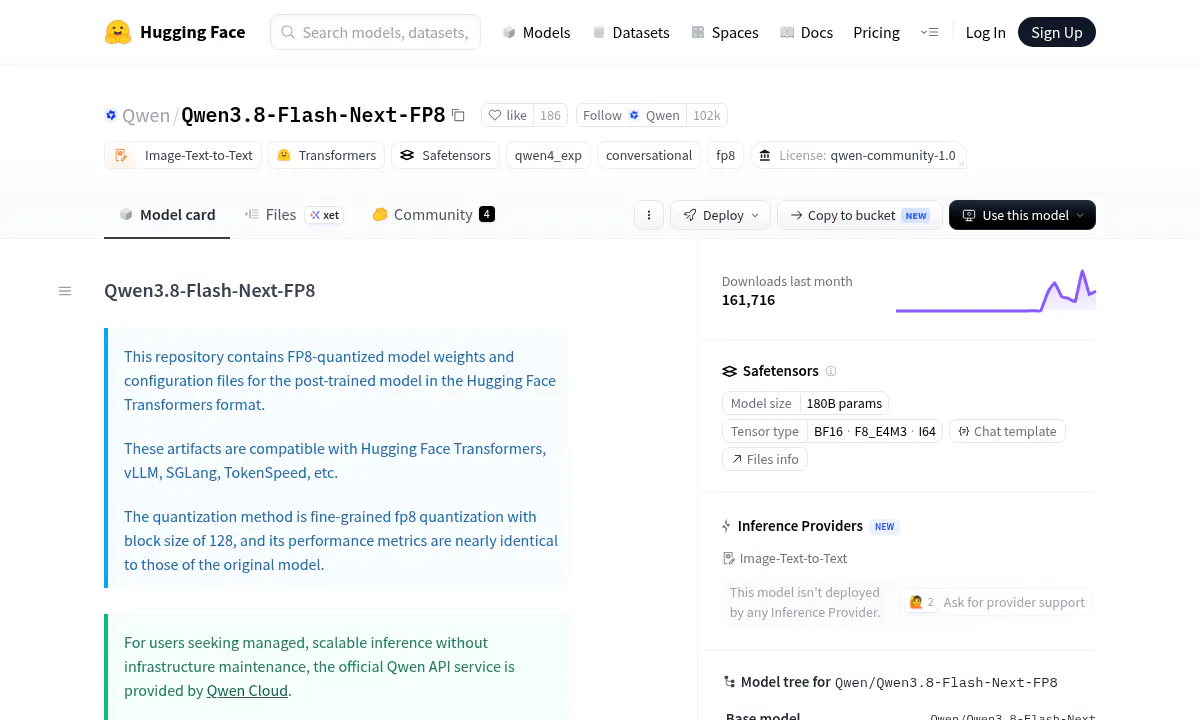
Qwen Drops Qwen3.8-Flash-Next, a 125B Open Model That Activates Only 6B Parameters
Qwen ships an FP8 preview of the architecture behind Qwen4, pairing sparse attention, n-gram embeddings and 125B params with 6B active.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
Qwen ships an FP8 preview of the architecture behind Qwen4, pairing sparse attention, n-gram embeddings and 125B params with 6B active.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report