Back to News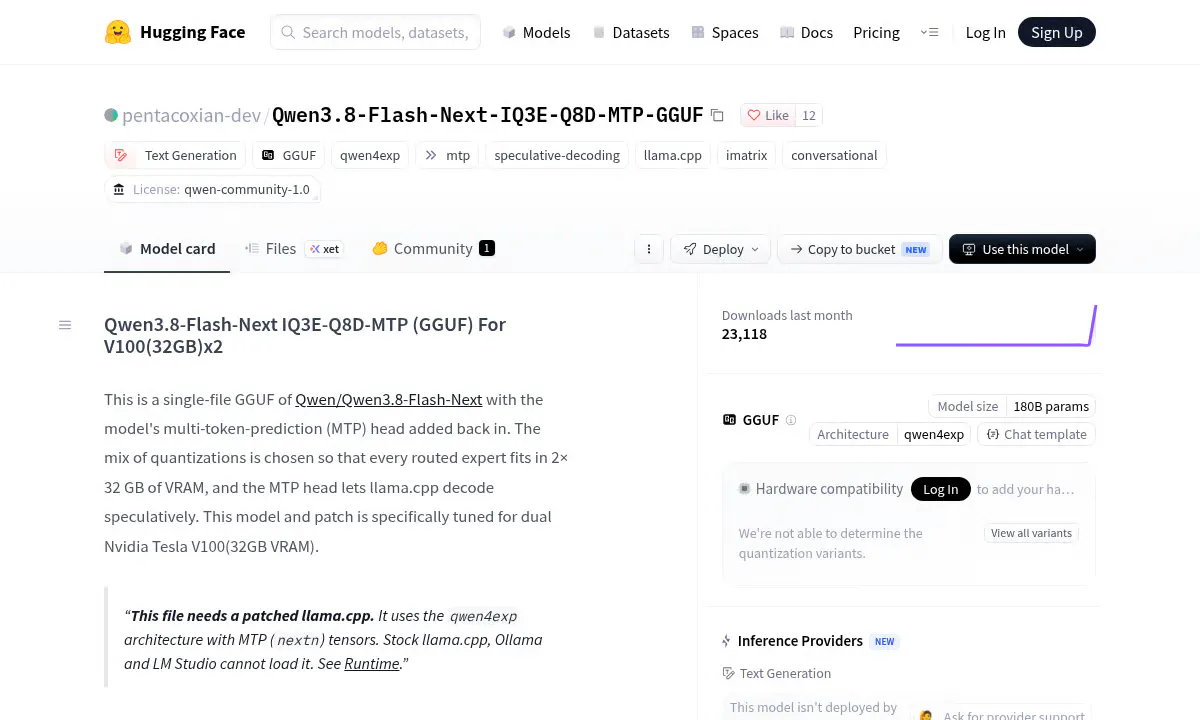
Qwen3.8 Flash Next Runs a 125B Model on Dual V100s at 120 tok/s
A community GGUF pack turns two aging V100 GPUs into a 180B multimodal Qwen3.8-Flash-Next server with 256K context and 120+ tok/s decode.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A community GGUF pack turns two aging V100 GPUs into a 180B multimodal Qwen3.8-Flash-Next server with 256K context and 120+ tok/s decode.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report