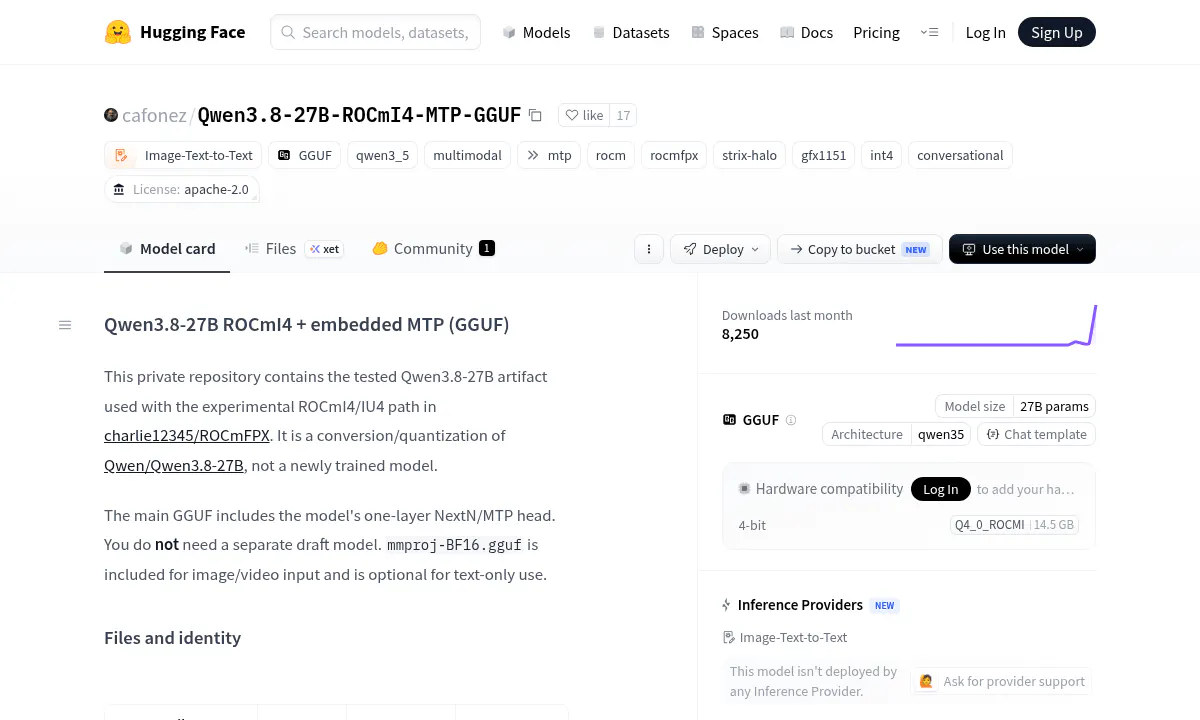
Qwen3.8 Hits 49 Tokens per Second on AMD's Budget APU
A community quantization pairs a 27B Qwen model with multi-token prediction and AMD's IU4 matrix path, hitting ~49 tokens per second on a single Strix Halo APU.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A community quantization pairs a 27B Qwen model with multi-token prediction and AMD's IU4 matrix path, hitting ~49 tokens per second on a single Strix Halo APU.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.