hermes-ai.netis an unofficial, independent community guide to Hermes Agent, with localized docs, release notes, desktop notes, and practical setup paths.
Red Hat Shrinks GLM-5.3-Flash to 4-Bit for NVIDIA Blackwell GPUs
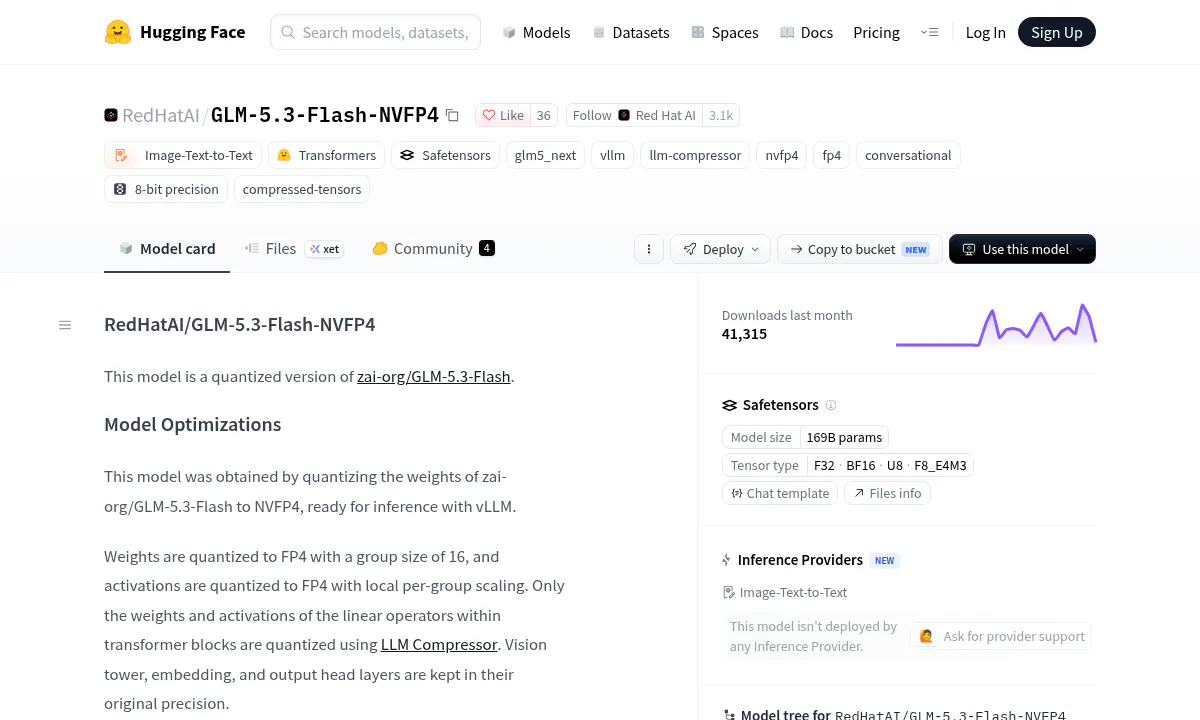
Red Hat AI shipped an NVFP4 quantization of Z.ai's 320B GLM-5.3-Flash, shrinking the model to run on vLLM with FP4 activations while holding reasoning benchmarks near the original.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
Red Hat AI shipped an NVFP4 quantization of Z.ai's 320B GLM-5.3-Flash, shrinking the model to run on vLLM with FP4 activations while holding reasoning benchmarks near the original.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.