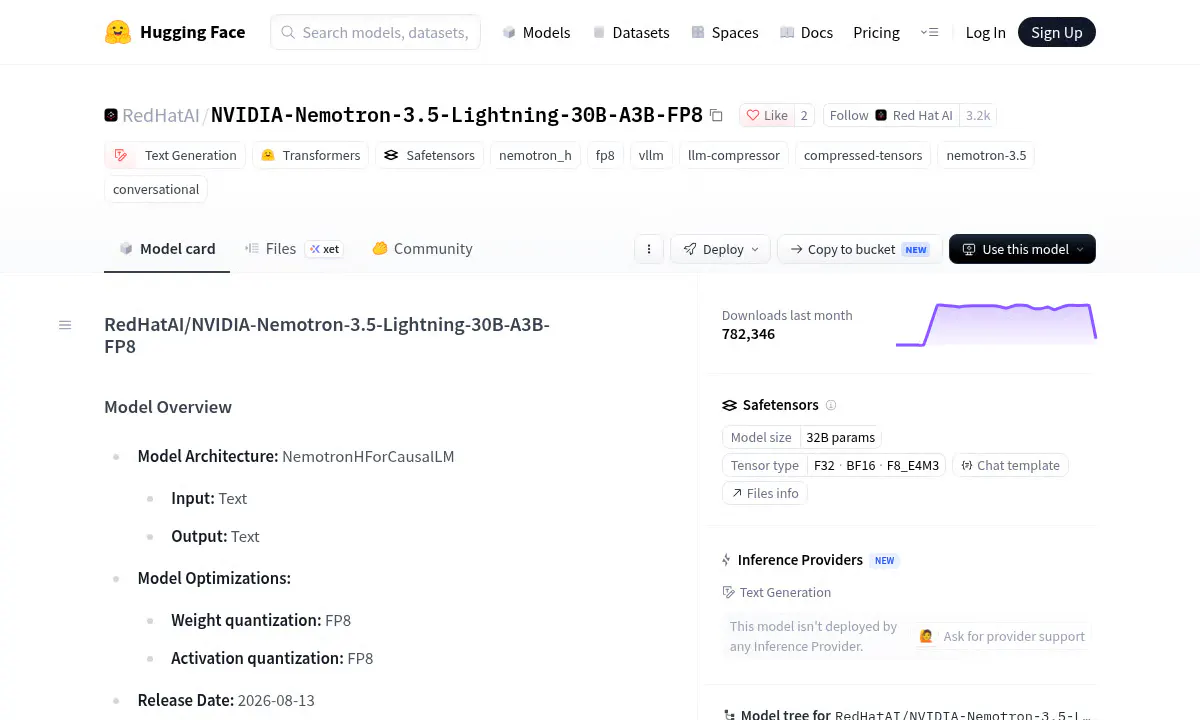
Red Hat Shrinks Nemotron 3.5 Lightning's 30B Agent Model by Half With FP8
Red Hat AI shipped an FP8 build of NVIDIA's hybrid Mamba-MoE Lightning model, halving memory while keeping the 1M-token agent workhorse on a single GPU.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
Red Hat AI shipped an FP8 build of NVIDIA's hybrid Mamba-MoE Lightning model, halving memory while keeping the 1M-token agent workhorse on a single GPU.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.