hermes-ai.netis an unofficial, independent community guide to Hermes Agent, with localized docs, release notes, desktop notes, and practical setup paths.
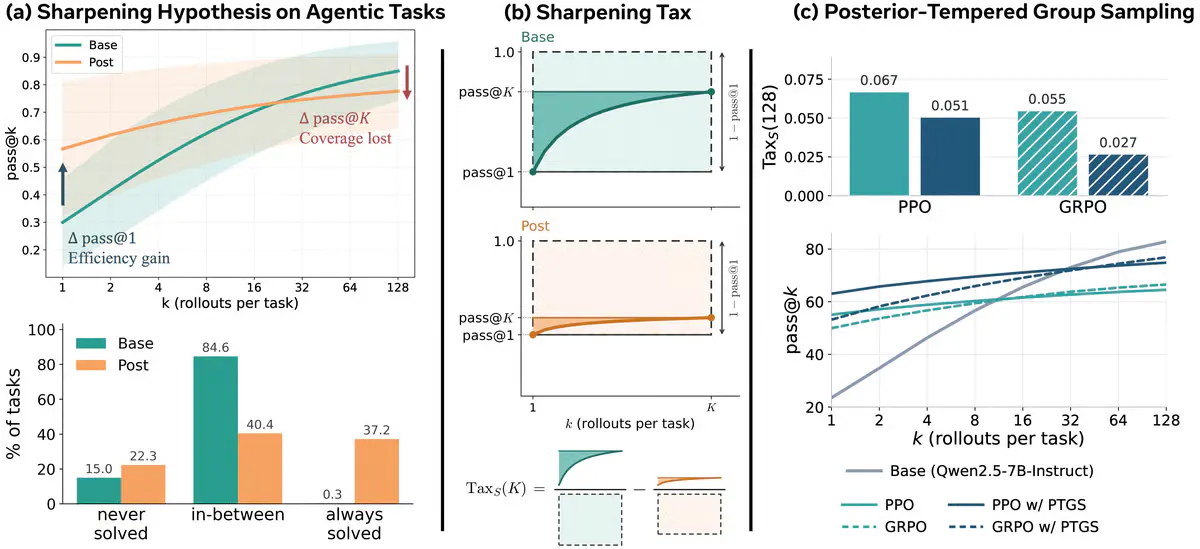
Sharpening Tax Shows How RL Post-Training Quietly Kills AI Agent Retries
A new study finds reinforcement learning post-training trades solution coverage for consistency on agentic tasks, and proposes an adaptive sampler that avoids the hit.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new study finds reinforcement learning post-training trades solution coverage for consistency on agentic tasks, and proposes an adaptive sampler that avoids the hit.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.