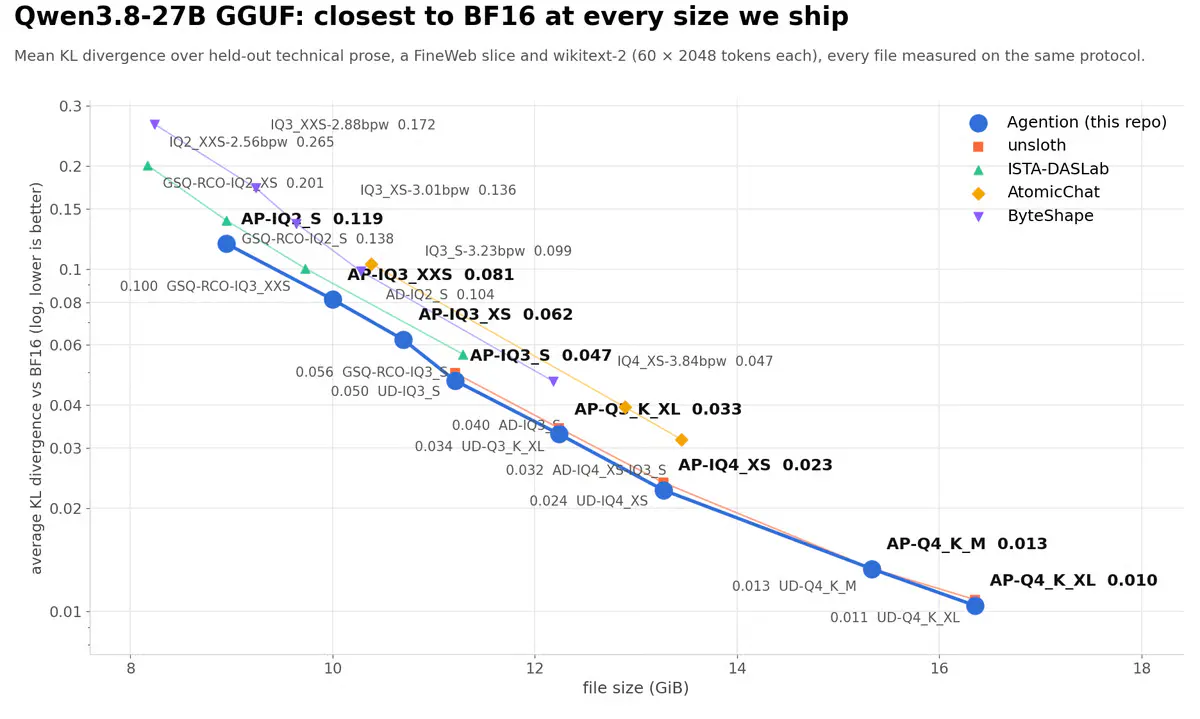
←Back to NewsAI News/LlmsmodelLlmsGpusSolo Developer Shrinks Qwen3.8-27B to 16 GiB With 10% Less DistortionA one-person shop is shipping GGUF quants of Qwen3.8-27B that measurably beat Unsloth and ISTA-DASLab byte-for-byte, with no fork required.SourceAlphaSignalPublishedSep 22, 2026, 4:21 PMAuthorAlphaSignal NewsroomRead1 min readA one-person shop is shipping GGUF quants of Qwen3.8-27B that measurably beat Unsloth and ISTA-DASLab byte-for-byte, with no fork required.Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.Read original report ↗Next readsAlphaSignal · modelQwen-2.5-1B-RLCD Scores JSON Fields in Parallel, Running 7x Faster on Apple SiliconAlphaSignal · modelIsValorum Squeezes a 35B Open-Source Qwen3.8 Model Into 14.65 GBAlphaSignal · modelQwen3.8 Squeezed to 11.8 GB Runs at 150 Tokens per Second