Back to News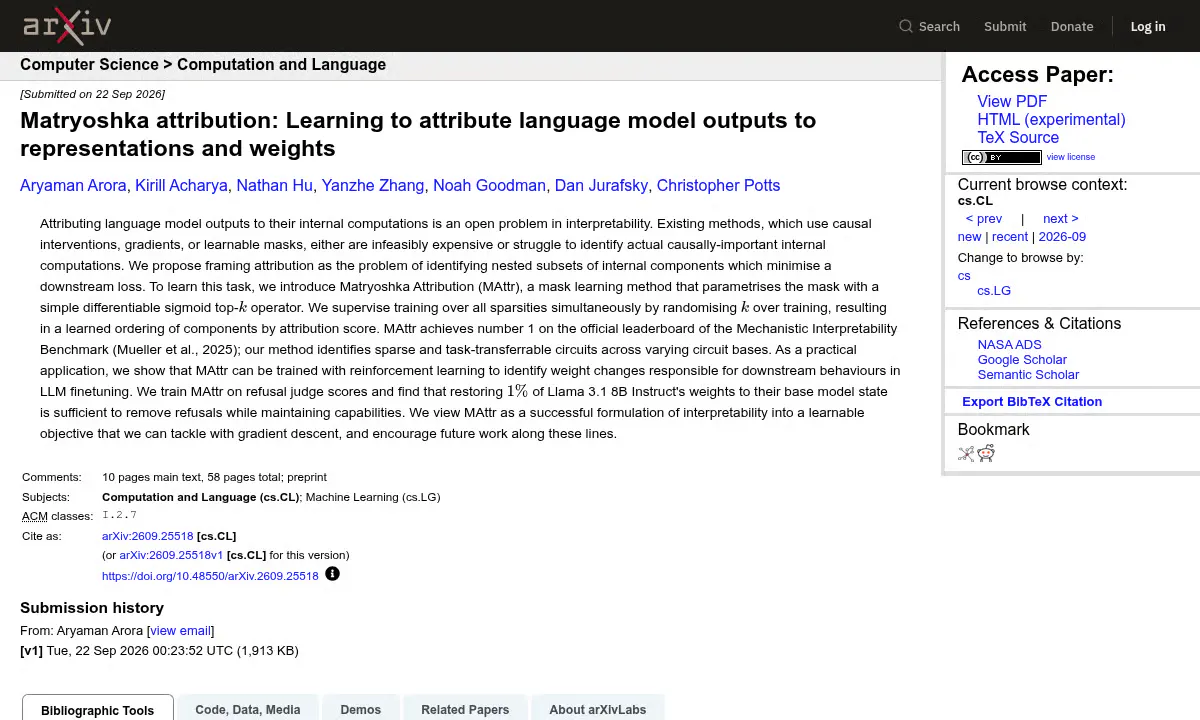
Stanford's MAttr Tops AI Interpretability Benchmark by Nearly 3x
A new interpretability method learns which internal components matter for a behavior, and pinpoints just 1% of Llama 3.1 weights driving refusals.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new interpretability method learns which internal components matter for a behavior, and pinpoints just 1% of Llama 3.1 weights driving refusals.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.
Read original report