Stanford's SOMA Slashes AI Training Noise by Sharding Models Into Expert Shards
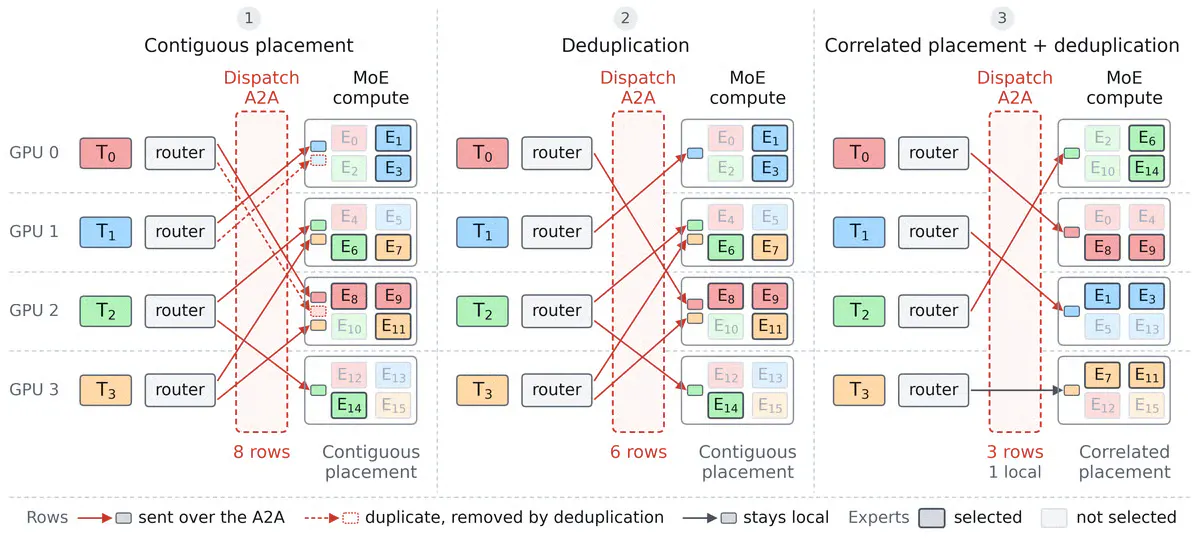
A new architecture called SOMA shards models into independent experts, slashing the gradient variance that has blocked zero-order methods from scaling to pretraining.
Source
AlphaSignal
Published
Author
AlphaSignal Newsroom
Read
1 min read
A new architecture called SOMA shards models into independent experts, slashing the gradient variance that has blocked zero-order methods from scaling to pretraining.
Reporting is indexed from AlphaSignal. Rights remain with the original publisher and cited sources.